Learning Jazz Pianist Style with Cross-Attention Conditioning
We start from Aria (Bradshaw et al., ISMIR 2025;
以下正文同步自 Hacker News,版权归原站所有,已转换为易读排版。
We start from Aria (Bradshaw et al., ISMIR 2025; code), a 16-layer transformer pretrained on a large corpus of piano MIDI. Into each of its last eight layers we insert a cross-attention block: the music attends to a small learned embedding for the chosen pianist, four vectors per pianist. A learned gate scales what the block adds, starting at 0.1, so fine-tuning begins from Aria’s own behaviour and learns how much to listen. Because the embedding is attended to at every step, the conditioning does not fade as generation goes on, the way a prompt prefix does.
x
Self-attention
Add & norm
Cross-attention
×g
Add & norm
Feed-forward
Add & norm x′ keys, values
pianist embedding 4 learned vectors
One of the eight adapted layers. The new pieces are in amber: the music supplies the queries, the pianist embedding supplies keys and values, and the gate g scales the result before it joins the residual stream.
Measuring style
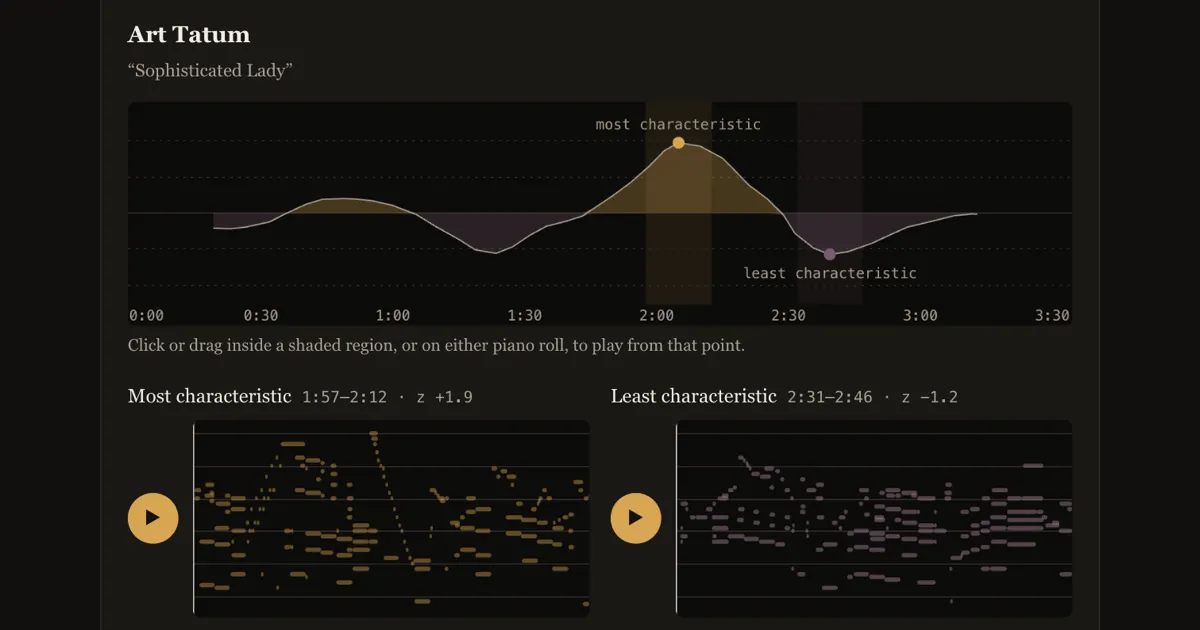
How can we tell whether the model has learned a pianist’s style? The standard yardstick for a generative model, perplexity on held-out music, turns out to be nearly blind to it: given the real preceding notes, the next one is predictable whoever is playing, so conditioning barely moves the score. Style shows up when the model generates freely and has to stay in character on its own output. So instead we let it play, and ask a pianist classifier who it sounds like. Agreement is how often the classifier names the intended pianist, in windows slid along each continuation.
Perplexity (lower is better) barely separates the two fine-tuned models; agreement nearly doubles. Continuations are 4096 tokens from 256-token prompts; chance agreement is 8%.
The paper has the details: per-pianist results, the mismatch experiment (prompting with one pianist and conditioning on another), memorization checks, and a from-scratch classifier that confirms the transfer result.
Everything here is MIDI, rendered in your browser on a sampled piano. The model was trained on automatic transcriptions of commercial recordings, so dynamics and pedalling are approximate, and the rendering is plainer than the records.
The twelve pianists were chosen for separability: they are the twelve of PiJAMA’s thirty whose recordings a pretrained model already tells apart most easily. Within them the model imitates some far better than others — across the paper’s evaluation, continuations were attributed to the intended pianist 96% of the time for Hank Jones and Dick Hyman, but only 29% for Cedar Walton.
The scored takes are selected, not copied. They are samples from the corpus of generated music that the paper’s synthetic-only classifier learned from; for each pianist we show the two highest-scoring of eight candidates. Their prompts come from the training recordings, and the paper checks that the continuations do not copy them: they resemble their closest training performance less than real held-out performances do.
The scores come from a classifier, not from listeners. It is a strong one (98.8% of held-out songs), but it has habits: many of its mistakes on generated music land on Dick Hyman — fitting, perhaps, for a pianist who made a career of playing in everyone else’s style. A listening study is the natural next step.
Built on Aria and the PiJAMA dataset. Code, checkpoints, and evaluation scripts: on GitHub.
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。