Streaming a coding agent's UI in Flutter: what broke and how we fixed it
I want to talk about the dumbest-looking decision in our Flutter app, because I've gone back and forth on it more times than I'd like to admit, and because defending it taught me most of what I now know about how Flutte…
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
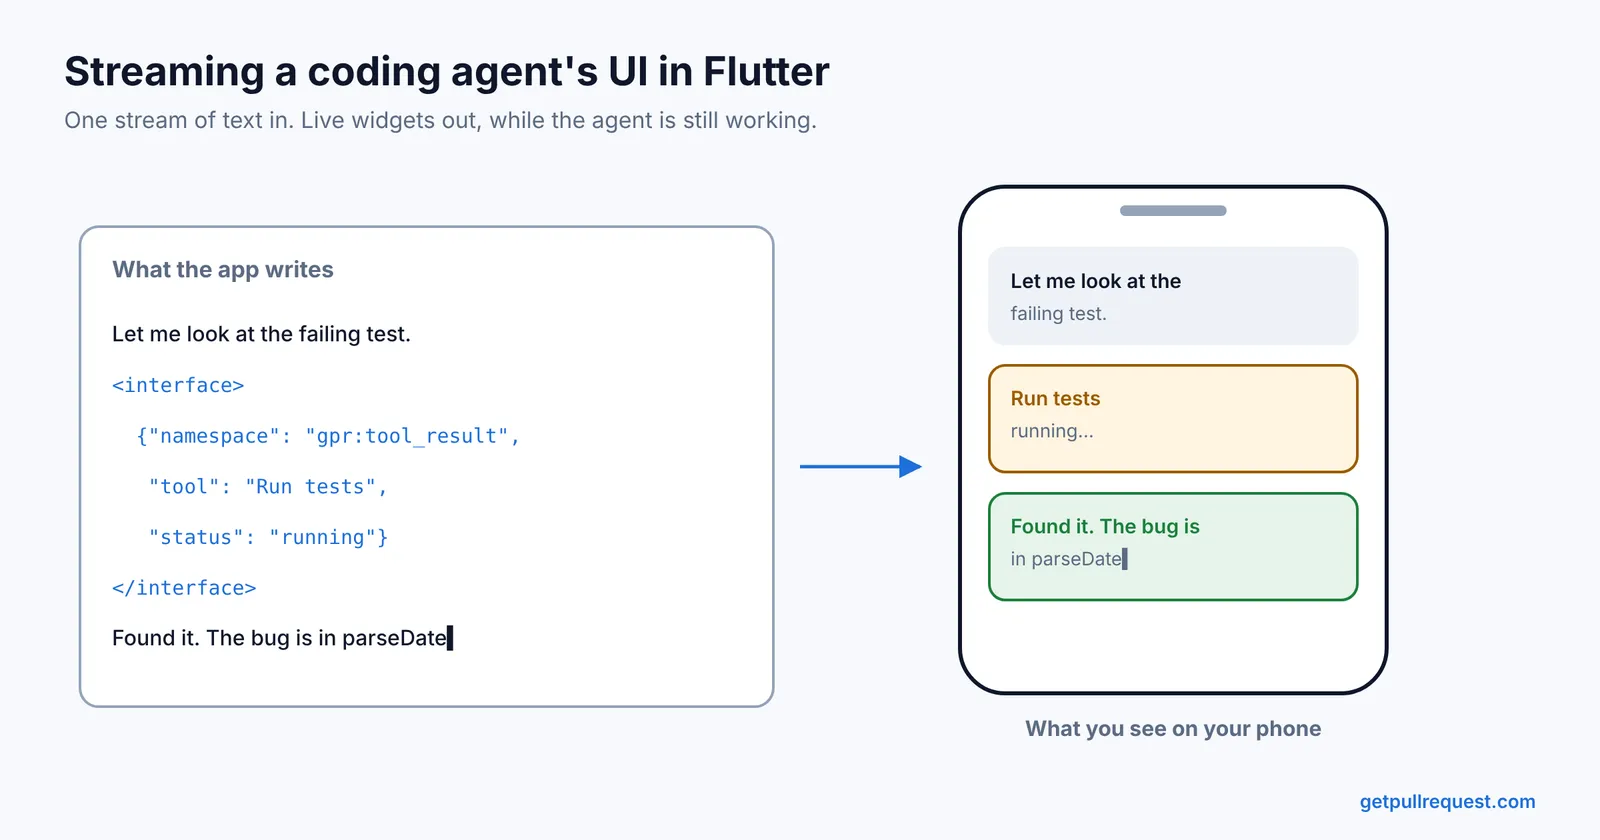
I want to talk about the dumbest-looking decision in our Flutter app, because I've gone back and forth on it more times than I'd like to admit, and because defending it taught me most of what I now know about how Flutter behaves under pressure. Some context first. We build GetPullRequest . A coding agent (Claude Code, Codex, Cursor, whatever you already pay for) runs on your own machine, and you watch it and talk to it from your phone. The phone app is Flutter. The agent speaks the Agent Client Protocol , which means everything it does arrives as nicely typed JSON-RPC frames: here's a piece of my reply, here's a piece of my reasoning, I've started a tool, that tool's status changed. Typed frames. Clean discriminated unions. Exactly what you'd want. And the first thing our app does with them is flatten them into one long string. The string Every agent turn gets its own Stream<String> . The phone app writes to this stream, not the agent. The agent never sees any of this. It just sends normal ACP messages. When a message arrives, one Dart class in the app ( AcpChatService ) decides what to do with it. The agent's reply text goes into the stream as it is. Everything else, like a tool card, a diff, terminal output, a permission prompt or the agent's thinking, gets wrapped by the app in a small <interface> tag with some JSON inside. So the stream looks like this: Let me look at the failing test. <interface>{"namespace":"gpr:tool_result","tool_call_id":"t7","tool":"Run tests","status":"running"}</interface> Found it. The bug is in parseDate. Then, on the rendering side, a tag parser splits the string back into text and tags. A streaming JSON parser reads the properties inside each tag. And a registry looks at the namespace (here gpr:tool_result ) and picks the widget to show. So we take structured data, turn it into text, and then parse the text back into structured data, all inside the same app. If I saw this in a code review with no context, I would ask what happened. Why we didn't use Flutter's GenUI Flutter does have its own package for this, called GenUI . We tried it first. We had to stop using it for one reason: it only drew the UI after the model's full response had arrived and been parsed. In a normal chat app, that means looking at a spinner for a few seconds. For a coding agent whose turn can run for twenty minutes, it doesn't work at all. When the agent starts running a tool, you want to see the tool card right away, not after the agent is finished. The GenUI team knew this. Their own README lists "Streaming UI: Support for progressively rendering UI components as they stream from the LLM" under things they're thinking about , and it has been on that list since August 2025. It's not an easy thing to add. GenUI would need a JSON parser that can handle half a response. It would need placeholders for widgets that refer to other widgets that haven't arrived yet. And it would need fields in the right order so the top-level widget shows up first. Other Flutter developers hit the same wall. When GenUI was first shared on r/FlutterDev , one developer wrote that "the only pain point I've run into is being able to stream the widgets, doing real-time incomplete json parsing is a PIA." Where the <interface> syntax comes from We didn't invent the <interface> tag. We took it from streaming_gen_ui , a small Flutter package that its author introduced on r/FlutterDev as "a simpler and streaming version" of GenUI. Its README describes our problem with GenUI almost word for word: "Most generative UI packages require you to wait for the complete JSON payload before decoding and popping the final widget tree onto the screen." The idea is simple. A model writes normal text, and when it wants a widget, it writes a tag with JSON inside: <interface>{"namespace":"gpr:code_block","language":"dart","code":"..."}</interface> The package reads the stream as it arrives. It uses llm_tag_parser to separate the text from the tags, and llm_json_stream to read the JSON inside a tag before the tag is complete. As soon as the namespace field arrives, it picks the matching widget and shows it. The rest of the fields fill in as they stream. Both parsers come from the same author, and we use llm_json_stream directly in our app too. We first used this to let a language model write UI directly. You can still see that in our config, which has instructions for the model like "ALWAYS use gpr:code_block instead of markdown code fences" . When we moved to ACP agents, we already had a renderer that could grow a tool card or a code block line by line. So instead of building a new one, we made the app write the agent's messages in the same <interface> format. What we changed to make it work for coding agents streaming_gen_ui was built for a chatbot-style reply: the user asks something, the model answers in a few seconds, and the answer has a handful of widgets in it. A coding agent works very differently. One turn can run for an hour. In that time the agent reads files, runs commands, edits code and runs tests, and every one of those steps shows up as a card. Between those steps it also thinks out loud. That reasoning streams into its own thinking widget, which stays open while the agent is thinking and folds itself away as soon as the agent starts replying or runs a tool. A single turn can end up with hundreds of tool cards, long terminal output and a few very large diffs, all streaming in while you scroll. The package's README is also honest that it "does not manage conversations, pipelines, or tooling", and for us, tooling is most of the screen. So we keep our own copy of streaming_gen_ui in our repo and changed a few things. It rebuilt on every chunk. The original calls notifyListeners() every time a piece of text arrives. With an agent streaming fast, that meant rebuilding many times a second. Our copy groups these into one notification per microtask. The logic is a single flag. When a chunk arrives, we check if a notification is already scheduled. If it is, we do nothing. If not, we set the flag and schedule one with scheduleMicrotask . When that microtask runs, it clears the flag and calls notifyListeners() once. bool _notifyScheduled = false; void _scheduleNotify() { if (_notifyScheduled) return; // one is already on the way _notifyScheduled = true; scheduleMicrotask(() { _notifyScheduled = false; notifyListeners(); }); } A microtask runs as soon as the current piece of Dart code finishes, before the event loop moves on to the next event or the next frame. So if the parsers push twenty chunks in one go, all twenty are added to their blocks first, and the listeners hear about it once. Nothing is delayed by a timer, and the screen never shows a state that is out of date. It drew the whole reply as one widget. The original puts every block of a reply inside one Column . For a short answer that's fine. For a long turn, Flutter had to build all of it whenever any part was on screen. Our copy can build one block at a time, so each block becomes its own row in the chat list, and Flutter only builds the rows you can see. The tags were written by a model, not by us. In the original, the model writes the tags. In our app, the agent never sees them. The app's AcpChatService receives the agent's ACP messages and writes the tags itself: one for each tool card, diff, terminal output or permission prompt. The agent's reply text goes in as normal markdown. Tool calls change after they start. The original only adds to the stream. It never goes back and changes a widget. But a tool call starts as "running" and then gets updated several times. We had to build a way to update a card that is already on screen. More on that below. We dropped what we didn't need. The package ships with many themed widgets, like weather cards and product results. We removed them and registered our own gpr: widgets instead. Why the string stayed Turning typed messages back into a string still looks odd. But we kept it for one reason I'm really happy about: the saved history uses the same string. When you open a session again the next day, the saved transcript is the same markup, drawn by the same widgets. We don't have one renderer for live sessions and another for history that slowly drift apart. It also helps when a turn ends. We fetch the saved version of that turn and swap it in for the live one. If the network dropped a message somewhere, say while you were in a tunnel, the missing part just appears. You never notice. I'm still not sure this is worth the strangeness. Some days I think we should remove it and draw the typed messages directly. Then I think about maintaining two renderers, and I change my mind. If GenUI gets proper streaming one day, I would seriously think about moving back. With the renderer working, the next problem showed up quickly: the text itself. Text gets cut in the wrong places The problem with streaming text is that it never gets split where you want. A chunk can end in the middle of a word, in the middle of a markdown table, or in the middle of the three backticks that start a code block. Here's a simple example. Say the agent wants to send this reply: Here's the fix: dart final total = price * qty; It doesn't arrive in one piece. It might arrive as three chunks like these: chunk 1: "Here's the fix:\n`" chunk 2: "``dart\nfinal total = pri" chunk 3: "ce * qty;\n" If you render the text after every chunk, this is what the user sees: After chunk 1, a stray backtick at the end of the sentence. After chunk 2, dart final total = pri as plain text, because there is no complete code block yet. After chunk 3, the text suddenly turns into a proper code block with syntax highlighting. So for a moment the screen shows something that was never in the reply. With short replies it's a flicker. With a long code block streaming for several seconds, it looks broken. I knew this in theory, but I only really understood it after watching it happen on my own phone, in a long code block, over and over. We fixed this with a small class called AgentMessageTextAssembler . It watches the reply as it streams in. As soon as it sees a complete opening fence, like dart , it starts a code block tag and sends the code into it bit by bit. So the code block appears straight away and fills in as the code arrives. The tricky part is the end of each chunk. If a chunk ends with one or two backticks, they might be the start of a fence. So the assembler holds back just those characters until the next chunk arrives and makes it clear. final ticks = _trailingBacktickCount(text); if (ticks == 1 || ticks == 2) return ticks; // not sure yet, keep these back JSON code blocks are harder, because agents often forget to close them. For those, the assembler counts brackets and quotes. If the JSON looks complete and the next text looks like a normal sentence, it stops waiting for a closing fence that will never come. How does it decide that the next text "looks like a sentence"? A regex checks if it starts with a letter, # or * . It's a rough rule, but it works. Plain markdown had its own version of this. Our chat renders the agent's text one line at a time, so you can tap any line and comment on it. Most markdown doesn't care. But some of it only works when the lines are read together. Here are the three cases that bit us. A table. The agent writes: | File | Change | |-------------|----------| | auth.dart | +12 -3 | | login.dart | +40 -18 | A table only works when all its rows are read together. We were reading one row at a time, so instead of a neat table, the user saw four lines of plain text with | symbols scattered through them. A code block. The agent writes: dart final user = await auth.signIn(); print(user.name); The three backticks at the top and bottom tell markdown where the code starts and ends. But we were reading one line at a time, so each line had no idea it was part of a bigger code block. Instead of one code box with both lines i
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。