The AI cost of JavaScript frameworks
Posted October 28, 2026 by Nolan Lawson in Web, AI.
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
Posted October 28, 2026 by Nolan Lawson in Web, AI.
One of my pet peeves with the web development community is that so many of the decisions we make are vibes-based. Frameworks are “blazing fast,” tools will “supercharge” your development, the right abstraction will benefit both you and your users (DX and UX all in one!). All of this breathless boasting is usually offered with zero evidence. Alex Russell has called this “frontend’s lost decade”, Baldur Bjarnason has called programming a pop culture, and I’ve tried to counter this trend in my blog with facts and benchmarks (at my best, anyway).
For a long time it seemed like our community’s allergy to evidence was driven by the desire for greater DX. In other words, devs just liked the way it felt to type JSX in React, and the arguments promoting React or related tools (“the virtual DOM is fast!”) were largely post-hoc rationalizations to justify those initial gut feelings. (Jonathan Haidt would likely agree with this assessment.)
But in the agentic era, when developers are no longer typing code by hand and are thus less constrained by DX, I still see vibes ruling the day (and not just in the sense of “vibe-coding”). Frontends are rewritten because some framework or another is “better for agents.” (Did anyone think to ask the agents?) The resulting code is “faster,” the agents make “fewer mistakes,” etc. Once again, these claims are often made without evidence. Whenever I read one of these accounts, I think to myself, “Where are the benchmarks?”
Well I got curious, so I wrote a benchmark. The structure of this benchmark is pretty straightforward:
The app is fairly simple: you’ve got a list of Pokémon with their types, moves, and data from various games. You can search, filter, etc.:
I should start off with some caveats: this is not a perfect experiment. This app represents only one holotype – it’s a relatively content-based site with little interactivity, closer to a Wikipedia than a Figma, GMail, etc. That said, I had to choose some app to build, and this one is at least easy to understand at a high level, and relatively straightforward to spec out and test.
To try to even the playing field, I had each framework/meta-framework use the official MCP or skills for that tool. I wanted to avoid accusations of “this framework is not well-represented in the training data, that’s why we built our MCP, we expect people to use it,” etc. I also didn’t over-specify the exact architecture to use (e.g. SSR vs CSR), nor did I specify that the app should be as performant as possible. I simply gave the spec to Opus 5.5 with high effort and told it to use the latest version of the given framework. Each agent ran in a sandbox and without any knowledge that it would be tested in Lighthouse on performance and accessibility, although it was given the conformance test suite.
Note I also didn’t mandate any CSS methodology, except to avoid using Tailwind, Bootstrap, or any other component framework, and to design based on a set of spec tokens to enforce some visual consistency. I didn’t want to make this test all about CSS, but instead about JS frameworks, CSR vs SSR, SPAs vs MPAs, etc. The resulting app is tested against a conformance suite based on the accessibility tree rather than the raw DOM to avoid mandating any particular HTML structure – one framework uses web components which rely on shadow DOM, so this was required.
One thing I learned from this experiment is that everything I’m measuring is very stochastic. LLMs are random-word generators, so sometimes you get a low dice-roll and an agent goes off on some weird tangent wasting a bunch of tokens, through no fault of the framework or its tools. Lighthouse itself can give inconsistent results as well: Largest Contentful Paint (LCP) may decide that one image is the “largest” element, then pick another one on the next run. It’s hard to have a perfectly fair experiment, but running multiple iterations did help, and I’ve tried to be honest about the variance.
With all that throat-clearing out of the way, let’s get to the results.
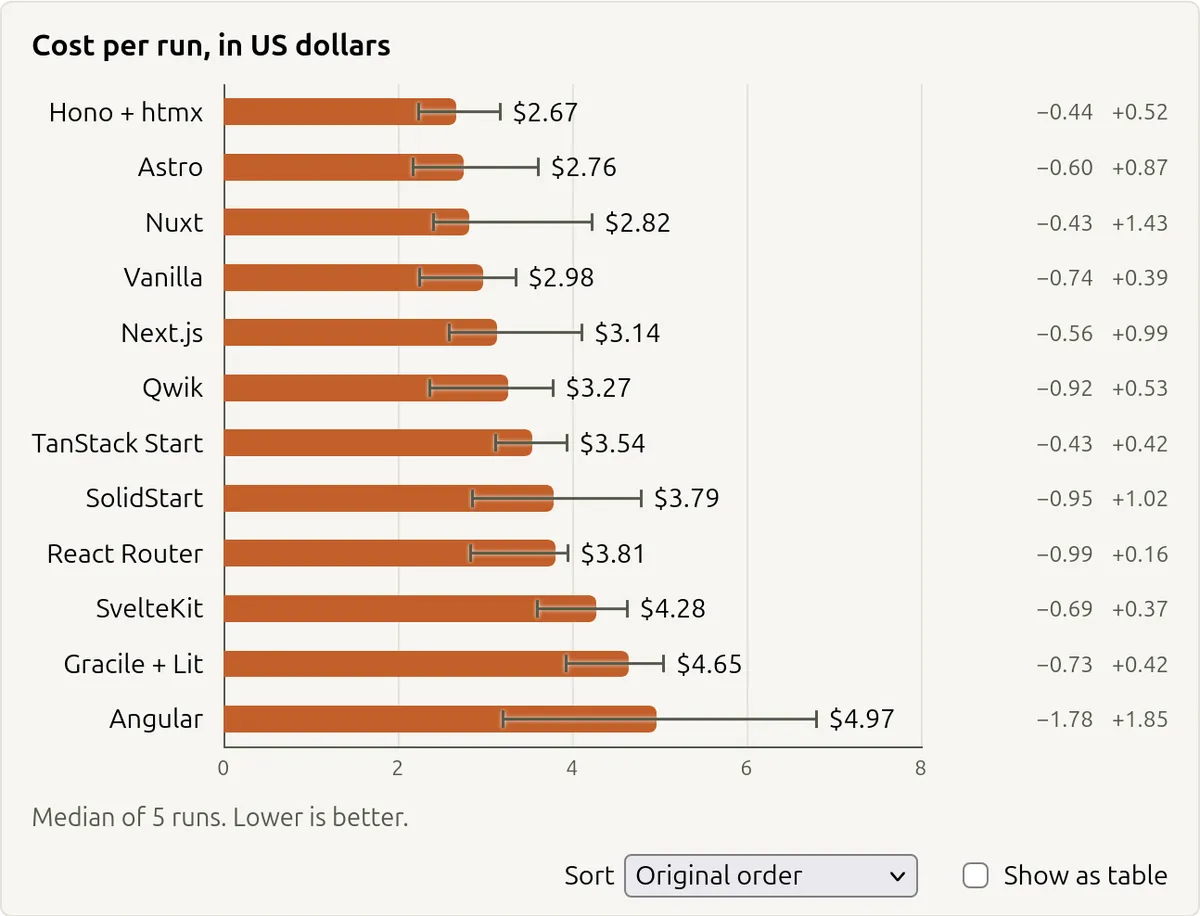
I’m going to break this down by multiple dimensions: cost to build, quality, and maintainability. For each framework/meta-framework, I took the median of 5 runs: in other words, I built the same app 5 times in the same framework. (Yes, this is the kind of zany thing you can do with coding agents these days.)
The exception was Angular, which failed to create a working app twice, so I took 3 iterations instead. (This is explained below.)
Note that this quotes the API prices directly from Claude Code and doesn’t actually represent how much money I spent. I’m on a Max plan, so this was just part of my overall $100/month.
Note also the variance: React Router’s median is roughly $1 worse than that of Hono+htmx, but the cheapest version of React Router ($2.82) is still cheaper than the most expensive version of Hono+htmx ($3.19). However some reliable patterns do emerge.
Most clearly, SvelteKit, Gracile+Lit, and Angular are more expensive to build than the other frameworks. For SvelteKit, this may be due to the fact that the agents read the SvelteKit v3 migration guide in every run, likely because it’s too new to be in Opus 5.5’s training data. Similarly for Gracile, the agents didn’t know the framework very well and either cloned the Gracile repo or read its compiled source from node_modules. For Angular it seems to be a function of the total code size (see below).
I should also mention that not every agent made use of an MCP/skill/Claude Code plugin, nor did every framework have one:
For example, TanStack Start’s agent only discovered its skill files in 2/5 runs (they’re shipped in the node_modules of the project). For Nuxt, the MCP was never used by the agents. For Next.js, agents only read the skill file in 1/5 runs and the AGENTS.md in 2/5 runs. This is a wide range of results, which points back to the stochastic nature of LLMs. I still consider this a valid experiment, though, because I doubt many vibe-coders are shouting at their agents in all-caps to use the MCP (and plenty are probably skipping it entirely).
Also, if you’re wondering how I came up with Hono+htmx: essentially, I wanted htmx represented somehow, and Hono seemed like a fine pairing (i.e. as a JavaScript alternative to Rails/Django/etc.). As for Gracile+Lit, I wanted web components represented via their standard-bearer framework (Lit), and was only aware of Gracile as a meta-framework. If there are better candidates, then those would be great for a follow-up experiment.
For “Vanilla,” note that the agent was told to use “vanilla JavaScript or TypeScript with Vite, without a UI framework.” Surprisingly, this underperforms several frameworks, which seems to demonstrate that having some framework can be better than nothing (or better than raw Vite, anyway). Vite was chosen because it undergirds many frameworks and represents fairly standard and agnostic JavaScript infrastructure.
The total time and tokens track pretty closely with the cost:
Wall-clock minutes from the agent’s perspective. Median of 3-5 runs.
Cache reads, uncached input and output. Median of 3-5 runs.
The tokens, by the way, were reported by Claude Code. The duration is just the total wall-clock time.
Of course, because I think that outcomes matter, I also tested the agents with Lighthouse. As software developers, I think it’s important that we not only build things cheaply but also performantly and accessibly.
I should first note two caveats about my benchmark:
For simplicity’s sake, I’m only reporting the scores for the home page. There are other pages, but they all score fairly similarly or they have wild swings in metrics like LCP, so it just complicates things to include them.
In short: the Lighthouse scores for Performance, Accessibility, and CLS (Cumulative Layout Shift) are nearly saturated and don’t vary much by framework:
So to get some more interesting numbers, we need to look at other metrics. The most reliable one is the JavaScript bytes sent, which largely tracks the client-side framework size:
As reported by Lighthouse. Median of 3-5 apps.
The Total Blocking Time (TBT) is interesting in that it’s not purely a function of the JavaScript bytes; some of the apps spend more time on the main thread than others. That said, the numbers are all quite small:
As reported by Lighthouse, simulated mobile throttling. Median of 5 Lighthouse runs per app, then median of 3-5 apps after that.
Largest Contentful Paint (LCP) is highly variable due to the aforementioned issues with the metric itself. As expected, though, it does broadly punish SPAs and reward MPAs:
As reported by Lighthouse, simulated mobile throttling. Median of 5 Lighthouse runs per app, then median of 3-5 apps after that.
Note that the wild variance in the Next.js numbers can be explained by the fact that one app avoided lazy-loading images and the other four didn’t. Astro and Vanilla have similar swings that appear to be caused by prioritization or LCP quirks.
In general though, it’s unsurprising that the metric tends to reward MPAs that paint quickly with HTML rather than SPAs that paint after client-side JavaScript runs (along with possibly multiple throttled round-trips to grab the Pokémon data). Ignoring variance, LCP here is mostly a function of JavaScript bundle size. (Qwik is a notable exception here: technically it’s an SPA that uses client-side routing, but it scores among the MPA frameworks.)
Note though that some of the frameworks varied in whether they focused more on the client or the server, or even whether they used a client-side framework. For example, the Gracile agent didn’t even use Lit in two runs. For “Vanilla,” the agent had full latitude (aside from being told to use Vite), but still chose to build an SPA all 5 times.
SSR vs CSR is also partly where the trouble with Angular came from: in 2 runs, the agent built an SSR app that rejected non-localhost (even though the instructions explicitly said that the app would be behind a reverse proxy). I considered this a valid failure to adhere to the spec and decided not to re-run the 2 failed iterations.
There are lots of ways to measure maintainability (including fancy things like cyclomatic complexity), but I decided to keep it simple and report something tried-and-true: total lines of code.
Number of non-blank source file lines. Median of 3-5 apps.
To me this is one of the more interesting charts. In a sense, the whole point of a framework is to reduce the amount of code you need to maintain. In Rich Harris’s memorable words:
“Frameworks are not tools for organizing your code; they are tools for organizing your mind.”
In the agentic era, this hits even harder because the code size ultimately impacts the number of tokens, including in future edits, meaning it affects the literal cost to maintain a codebase over time. This doesn’t mean that succinctness is the only value that matters, but it’s certainly interesting to see that Hono+htmx can do roughly the same thing as Angular with ~70% of the code (and faster, to boot).
There are many ways you could improve this benchmark. For example, you could mandate that the agent use Service Workers for offline caching, or optimize the Pokémon image files, or use lazy-loading, fetchpriority, the Speculation Rules API, etc. Even though I know a lot of these performance hacks, I deliberately didn’t steer the agents toward any of them, because it’s not what a typical vibe-coder would do.
On the other hand, this entire benchmark could be cheated by just pre-generating all the HTML files as static assets (there are only so many Pokémon). I specifically forebade that in the instructions and made it an explicit check in the test harness, because I felt that it wasn’t in the spirit of the benchmark. (My aim is to simulate a large volume of possibly-dynamic data, which is more challenging than a purely static site.)
You could also
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。