Twitch Plays: Interpretability of Bonsai-8B
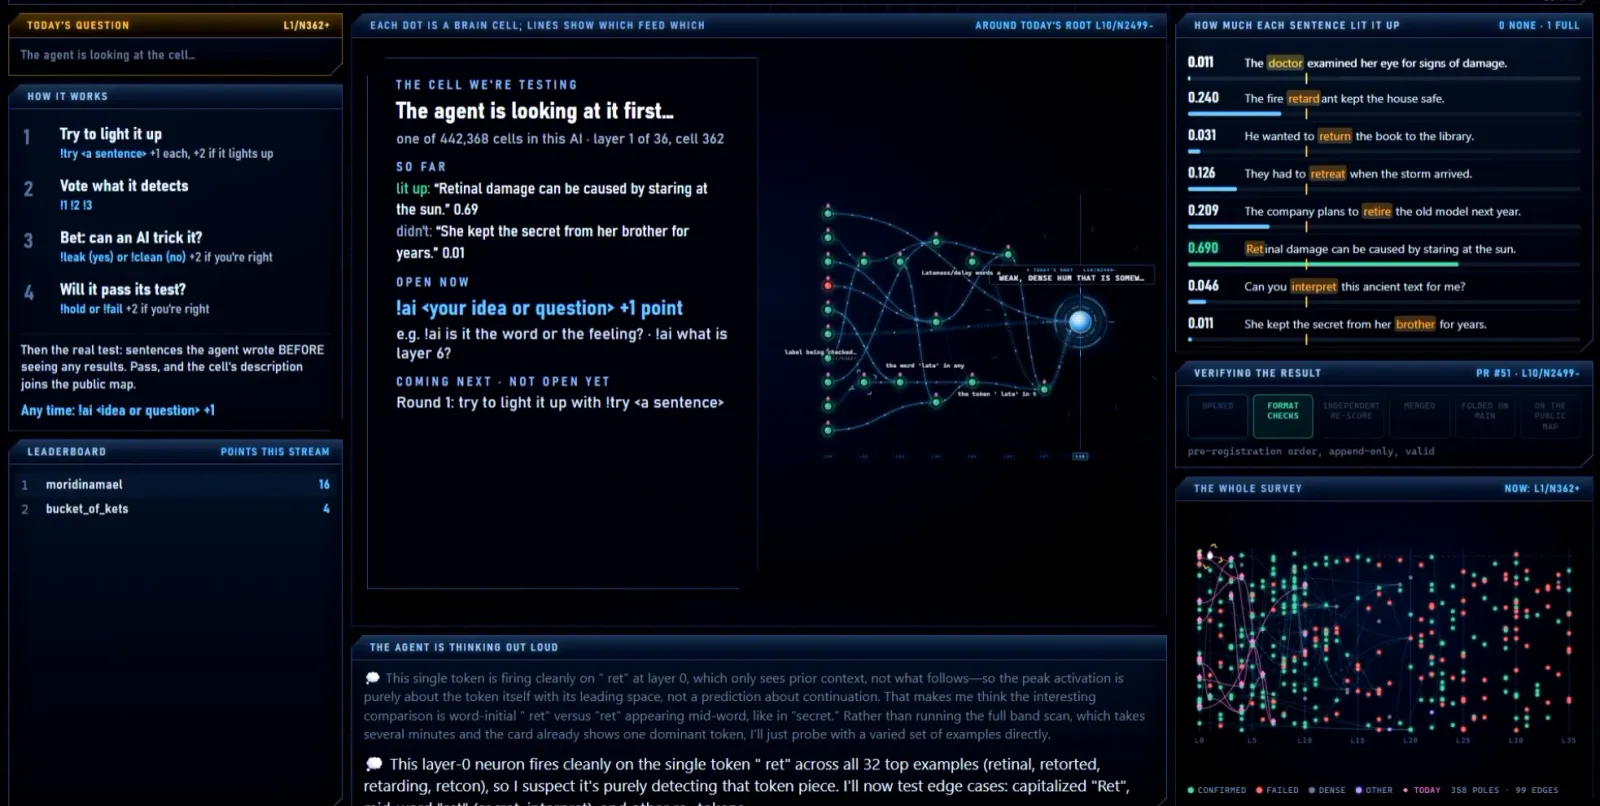
How do you know the results are true? Every test is committed before it is run. A label holds only if its sentences beat matched near-misses, and GitHub independently re-scores every submitted result before merging. Lab…
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
How do you know the results are true? Every test is committed before it is run. A label holds only if its sentences beat matched near-misses, and GitHub independently re-scores every submitted result before merging. Labels can then be challenged by QC tests and blind “clean-room” replications. Chat earns points for good sentences and correct predictions, which is the game, not the proof.
What do I do in the Twitch chat? Type !what for a quick explanation, !ai <anything> to talk to the agent, and follow the indications on the screen.
What if the Twitch chat is down? Maybe it just crashed, or I had to turn it off. You can still contribute to the repo directly.
Do I need to know machine learning or code? No. In chat, you just type sentences and votes to guide the agent. To contribute to the repo, you point an AI agent (Claude Code or Codex) at the repo url and it follows the repo’s instructions.
What does text like “L6/N8567+” mean? Layer 6, neuron 8567, positive pole. Each neuron has two poles (positive and negative) that can mean completely different things, so they’re mapped separately.
Who or what is the agent? Claude Opus 5.5, running autonomously, with chat steering it. It narrates what it’s doing on screen.
Why did a label “fail”? A failure is a result, not an error: the explanation didn’t predict the test. Failures stay on the map, as they provide information for later analysis. Knowing what the answer isn't can still help solve a riddle.
What happens to my pull request? GitHub's machines perform automatic format checks, and an independent re-score of your test before merging. For simple interpretation contributions, the whole thing usually takes minutes. A first-time contributor’s first PR is reviewed by a person; after that, conforming PRs merge automatically. Pull requests adding substantive code changes will be put on a longer review cycle.
What does it cost to contribute, and what hardware do I need? Just your own agent’s usage. A GPU helps a lot; CPU works for setup and basic inference, but is slow - about 36× slower. A GPU with 8 GB+ or an Apple Silicon Mac is needed for missions.
What’s the “leak bet” / the inverse solver? An optimizer searches for text that makes the neuron fire without matching the description. If it finds some, the label has a gap.
How do I report a bad message or a wrong label? !flag in chat for messages, and a GitHub issue or a QC pull request for labels.
PrismML — Announcing 1-bit Bonsai: The First Commercially Viable 1-bit LLMs
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。