Exporting 150M SQL Server rows to Parquet: reading the .bak beats the DB
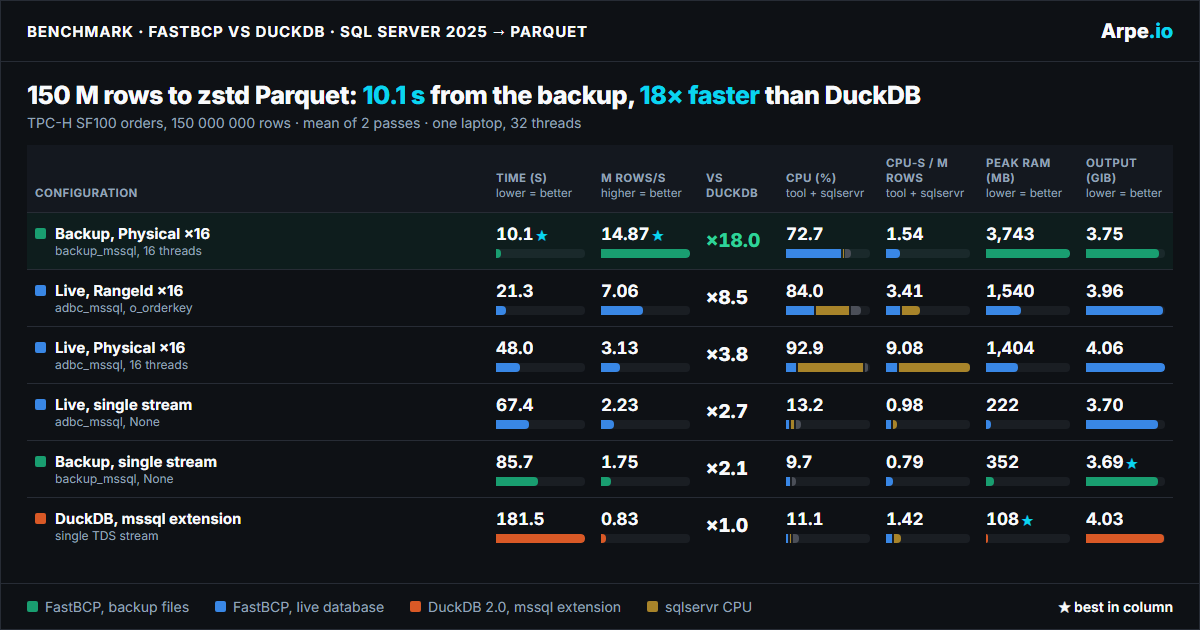
We exported the TPC-H SF100 orders table, 150 million rows, from SQL Server 2025 to zstd Parquet on one laptop. DuckDB 2.0 with its mssql extension took 181 s. FastBCP took 21 s on the live database with RangeId, and 10…
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
We exported the TPC-H SF100 orders table, 150 million rows, from SQL Server 2025 to zstd Parquet on one laptop. DuckDB 2.0 with its mssql extension took 181 s. FastBCP took 21 s on the live database with RangeId, and 10.1 s reading the backup files with no SQL Server involved. All six outputs hold exactly the same 150 million rows.
Getting a large SQL Server table into Parquet is a daily job for data engineers: to feed a lake, a warehouse, or a model. Most teams reach for what they already have, and DuckDB is a fine default: one binary, one COPY statement. The question is what it costs on a big table, and what you gain with a tool built for bulk export.
So we put the same 150 million rows through six configurations: DuckDB, FastBCP on the live database with three parallel methods, and FastBCP reading the database backup directly. Every run was measured twice, with CPU, memory and disk sampled every 1.3 seconds.
The mssql community extension (v0.3.0, native TDS client) attaches the database, then COPY (SELECT * FROM src.dbo.orders) TO 'orders.parquet'. One query, one stream, one file.
The adbc_mssql connector embeds the arpe.io ArpeMSSQL ADBC driver: it speaks TDS to SQL Server and hands Arrow batches to FastBCP. Three ways to split the table: None (one stream), Physical and RangeId on o_orderkey, both with 16 threads.
The backup_mssql connector reads the table straight from the striped .bak files, with no restore and no instance. One stream, or Physical with 16 threads, which reads the pages in parallel.
The four live configurations ask SQL Server for the rows: it decompresses the columnstore and sends the rows over the network protocol, then the export tool encodes Parquet. The two backup configurations skip SQL Server entirely: FastBCP opens the backup pages itself. Several arrows stand for the 16 parallel streams of Physical and RangeId.
The sampler's CPU-seconds match FastBCP's self-reported CPU time within 4% on every run, so the CPU figures can be trusted for DuckDB too, which reports none. The live runs had orders already in the SQL Server buffer pool; the backup runs, except the very first one, read the .bak files from the Windows file cache. Both start from a warm cache.
This benchmark was designed, run, checked and written up by Claude Opus 5.5 in Claude Code, using the arpe.io fastbcp skill. The agent wrote the PowerShell harness and the sampler, built every FastBCP command line, ran the 12 runs, cross-checked its metrics against FastBCP's own, and verified the row counts and checksums of the Parquet outputs.
The skill is what makes this practical. FastBCP has many options, and a few of them only make sense together: backup_mssql takes a directory in --server and a file pattern in --database, RangeId needs --distributekeycolumn, Physical resolves to a different strategy on a backup than on a live table. The skill gives the agent those rules, the defaults of the version in use, and the mistakes to avoid, so the commands are right the first time instead of after a few failed runs.
github.com/arpe-io/arpeio-skills: one plugin per product, each with a SKILL.md and reference files loaded on demand.
Claude Code as a plugin marketplace. Codex, Cursor, GitHub Copilot, Gemini CLI and any agent that reads skills, by copying the skill folder.
In Claude Code, add the marketplace and install the skill:
/plugin marketplace add arpe-io/arpeio-skills
/plugin install fastbcp@arpe-io
Or in one step: /plugin install fastbcp --marketplace arpe-io/arpeio-skills. Third-party marketplaces do not auto-update by default; turn it on in /plugin → Marketplaces → arpe-io, or update by hand with /plugin marketplace update arpe-io then /plugin update fastbcp@arpe-io.
For other agents, copy the skill folder into the directory your agent reads skills from:
git clone https://github.com/arpe-io/arpeio-skills.git
cp -r arpeio-skills/plugins/fastbcp/skills/fastbcp <your-agent-skills-dir>/
Then ask in plain words, for example "Export dbo.orders from the tpch_100 backup files to Parquet with FastBCP, 16 threads". The skill checks the installed FastBCP version first and follows the FastBCP documentation when the product is newer than the skill.
Idle baseline of the machine: ≈ 9 to 10 % CPU, counted in 'rest of the machine'. Backup, single stream: 94.1 s on the first pass (cold file cache, plus a one-time backup index build) and 77.3 s warm.
The two passes agree within 3% for four configurations. RangeId varies more (22.7 s, then 19.9 s), and the single-stream backup read is 18% faster once the file cache is warm. Even FastBCP's slowest configuration, one thread on the backup files, beats DuckDB by more than a factor of two.
The fairest single-stream comparison is FastBCP None on the live database: same source, one stream, one file. FastBCP is still 2.7 times faster: both read TDS, but the ArpeMSSQL driver decodes it straight into Arrow batches.
A busy machine is not a bad sign here: the fast runs are fast because they put the cores to work. What matters is who burns the CPU: with the backup, it is FastBCP alone, and SQL Server stays free for its users.
Among the parallel runs, the backup is the cheapest: 1.54 CPU-s per million rows, against 3.41 for RangeId. The live path pays twice: SQL Server decompresses and serializes the rows, then FastBCP decodes them. The backup reader skips the first half.
Speed has a price in memory: 3.7 GB for the parallel backup reader, 1.5 GB for the live parallel runs. On a 64 GB machine that is comfortable; on a small VM, lower --paralleldegree.
Same codec everywhere; the differences come from the row group size. FastBCP uses 262 144 rows per group in one stream and 65 536 at 16 threads. Set FASTBCP_RGSIZE if your engine prefers another layout.
FastBCP live, RangeId ×1620 s
FastBCP live, Physical ×1648 s
FastBCP live, single stream69 s
FastBCP backup, single stream77 s
DuckDB, mssql extension182 s
0 s30 s60 s90 s120 s150 s180 s
Drawn on one time scale, the six runs tell the story at a glance. The parallel backup run is a short block of FastBCP alone. RangeId pins the machine at 100% for most of its 20 seconds, shared between SQL Server and FastBCP. Physical keeps it near 100% for most of its 47 seconds, almost all of it in SQL Server. DuckDB is a flat line for three minutes.
backup_mssql with Physical reads the striped .bak files with page-level random access. It is CPU-bound: FastBCP alone uses about 65% of the machine. It is not disk-bound: writes average 389 MB/s, far below what the NVMe drive can do. And the SQL Server instance does nothing at all, which on a production server is the point: the export no longer competes with your users, and it runs on any machine that can see the backup.
Both use 16 threads, but they spend the CPU in different places. RangeId splits o_orderkey into 16 min/max ranges; SQL Server uses about 40% of the machine and FastBCP 33%. Physical splits by physical row location, and on this clustered columnstore SQL Server saturates: 1 181 CPU-seconds against 280. The likely reason, not verified on the query plans, is that key ranges benefit from columnstore segment elimination while row-location predicates make each of the 16 queries work through far more data.
Practical rule
On SQL Server, prefer RangeId or Ntile on a good leading key over Physical, especially on columnstore tables. Our guide on choosing the right FastBCP parallel method goes through every option.
With one thread, the live export (67 s) beats the backup export (77 s warm). From the backup, FastBCP decodes the columnstore segments on its single thread: 118 CPU-s, against 81 for the live run, where SQL Server does that part. The backup reader pays off in parallel, where it scales much further.
All six outputs contain exactly 150 000 000 rows. The pass 2 outputs were compared with DuckDB over the Parquet files:
The float sums differ only in the last digits, from the summation order over a different file and row-group layout.
A hybrid P/E-core CPU with frequency boost. Source, backup and output share one NVMe drive, and the client competes with SQL Server for the same cores. A server, remote storage or a network will change the absolute numbers.
The table sat in the buffer pool and the backup in the file cache. A cold 16-thread backup read would likely be bound by the disk; the cold single-stream pass took 94 s instead of 77 s.
The live results depend on how the table is stored. With a classic clustered index on o_orderkey instead of a clustered columnstore, each RangeId range would be a clean index seek, and FastBCP on the live database would likely do better than here.
A backup export returns the data as of the backup, here 2026-11-01. The table had not changed since. For fresher data, FastBCP can read a full backup and its differential together; the export is then slightly slower than from the full backup alone.
The FastBCP command for the live database, in PowerShell:
.\FastBCP.exe `
--connectiontype adbc_mssql `
--server ".\SS2025" `
--database tpch_100 `
--trusted `
--sourceschema dbo `
--sourcetable orders `
--directory "C:\temp\export\fastbcp_rangeid" `
--fileoutput "orders.parquet" `
--parallelmethod RangeId `
--distributekeycolumn o_orderkey `
--paralleldegree 16
For Physical, use --parallelmethod Physical --paralleldegree 16 without --distributekeycolumn. For one stream, see the minimal commands below.
From the backup files, no credentials and no instance, the pattern names all 6 stripes:
.\FastBCP.exe `
--connectiontype backup_mssql `
--server "C:\MSBAKTEST\NOCOMPRESS" `
--database "tpch_100_part*.bak" `
--sourceschema dbo `
--sourcetable orders `
--directory "C:\temp\export\backup_physical" `
--fileoutput "orders.parquet" `
--parallelmethod Physical `
--paralleldegree 16
And DuckDB, after INSTALL mssql FROM community;:
LOAD mssql;
SET mssql_named_instance_resolution=true;
SET mssql_query_timeout=0;
ATTACH 'Server=localhost\SS2025;Database=tpch_100;Trusted_Connection=yes;TrustServerCertificate=yes'
AS src (TYPE mssql, READ_ONLY);
COPY (SELECT * FROM src.dbo.orders)
TO 'C:\temp\export\duckdb\orders.parquet' (FORMAT parquet, COMPRESSION zstd);
The minimal FastBCP commands
The single-stream runs need no parallel option at all: the default method is None. Parquet with zstd is the default output too, so no format option is needed either. From the live database:
.\FastBCP.exe `
--connectiontype adbc_mssql `
--server ".\SS2025" `
--database tpch_100 `
--trusted `
--sourceschema dbo `
--sourcetable orders `
--directory "C:\temp\export\fastbcp_none" `
--fileoutput "orders.parquet"
From the backup files:
.\FastBCP.exe `
--connectiontype backup_mssql `
--server "C:\MSBAKTEST\NOCOMPRESS" `
--database "tpch_100_part*.bak" `
--sourceschema dbo `
--sourcetable orders `
--directory "C:\temp\export\backup_none" `
--fileoutput "orders.parquet"
With the fastbcp skill installed, you can also just describe the export to your agent and let it build the command.
Parallel export from the live database, or straight from your .bak files with no restore and no load on production. SQL Server, PostgreSQL, Oracle, MySQL, Teradata and more, to Parquet, CSV or JSON, on local disk or in the cloud.
Add the arpe.io skill to your agent and let it write the commands.
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。