Who owns NIS2 and DORA on a Kubernetes platform team
There is a meeting that repeats across a lot of European engineering organizations right now. Someone from legal or risk brings a NIS2 control, a DORA article, or a “can we evidence this” request into the...
以下正文同步自 CNCF Blog,版权归原站所有,已转换为易读排版。
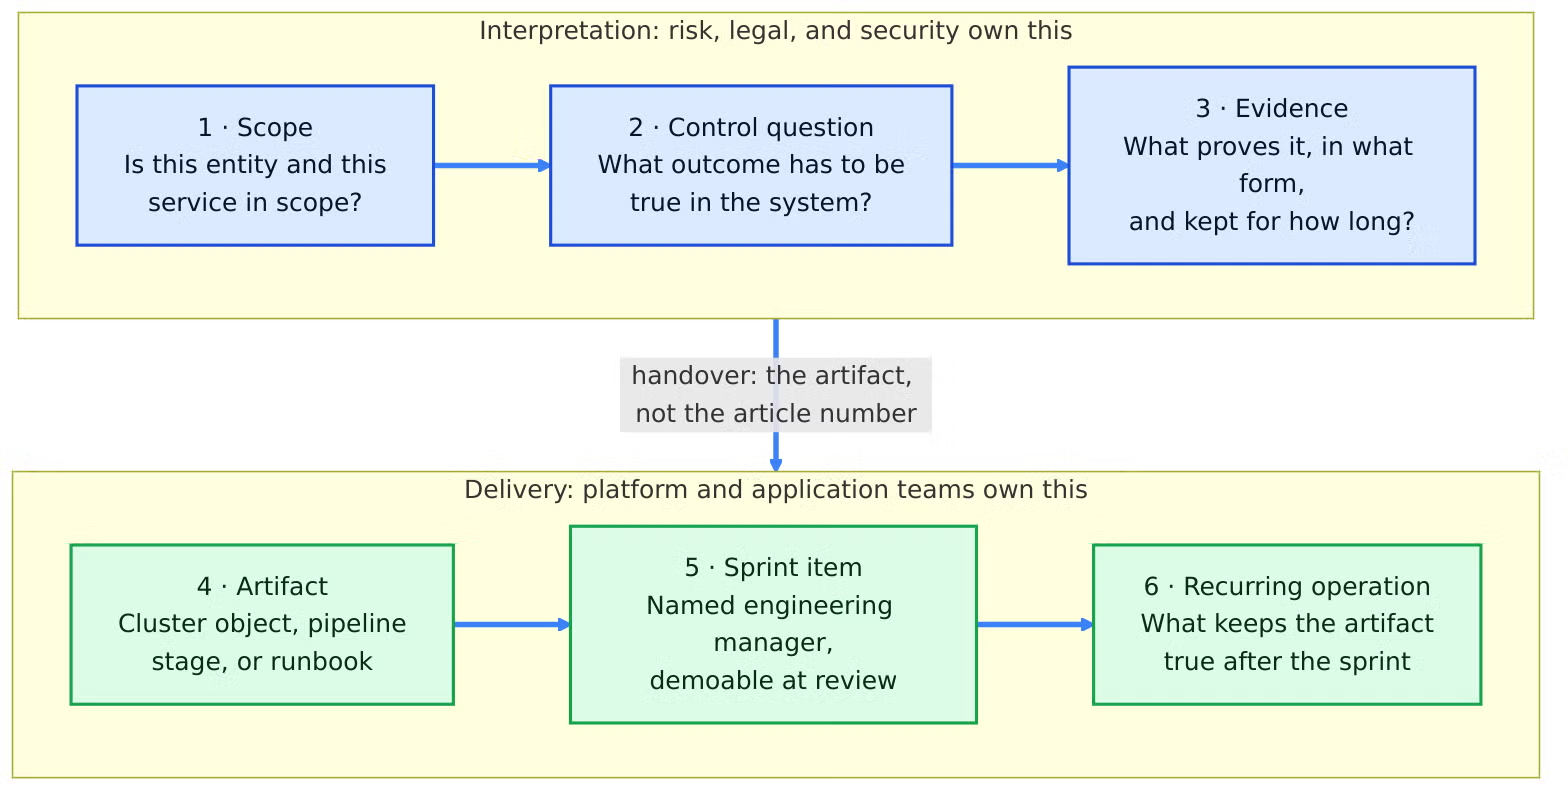
There is a meeting that repeats across a lot of European engineering organizations right now. Someone from legal or risk brings a NIS2 control, a DORA article, or a “can we evidence this” request into the room. The Kubernetes platform team looks at security. Security looks at the platform team. A ticket lands on the security board, because that feels like the responsible place for anything with a regulation in the title. Three sprints later the cluster has not changed, the evidence still does not exist, and everyone is quietly annoyed with the security lead. The failure is not legal and it is not technical. It is an ownership failure, and it has a specific shape: a regulation name was put on a board instead of an artifact being put in a sprint. Security can write the policy. Security cannot merge the Helm chart. This article is about closing that gap on a cloud native platform: the traceability chain from a regulatory requirement to a Kubernetes object, a RACI that survives contact with sprint planning, and the open source projects that actually produce the evidence. One caveat before going further. Nothing here is legal advice, and none of the mappings below are an official compliance mapping. NIS2 and DORA are outcome-based texts. Which entities and services are in scope, what measures are proportionate, and what evidence is sufficient all depend on the organization’s own risk assessment, its sector rules, national transposition, and its regulator. They do not depend on a table in a blog post. What happens when security owns the regulation The common default is that anything with a regulation in the title becomes a security ticket. The CISO, or the one senior security engineer who still answers Slack, becomes the owner of NIS2, DORA, and whatever arrives next. Platform engineers stay on product work. Application teams stay on features. The security function becomes a queue. Two failure modes follow, and they feed each other. The first is the bottleneck. Every image exception, every privileged securityContext, every “we need this log in the SIEM” request waits on the same two people. Delivery teams learn that talking to security is how work dies, so they start routing around it: a break-glass kubeconfig here, a sidecar nobody reviewed there, a registry that is not the approved catalog. The result rarely announces itself. Non-compliance does not show up as a red cell on a slide; it shows up as shadow infrastructure carrying a ticket label that still says “security”. The second is learned helplessness on the platform side. If compliance is permanently someone else’s backlog, platform engineers never own the reasoning behind it. They ship an admission policy because they were told to, disable it when it blocks a release, and wait for security to notice. That is the opposite of the ownership every platform engineering talk asks for. You cannot ask a team to own outcomes and simultaneously keep the regulatory outcome on another team’s board. Neither failure is a personality problem. Both are org designs that nobody named out loud. What NIS2 Article 20 and DORA Article 5 actually assign Both texts are blunt about where accountability sits, and it is not “the security team”. NIS2 Article 20 places cybersecurity risk-management measures on the management body of essential and important entities. The management body approves the measures, oversees their implementation, can be held liable for non-compliance, and is required to follow training. DORA Article 5 does the same for financial entities. The management body defines, approves, oversees, and remains responsible for the ICT risk management framework, and roles and responsibilities for all ICT-related functions have to be assigned clearly and documented. A CISO title is not a substitute for that assignment; it is one of the roles the assignment has to name. So far this reads like a board problem. By Friday afternoon it is a middle-management problem. The management body will not patch containerd. It will not decide whether kube-apiserver audit logs are retained for 12 months or 18. It will not sit in the planning session where “ship the new tenant” competes with “we still have no evidence trail”. Those decisions are made by engineering managers, or they are not made at all. The vacuum underneath the management body is where most programs die. Legal translates the article. Security writes a control statement. Nobody is accountable for the Kubernetes object that would make the statement true. The same vacuum appears in Cyber Resilience Act programs, which carry a harder clock: accountability at the top is theater unless someone in engineering owns the work that produces the evidence. Put artifacts on the board, not regulation names A regulation is a reason. It is not a ticket. “NIS2 Article 21” cannot be demoed at sprint review. “kube-apiserver audit policy shipped, logs shipped to the SIEM, retention documented” can be. The artifact does not come from an engineer reading a directive and inventing a Kubernetes task. It comes from a traceability chain with a clean handover in the middle. Traceability chain in two stages: scope, control question, and evidence definition owned by risk, legal, and security; artifact, sprint item, and recurring operation owned by the platform and application teams Steps one to three are interpretation, and they belong to risk, legal, and security. Steps four to six are delivery, and they belong to the platform and application teams. The handover is the artifact, not the article number. A ticket that says “implement NIS2 Article 21(2)(d)” has skipped the middle of the chain and asks an engineer to act as the lawyer who decided the law applies. The chain also closes. Step six is what produces the evidence that step three asked for, which means the output of delivery flows back to risk, audit, and the SOC as a matter of routine rather than as a fire drill three days before an inspection. An artifact that only exists because someone ran a script by hand once has not completed the chain. The table below shows what the output of that chain looks like on a Kubernetes platform. The middle column is the control question the artifact answers. The provenance columns point at the provisions that make the artifact relevant; they are not a claim that the text commands that specific implementation. DORA references apply only where the financial entity and the ICT service fall within its scope. Operational artifactControl question it answersNIS2 provenanceDORA provenance Hardened image catalog and rebuild pipelineCan we reduce known weaknesses in deployed software, and rebuild promptly when a material vulnerability is disclosed?Article 21(2)(d) and (e): supply chain security, vulnerability handling and disclosureArticles 8 and 9: ICT asset identification, protection and prevention A secrets manager as the only credential pathCan we protect credentials, limit access to them, and show that secrets are not spread through code and cluster configuration?Article 21(2)(i) and (j): access control, asset management, multi-factor authenticationArticle 9: protection and prevention measures Kubernetes audit logs and ingress logs in the SIEMCan we detect suspicious activity, investigate an incident, and retain the evidence for the required period?Article 21(2)(b): incident handlingArticles 10 and 17: detection capabilities, ICT-related incident management Admission policy: restricted Pod Security Standards, no unpinned image tagsCan we prevent unsafe workload configurations from reaching production, while recording approved exceptions?Article 21(2)(f) and (i): policies on effectiveness, access control, asset managementArticle 9: protection and prevention measures Incident runbook and a 24-hour fact packCan on-call staff establish what happened, its impact, and the facts needed for a timely escalation?Articles 21(2)(b) and 23: incident handling, early warning within 24 hours and notification within 72 hoursArticles 17 and 19: incident management, reporting of major incidents SBOM generated and retained in CICan we identify what software we shipped, and when, if a supplier, package, or vulnerability requires investigation?Article 21(2)(d) and (e): supply chain security, vulnerability handlingArticle 28: ICT third-party risk management A ticket that names the artifact, links the control question, states the evidence, and has a person who can finish it is a concrete piece of work. It can be estimated, it can be demoed, and (the part that matters at audit time) it can be pointed at. The cloud native projects that produce the evidence None of these artifacts requires a compliance product, in the sense of a tool that generates evidence about a platform it does not otherwise touch. They are ordinary platform capabilities, and the open source ecosystem covers most of them. Not everything in the table below is a CNCF project (Sigstore and OpenBao sit under the OpenSSF and the Linux Foundation respectively), but all of it is open source and all of it can be run by the team that owns the cluster. The table is illustrative rather than prescriptive. It answers “can this be built with open source”, which is not quite the question a platform lead faces. ArtifactOpen source building blocksWhat the platform team actually operates Hardened image catalog and rebuild pipeline *Harbor for the registry, Sigstore for signing and verification, in-toto for attestations, an image scanner in CIA base image that is rebuilt on a schedule and on advisory, published to one registry that workloads are allowed to pull from Secrets as a managed serviceOpenBao or an equivalent open source secrets manager as the store, External Secrets Operator to project secrets into the cluster, SPIFFE and SPIRE for workload identity, cert-manager for certificate lifecycleOne credential path: identity-based, short-lived, with no long-lived tokens in manifests or CI variables Audit and detection evidenceKubernetes audit policy upstream, Fluentd or Fluent Bit and OpenTelemetry for collection, Falco for runtime events, Prometheus for the operational signalsAn audit policy that is not None, a shipping pipeline that survives node churn, and a retention setting someone has written down (the SIEM at the far end is usually bought; the collection path is yours) Admission control and exceptionsKyverno or OPA Gatekeeper, plus the upstream Pod Security Admission baselinePolicies in version control, enforced in production, with exceptions expressed as objects that expire rather than as Slack messages Software inventorySBOM generation in CI, stored as an attestation next to the artifact rather than in a wikiAn answer to “what was in the image we deployed on the 14th” that takes minutes, not days Service ownership metadataBackstage or an equivalent catalogA machine-readable answer to “who is the engineering manager for this service”, which is what makes the RACI below real
- Buildable and realistic to operate are different claims, and the hardened image catalog is where they diverge most. The pieces are all open source, but the product is not the pipeline; it is the rebuild cadence, sustained across every base image and runtime you ship, in the week half the team is on holiday. Few platform teams are funded for that, and a catalog that goes stale is worse than no catalog, because by then a control statement says it is handled. Sourcing the base layer from someone who maintains it full time is a legitimate answer, and it does not remove the ownership question so much as change its shape: the provider enters third party scope under NIS2 Article 21(2)(d) and DORA Article 28, and supplier management needs a named owner exactly as the pipeline did. None of this is unique to regulated industries. It is the same platform baseline most mature teams build anyway; NIS2 and DORA mostly change the deadline and the consequence of missing it. Open source removes the license barrier rather than the staffing
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。