Multi-tenant GPU Kubernetes on simulated hardware with Kamaji and HAMi
GPU teams usually face a bad trade-off. Give every team its own Kubernetes cluster and you pay for a control plane per team. Put everyone in one shared cluster and you get weak isolation. Either way,...
以下正文同步自 CNCF Blog,版权归原站所有,已转换为易读排版。
GPU teams usually face a bad trade-off. Give every team its own Kubernetes cluster and you pay for a control plane per team. Put everyone in one shared cluster and you get weak isolation. Either way, Kubernetes hands out GPUs as whole cards, so a pod that needs 4 GB of an 80 GB GPU still blocks the entire card. This post shows a way out by combining two open-source projects:
- Kamaji runs each tenant’s Kubernetes control plane as pods inside one management cluster.
- HAMi lets pods request a slice of a GPU (memory in MB, compute in %) and packs several pods onto one card. I built the whole thing on a single machine with no physical GPU, using HAMi’s mock device plugin to simulate the cards. The result: two fully isolated tenant clusters, each scheduling fractional-GPU workloads through HAMi, with all eight tests passing. Everything below is reproducible: the exact versions, the commands that worked, the errors I hit and how I fixed them.
Architecture
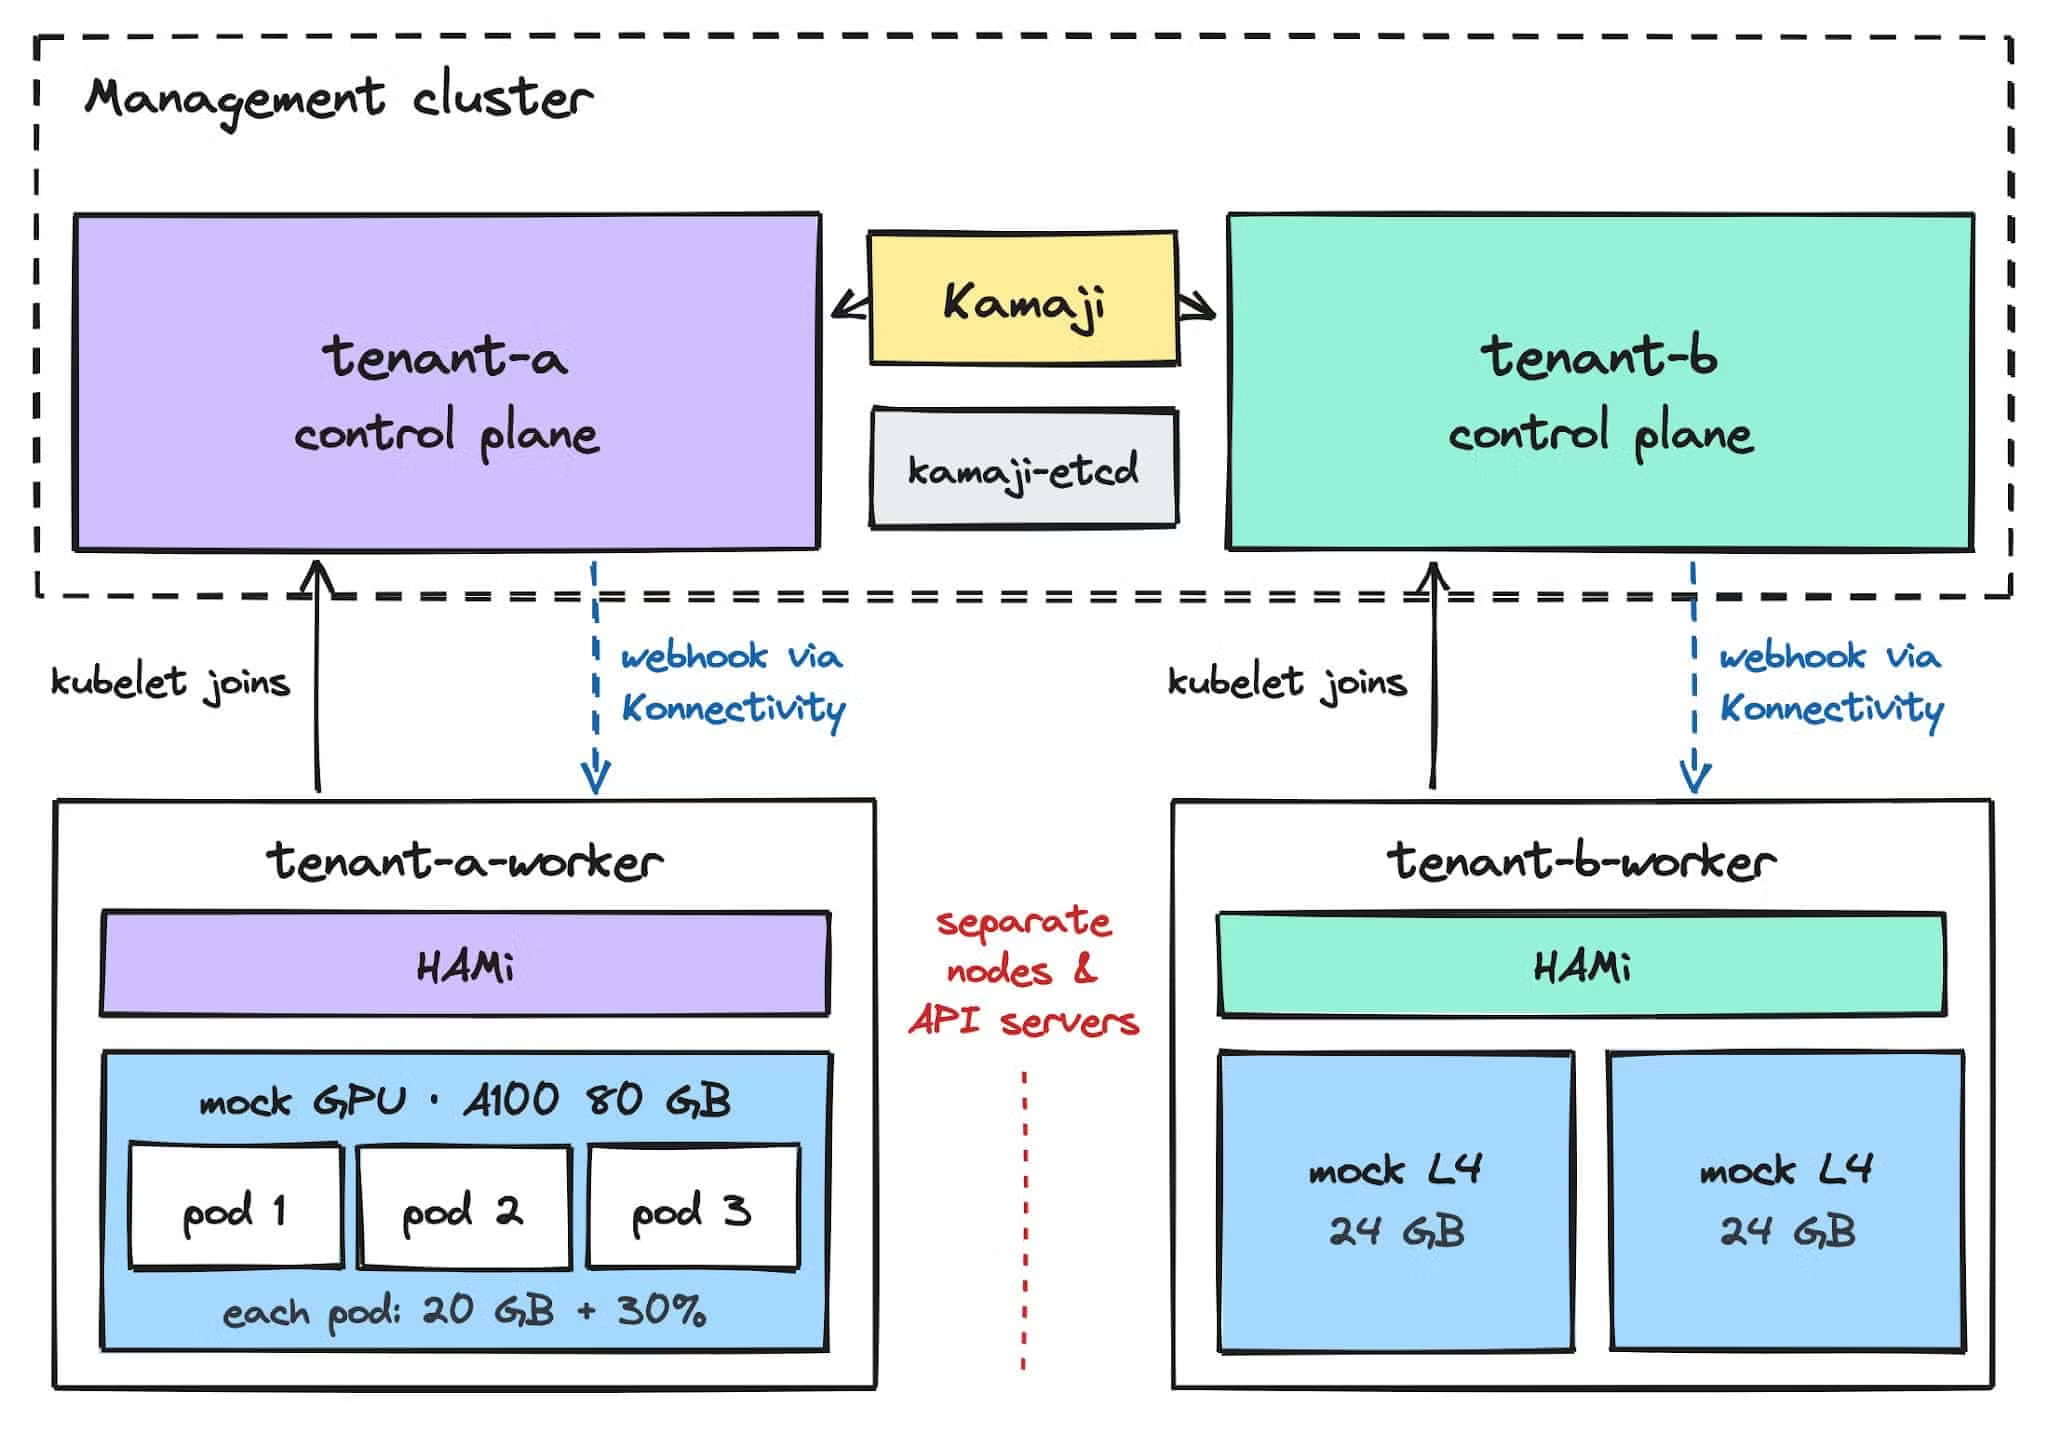
One kind cluster hosts Kamaji and both tenant control planes; each tenant’s worker is a separate container that joins over the kind network and runs HAMi. Tenants never share a node or an API server. The only shared pieces are the management cluster and the kamaji-etcd datastore, where each tenant’s data is kept separate.
Why Kamaji + HAMi
Kamaji solves the cluster problem and HAMi solves the GPU problem; they work at different layers, so they don’t overlap. The interesting part is where they meet. A tenant’s API server lives in the management cluster, but HAMi’s webhook lives on the tenant’s worker nodes. Every GPU pod creation therefore depends on the API server reaching back into the tenant through Kamaji’s Konnectivity tunnel. Proving that path works was the main goal of this lab.
Lab setup
Everything runs as Docker containers on one Linux host; 4 CPU cores, 8 GB of free RAM and 20 GB of disk are enough. How do you test GPU sharing without a GPU? HAMi’s real device plugin talks to the NVIDIA driver, so it can’t start without hardware. The mock device plugin skips hardware discovery. You describe fake cards in a node annotation, and it registers gpumem and gpucores capacity from that. HAMi’s webhook, scheduler and quota logic then run exactly as they would on real nodes. Two simulated setups make the tenants easy to tell apart:
- tenant-a: 1 × NVIDIA A100 80 GB (81,920 MB, 100 cores)
- tenant-b: 2 × NVIDIA L4 24 GB (49,152 MB, 200 cores)
Step-by-step build
The build has five steps; step 3 creates both tenants at once, and steps 4 and 5 are repeated per tenant. Plain kubectl talks to the management cluster; --kubeconfig tenant-a.kubeconfig talks to a tenant. Step 1: Management cluster, cert-manager and MetalLB
kind create cluster --name kamaji

kubectl apply -f https://github.com/cert-manager/cert-manager/releases/download/v1.21.2/cert-manager.yaml

kubectl -n cert-manager wait pod --all --for=condition=Ready --timeout=180s

kubectl apply -f https://raw.githubusercontent.com/metallb/metallb/v0.16.1/config/manifests/metallb-frr-k8s.yaml

kubectl -n metallb-system wait pod --all --for=condition=Ready --timeout=180s
Find your kind network’s IPv4 subnet, then give MetalLB a range at the top of it:
docker network inspect kind | grep Subnet
cat
Step 2: Install Kamaji
helm repo add clastix https://clastix.github.io/charts
helm upgrade --install kamaji clastix/kamaji \
 --namespace kamaji-system --create-namespace \
 --set 'resources=null' --version 0.0.0+latest

kubectl -n kamaji-system get pods
Step 3: Create the Tenant Control Planes This creates both tenants, tenant-a and tenant-b:
export TENANT_VERSION=v1.36.4
kubectl create namespace tenants
for t in tenant-a tenant-b; do
cat
Once both tenant control plane pods are Running, save a kubeconfig for each tenant:
for t in tenant-a tenant-b; do
 kubectl -n tenants get secret ${t}-admin-kubeconfig -o jsonpath='{.data.admin\.conf}' | base64 -d > ${t}.kubeconfig
 kubectl --kubeconfig ${t}.kubeconfig cluster-info
Done
Each tenant control plane is a single pod in the tenants namespace of the management cluster, running on the kamaji-control-plane node. The 4/4 in the READY column are its four containers:
- kube-apiserver: the tenant’s API server, exposed through the MetalLB IP
- kube-scheduler: the tenant’s default scheduler
- kube-controller-manager: runs the tenant’s built-in controllers
- konnectivity-server: the management-cluster end of the tunnel that lets the API server reach the tenant’s worker nodes Step 4: Join a worker node Kamaji has no kind helper for workers, so the worker is a kindest/node container on the kind network, joined with standard kubeadm. Its version must match the tenant.
docker run -d --name tenant-a-worker --hostname tenant-a-worker \
 --network kind --privileged \
 --security-opt seccomp=unconfined --security-opt apparmor=unconfined \
 --tmpfs /tmp --tmpfs /run -v /var -v /lib/modules:/lib/modules:ro \
kindest/node:v1.36.4@sha256:099e049362a1526b2db71494e1947aae99bd16290d7c895f2b7ea312e3cbfaed
sleep 15

docker exec -i tenant-a-worker sh -c 'cat > /root/tenant-a.kubeconfig'
Install Calico in the tenant (not the management cluster), with its pool set to the tenant podCidr:
curl -sLO https://raw.githubusercontent.com/projectcalico/calico/v3.31.2/manifests/calico.yaml

sed -i 's|# - name: CALICO_IPV4POOL_CIDR|- name: CALICO_IPV4POOL_CIDR|; s|#   value: "192.168.0.0/16"|  value: "10.244.0.0/16"|' calico.yaml

kubectl --kubeconfig tenant-a.kubeconfig apply -f calico.yaml

kubectl --kubeconfig tenant-a.kubeconfig get nodes
Step 5: HAMi and mock GPUs in the tenant # Don’t label the worker gpu=on; that starts HAMi’s real NVIDIA device plugin, which fails without a driver.
export KUBECONFIG=$PWD/tenant-a.kubeconfig
helm repo add hami-charts https://project-hami.github.io/HAMi/
helm install hami hami-charts/hami -n kube-system

# wait for hami-scheduler Running, and the hami-scheduler-device ConfigMap to exist

kubectl apply -f https://raw.githubusercontent.com/Project-HAMi/mock-device-plugin/master/k8s-mock-rbac.yaml

kubectl apply -f https://raw.githubusercontent.com/Project-HAMi/mock-device-plugin/master/k8s-mock-plugin.yaml

# Simulate 1 x A100 80 GB

NODE=tenant-a-worker

kubectl patch node $NODE --subresource=status --type=json \
 -p '[{"op":"add","path":"/status/capacity/nvidia.com~1gpu","value":"10"}]'

kubectl annotate node $NODE \
 'hami.io/node-nvidia-register=[{"id":"GPU-MOCK-0","count":10,"devmem":81920,"devcore":100,"type":"NVIDIA-A100-SXM4-80GB","health":true,"numa":0,"mode":"hami-core"}]'
About 30 seconds later the node advertises the fake card:
{

 "nvidia.com/gpu": "10",

 "nvidia.com/gpucores": "100",

 "nvidia.com/gpumem": "81920",

 "nvidia.com/gpumem-percentage": "100"

}
For tenant-b, repeat steps 4 and 5 with tenant-b names. Its annotation describes two cards (GPU-MOCK-B0 and GPU-MOCK-B1, 24,576 MB and 100 cores each), with nvidia.com/gpu capacity set to 20.
How a GPU pod gets scheduled
A GPU pod crosses from the management cluster into the tenant and back before it lands on a node, and that round trip is what makes the two projects work together. The dashed hop is the key integration point. The API server runs inside the management cluster, but HAMi’s webhook runs on the tenant worker, so the admission call travels through Kamaji’s Konnectivity tunnel. If that hop failed, GPU pods would fall back to the default scheduler and HAMi would never see them.
Test results
All eight tests passed. TC-03 and TC-05: three pods share one card Each pod asks for 20,000 MB and 30% of a GPU. This loop creates all three. After each pod is scheduled, it releases HAMi’s node lock by hand, because the mock plugin never does (see gotcha 2):
export KUBECONFIG=$PWD/tenant-a.kubeconfig

for i in 1 2 3; do
cat
The webhook routed the pod to HAMi, and HAMi placed it on the mock card:
$ kubectl get pod gpu-share-1 -o jsonpath='{.spec.schedulerName}'

Hami-scheduler

Annotations:  hami.io/vgpu-devices-allocated: GPU-MOCK-0,NVIDIA,20000,30:;

             hami.io/vgpu-node: tenant-a-worker

Events:

 Normal  FilteringSucceed  hami-scheduler  find fit node(tenant-a-worker), 0 nodes not fit, 1 nodes fit

 Normal  BindingSucceed    hami-scheduler  Successfully binding node [tenant-a-worker] to default/gpu-share-1
Three such pods ended up running on the same card: 60,000 MB and 90% of compute in use.
NAME          READY   STATUS    NODE
gpu-share-1   1/1     Running   tenant-a-worker
gpu-share-2   1/1     Running   tenant-a-worker
gpu-share-3   1/1     Running   tenant-a-worker
TC-06 and TC-07: HAMi refuses to over-commit A fourth 30% pod would need 120 of 100 cores:
cat
It stays Pending, and HAMi names the reason:
$ kubectl describe pod gpu-share-4 | sed -n '/Events/,$p'
Events:
 Type     Reason            Age                From            Message
 ----     ------            ----               ----            -------
 Warning  FailedScheduling  15s                hami-scheduler  0/1 nodes are available: 1 1/1 CardInsufficientCore. no new claims to deallocate, preemption: 0/1 nodes are available: 1 No preemption victims found for incoming pod.

 Warning  FilteringFailed   15s (x2 over 15s)  hami-scheduler  1 nodes CardInsufficientCore(tenant-a-worker)
 Warning  FilteringFailed   15s (x2 over 15s)  hami-scheduler  no available node, 1 nodes do not meet
A pod asking for 90,000 MB exceeds the 81,920 MB card:
cat
It stays Pending, this time with CardInsufficientMemory. TC-08: tenants can’t see each other Run the same queries against each tenant’s API server and compare what comes back:
for t in a b; do
 echo "===== tenant-$t ====="

 kubectl --kubeconfig tenant-$t.kubeconfig get nodes
 kubectl --kubeconfig tenant-$t.kubeconfig get pods -A | grep -E 'gpu-|NAME'
 kubectl --kubeconfig tenant-$t.kubeconfig get nodes -o json \
   | jq '.items[].status.allocatable | with_entries(select(.key|test("gpumem|gpucores")))'
done

===== tenant-a =====
NAME              STATUS   ROLES    AGE   VERSION
tenant-a-worker   Ready       29m   v1.36.4
NAMESPACE     NAME          READY   STATUS    RESTARTS   AGE
default       gpu-share-1   1/1     Running   0          14m
default       gpu-share-2   1/1     Running   0          12m
default       gpu-share-3   1/1     Running   0          12m
{
 "nvidia.com/gpucores": "100",
 "nvidia.com/gpumem": "81920",
 "nvidia.com/gpumem-percentage": "100"
}
===== tenant-b =====
NAME              STATUS   ROLES    AGE     VERSION
tenant-b-worker   Ready       5m28s   v1.36.4
NAMESPACE     NAME          READY   STATUS    RESTARTS   AGE
{
 "nvidia.com/gpucores": "200",
 "nvidia.com/gpumem": "49152",
 "nvidia.com/gpumem-percentage": "200"
}
Each tenant sees only its own worker, its own pods and its own GPU capacity: Both control planes run in the same management cluster, yet neither tenant’s API returns anything belonging to the other.
Gotchas and fixes
Few things broke along the way; each has a one-line fix.
- IPv6 on the kind network broke the MetalLB pool. The gateway lookup from the Kamaji guide printed fc00:f853:ccd:e793::1172.18.0.1, with the IPv6 and IPv4 gateways glued together. Fix: read the IPv4 subnet with docker network inspect kind | grep Subnet and write the range (172.18.255.200-172.18.255.250) directly.
- GPU pods stuck on “node lock contention”. After the first GPU pod, the next ones stayed Pending with:
Warning BindingFailed hami-scheduler node tenant-a-worker has been locked within 5m0s: node lock contention
HAMi locks a node while binding a pod and marks it hami.io/bind-phase: allocating. On real nodes, HAMi’s device plugin completes the allocation and releases the lock. The mock plugin doesn’t, so the lock only expires after 5 minutes. Fix for the lab: do the device plugin’s job by hand.
kubectl annotate pod gpu-share-1 hami.io/bind-phase=succe
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。