One GPU cluster across every cloud
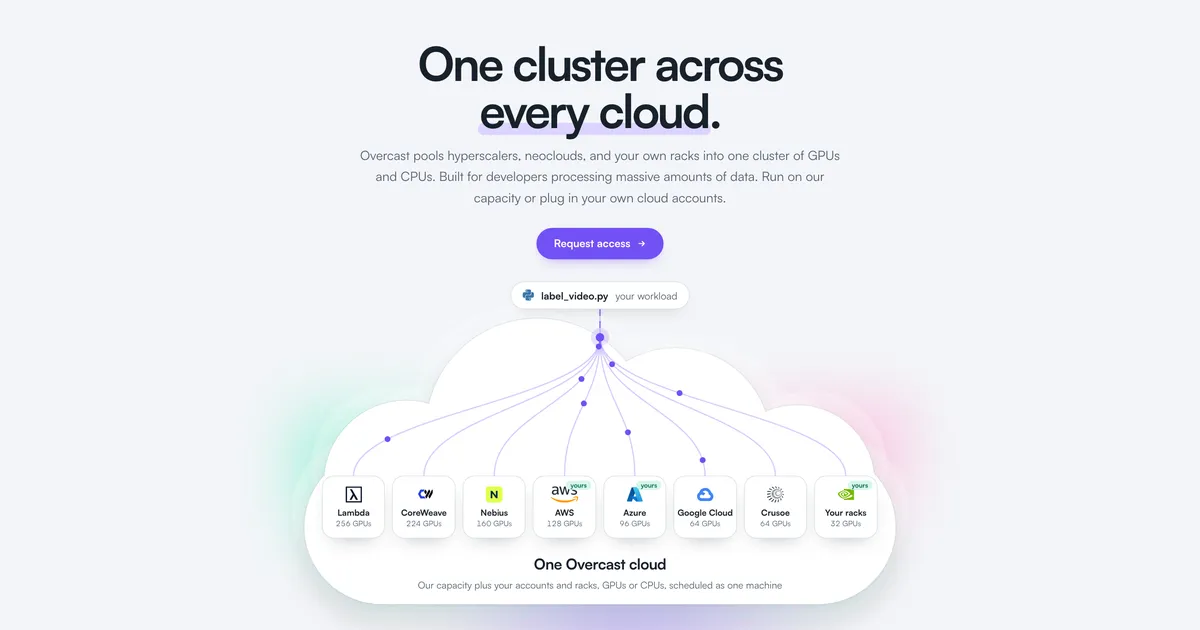
Overcast pools hyperscalers, neoclouds, and your own racks into one cluster of GPUs and CPUs. Built for developers processing massive amounts of data. Run on our capacity or plug in your own cloud accounts.
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
Overcast pools hyperscalers, neoclouds, and your own racks into one cluster of GPUs and CPUs. Built for developers processing massive amounts of data. Run on our capacity or plug in your own cloud accounts.
label_video.pyyour workload
Lambda256 GPUs
CoreWeave224 GPUs
Nebius160 GPUs
AWS128 GPUs
Azure96 GPUs
Google Cloud64 GPUs
Crusoe64 GPUs
Your racks32 GPUs
One Overcast cloud
Every provider, routed as one cluster
label_video.pyyour workload
Lambda256 GPUs
CoreWeave224 GPUs
Nebius160 GPUs
yoursAWS128 GPUs
yoursAzure96 GPUs
Google Cloud64 GPUs
Crusoe64 GPUs
yoursYour racks32 GPUs
One Overcast cloud
Hyperscalers, neoclouds, and your own accounts and racks, routed as one cluster
From one prompt to thousands of GPUs or CPUs.
1Install the skill
One line teaches your agent to use Overcast.
Mix our capacity with your clouds and racks.
ProvidersPriceSecuritySpeed
Lambda
CoreWeave
Nebius
AWSyours
Azureyours
Google Cloud
Crusoe
Your racksyours
Price. Each job goes where it costs least, counting the cost of moving your data.Security. Sensitive jobs stay on your own accounts and racks, in regions you approve.Speed. Every provider at once, for the most machines and the fastest finish.
Cursor writes the code. No hardware to size.
Every machine, GPU or CPU, and dollar in one view. When the job finishes, the cluster scales to zero.
Overcast
BBurla
Jobs
Providers
Machines128
Billing
Settings
Recent jobs
label_videoGPUbacktest_fxCPUalign_genomesCPUetl_clickstreamCPU
JPJoe Perryjoe@burla.dev
label_videobacktest_fxalign_genomesetl_clickstream
Jobs / label_video
Running
job_8f2k41 · started 12:04 by joe@burla.dev via Cursor · H100 · optimize for speed
View logsCancel job
Machines running
128
of 128, 1,024 GPUs
GPU utilization
80.2%
live
Throughput
823,319/s
frames
Spend
$8,970
cap $25,000
1,656,000,000 / 3,600,000,000 frames46% · 40 min left
Machines 128 / 128 receiving code running
Lambda80%
32 machines · 256 GPUs
CoreWeave81%
28 machines · 224 GPUs
Nebius81%
20 machines · 160 GPUs
AWSyours80%
16 machines · 128 GPUs
Azureyours80%
12 machines · 96 GPUs
Google Cloud80%
8 machines · 64 GPUs
Crusoe80%
8 machines · 64 GPUs
Your racks80%
4 machines · 32 GPUs
EventsLogsOutputsstreaming
12:04:03INFOrouteSpeed: all 8 providers at once
12:04:04INFOdeployShipping code to 128 machines
12:04:41INFOcluster128 machines running, 1,024 GPUs at 80% utilization
One cloud is a bottleneck.
Overcast gets you past capacity shortages and gives every workload more options on cost, speed, and security.
When your provider runs out of capacity in us-east-1, GPU or CPU, your job waits in a queue.
Overcast pools every provider into one cluster, so capacity is wherever it is cheapest right now.
A machine pulled mid-run means lost results and a retry loop you have to write yourself.
Reclaimed machines are replaced in seconds and every finished result is kept.
Clusters sit half-used between jobs while the meter keeps running.
The cluster scales to zero the moment a job finishes, and never spends past your cap.
Modeled from public list prices, not measured runs. See the math
Every job goes to the cheapest, most secure, or fastest compute. Then every machine you rent runs close to full, without running out of memory.
Overcast picks where it runs
Choose price, security, or speed for each job.
Small tasks fill each machine. When a big task needs more memory, Overcast gives it room and boots another machine for the small tasks.
Crashes when a big task runs out of memory
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。