CI/CD Pipeline Observability Tools: How to Choose the Right Setup
When a CI/CD pipeline fails, its dashboard can usually show you what went wrong. Pipeline observability tools should help you understand why, whether the cause is a flaky test, an overloaded build agent, or a problem el…
以下正文同步自 JetBrains Blog,版权归原站所有,已转换为易读排版。
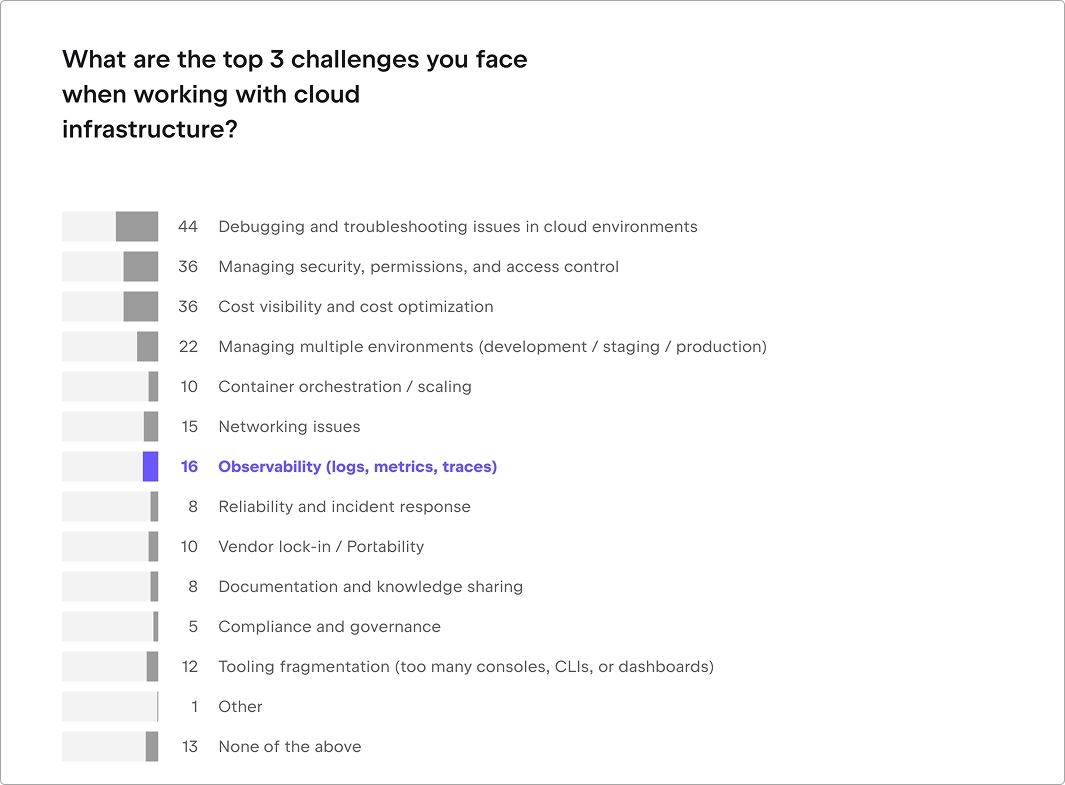
When a CI/CD pipeline fails, its dashboard can usually show you what went wrong. Pipeline observability tools should help you understand why, whether the cause is a flaky test, an overloaded build agent, or a problem elsewhere in the delivery process. This becomes harder as pipelines grow more complex. A pipeline touches a lot of separate systems: version control, build agents, containers, test frameworks, artifact repositories, security scanners, and deployment tools. Each one generates its own data, and pulling all of it together during an investigation isn’t easy. The JetBrains Developer Ecosystem Survey 2026 shows how common these challenges are. When we asked 20,416 respondents about their top three challenges when working with cloud infrastructure, 44% selected debugging and troubleshooting issues in cloud environments. Security and access control was selected by 36%, as was cost visibility and optimization. Observability was named by 16%, while 12% pointed to having too many separate tools, consoles, or dashboards. JetBrains Developer Ecosystem Report 2026 This article explains what CI/CD pipeline observability means, which metrics are worth tracking, and how the most common observability tools compare. It also provides a framework for choosing the right CI/CD observability tools for your team. What is CI/CD pipeline observability? CI/CD pipeline observability is the ability to understand the state and behavior of a delivery pipeline from the data it produces, including build results, metrics, logs, events, and traces. In practical terms, an observable pipeline should help you answer questions such as:
- Why are builds taking longer than they did last month?
- Why does one agent pool fail more frequently than another?
- Which pipeline stage introduced a regression?
- Did a code change cause the failure, or did something in the build environment change? Monitoring and observability are closely related, but they are not identical. Pipeline monitoring tracks known conditions. You define a metric or event, display it on a dashboard, and perhaps create an alert when it crosses a threshold. Observability helps when the cause of a problem is not immediately clear. It gives you enough connected data to investigate unexpected failures without first adding new tracking and waiting for the issue to occur again. For example, monitoring can show that build duration has suddenly increased. Observability helps you trace that increase to a particular pipeline, stage, build agent, commit, test, or infrastructure issue. TeamCity Performance Monitor What should you observe in a CI/CD pipeline? Pipeline observability covers both the work performed by the pipeline and the platform running it. At the pipeline level, these metrics fall into two groups: In the first, we’ve got queue time, total duration, and stage duration, which tell you where developers are kept waiting. In the other group, there are success rates, retries, flaky tests, and cache performance, which tell you where the pipeline itself is becoming less reliable. At the platform level, teams need visibility into agents or runners, CPU and memory consumption, disk and network activity, server health, and the availability of external dependencies. This context helps distinguish a code problem from an infrastructure problem. The most useful metrics are those connected to a concrete investigation. QuestionUseful signalsContext needed Are developers waiting longer for feedback?Queue time, pipeline duration, stage duration, median and 95th-percentile build durationRepository, branch, pipeline, stage, and agent pool Are pipelines becoming less reliable?Failure rate, retry rate, canceled runs, flaky-test rateFailure type, test, commit, and environment Is the build infrastructure keeping up with demand?Agent utilization, available agents, CPU, memory, disk, queue lengthAgent, pool, operating system, and executor type Is work being repeated unnecessarily?Cache hit rate, artifact reuse, repeated downloadsDependency, cache key, and build configuration What is driving CI infrastructure cost?Compute time, runner type, concurrency, storage, artifact volumeTeam, project, workload, and cloud resource Can a failure be tracked back to a change?Commit metadata, configuration changes, and dependency versionsRepository, pull request, and build run Percentiles are usually more informative than averages for duration and queue-time metrics. A stable average can conceal a poor experience for the slowest 5% or 10% of builds. Looking only at an overall success rate can hide problems. The number may appear healthy even if one branch, build-agent image, or test suite fails regularly. To find these patterns, teams need to be able to break metrics down by project, branch, pipeline stage, agent pool, environment, and failure type. Your CI/CD system is normally the best source for run identity and pipeline structure. For example, TeamCity statistic charts connect build duration, queue time, success rates, tests, artifacts, and other statistics to the underlying build configuration. This context becomes particularly valuable when CI data is exported to another observability system. Build configuration statistics in TeamCity How teams observe CI/CD pipelines in 2026 The State of Developer Ecosystem Survey 2026 asked 8,323 respondents which tools they use for CI/CD pipeline observability. Respondents could select more than one answer. JetBrains Developer Ecosystem Report 2026 Built-in CI/CD dashboards are the most common option, used by 76% of respondents. They are already part of the CI/CD platform, require little setup, and show pipeline runs, stages, tests, and failures in their original context. However, many teams use more than one observability tool. They might investigate a failed build in the CI/CD dashboard, use Prometheus and Grafana to monitor build infrastructure, and search logs in Elastic or OpenSearch. These tools are not direct alternatives: each provides a different type of information. Metrics show trends and changes over time, logs provide detailed records of what happened, and traces show how work moved through different parts of the pipeline. OpenTelemetry helps collect and send this data, but it still needs a separate system to store and display it. How to choose a CI/CD pipeline observability tool Most observability tools promise the same basics: dashboards, alerts, and some integrations. What actually separates them is what data they collect, how well that data stays connected to your pipelines, and how much work it takes to set them up and keep them running. The following five criteria can help you compare the options and choose the right fit for your team.
- Investigation depth and CI/CD context Think about the problems you want the tool to help you investigate. If a pipeline fails, can you quickly find the affected stage or test? Can you compare the failed run with earlier successful ones? To answer these questions, the tool needs to keep each metric, log, or trace connected to the relevant pipeline run. It should be possible to see which repository, branch, commit, stage, and environment the data came from. You may also need information about the pull request, build agent, test, or artifact involved. TeamCity’s AI Assistant helps analyze failed builds Built-in CI/CD dashboards are useful because they already have this context. When evaluating an external observability tool, check whether its integration keeps these connections or reduces the pipeline to a collection of unrelated metrics and logs.
- Correlation across systems A pipeline problem can come from many places, including a build runner, container, cloud service, artifact repository, external API, or deployment environment. A good observability tool should connect data from these systems, so that developers do not have to compare timestamps and search through several dashboards to understand what happened. This is especially useful for organizations that work with multiple CI/CD platforms or environments. According to the State of Developer Ecosystem Survey 2026, 22% of respondents find managing multiple environments challenging, while 12% struggle with having too many separate tools, consoles, or dashboards. An observability tool should bring this information together rather than add another disconnected dashboard.
- Setup and usability Different observability tools require different amounts of setup. A built-in CI/CD dashboard may work straight away, while external tools need to be connected to the pipeline and configured to collect, store, and display the right data. Distributed tracing may require additional changes to the pipeline itself. A more complex setup can be worthwhile if it gives your team the information it needs. However, you should consider how much work the tool will take to introduce and maintain. The tool should also be easy for developers to use. They are usually the first people to see a pipeline failure. If they cannot understand the data without help from the platform team, the tool will have limited value in everyday investigations.
- Security and deployment model The data collected from CI/CD pipelines may include repository and commit details, usernames, infrastructure addresses, and information about build environments. Build logs can also contain passwords, tokens, or other secrets if sensitive information is not properly hidden. It’s not a small concern, either: Security, permissions, and access control ranked as a top cloud challenge for 36% of survey respondents. Before choosing a tool, find out where it stores your data, how the data is protected when it is transferred, who can access it, and how long it is kept. Your organization may also need access controls, activity logs, encryption, a choice of data-storage region, or the ability to run the tool on its own infrastructure.
- Cost, maintenance, and portability The subscription or license price is only part of the total cost. Collecting large amounts of detailed metrics, logs, and traces can increase storage and processing costs. A self-hosted tool may reduce subscription fees, but your team will still need to provide the infrastructure, install updates, manage backups, and maintain the system. You should also consider how easy it would be to move your data to another tool. 10% of survey respondents cited vendor lock-in and portability as challenges in using cloud services. Open standards cannot make a migration effortless, but they can reduce the amount of data collection and pipeline configuration that must be rebuilt. Open-source, managed, or a combination? We often talk about open-source versus commercial platforms as though it’s a binary choice. But most teams have “a foot in both camps”, so to speak. Prometheus, Grafana, OpenSearch, and OpenTelemetry give you full control over hosting, data, and retention. You decide where it lives and how long it stays. The trade-off is that you’re also the one running and securing it. Commercial platforms take that job off your hands. You get useful data faster, but you’re paying through subscription and ingestion costs, and you’re trusting someone else with where your data is stored. Most teams don’t actually pick a side. A typical setup uses OpenTelemetry to collect the data, Prometheus for infrastructure metrics, and a managed platform for storage and analysis on top of both. Decide based on what your team already knows how to run and what questions you actually need answered, not based on whether a given platform is open-source or commercial. CI/CD pipeline observability tools compared The State of Developer Ecosystem Survey 2026 grouped observability tools by type. This means that the results show how widely each approach is taken, but not the usage of individual products. For example, 14% use a commercial observability platform, but the survey does not show how this percentage is divided among Datadog, New Relic, and Dynatrace. For this
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。