Show HN: Control – Data Observability for Postgres, Pipelines and CDC
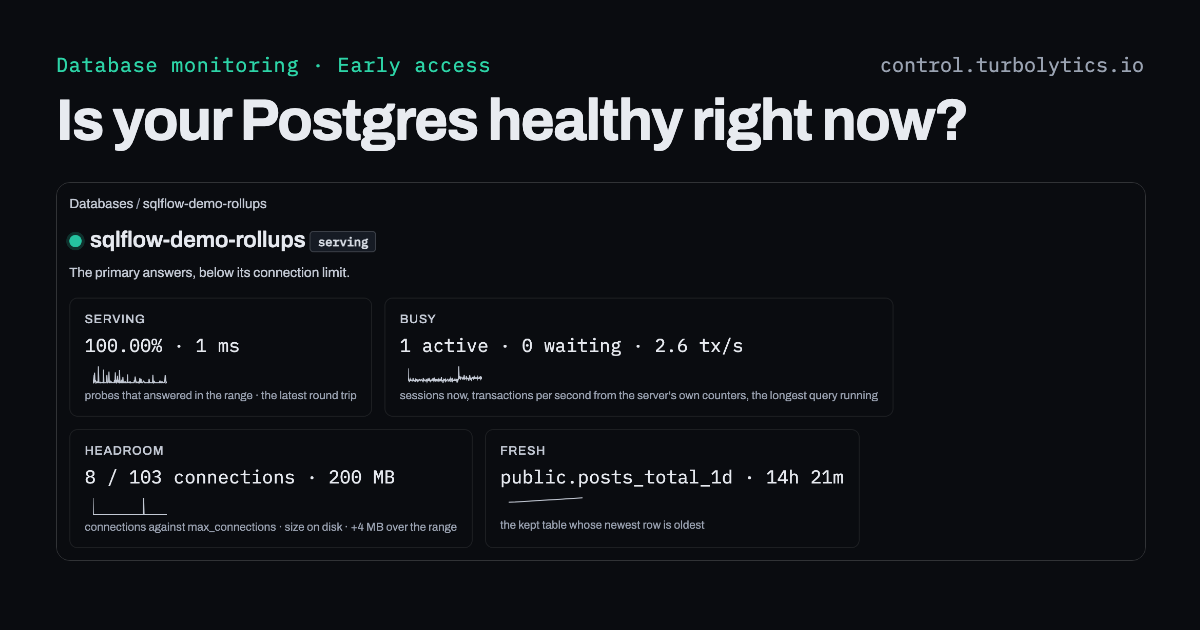
Hello Everyone! I built control.turbolytics.io for data observability.The goal is to provide a cost-effective way to monitor postgres and data pipelines at scale. Onboarding a new db takes minutes. Controls entire purpo…
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
Hello Everyone! I built control.turbolytics.io for data observability.The goal is to provide a cost-effective way to monitor postgres and data pipelines at scale. Onboarding a new db takes minutes. Controls entire purpose is to answer the question: "Are customers being affected?"I have experience operating pretty large data clusters and pipelines (100's of thousands of instances). Control takes these learnings and exposes them in the product:- SLO based alerts by default model that errors exist in reality
- Verdicts provide health classifications, instead of requiring the operator to read through 10's or hundreds of metrics.
- Flat pricing based on instances.
- The control observability protocol is pushed based and no customer or sensitive data is stored in control.How is everyone monitoring their databases and pipelines today? If you're using a big vendor, what's working for you? What's not?Looking forward to everyone's feedback,Thank you!Danny Comments URL: https://news.ycombinator.com/item?id=50287082 Points: 1
Comments: 0
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。