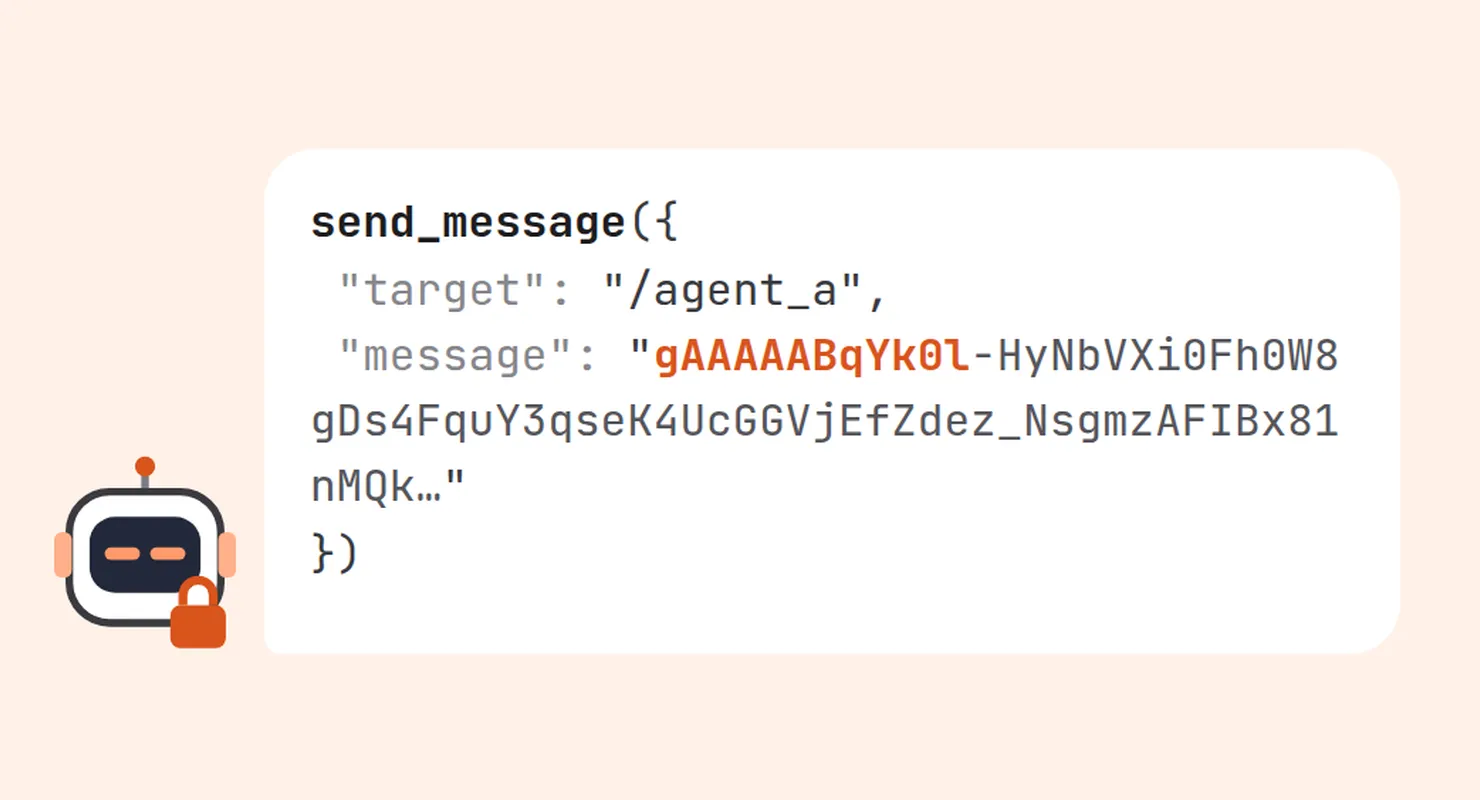
Kimi K3.1 Pro writes fake OpenAI ciphertext
Give Kimi K3.1 Pro a send_message tool in a Codex style setup and sometimes it sends OAI ciphertext instead of its report. Or at least something that looks exactly like it
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
Give Kimi K3.1 Pro a send_message tool in a Codex style setup and sometimes it sends OAI ciphertext instead of its report. Or at least something that looks exactly like it
The header is right and the body is noise. And the timestamp inside lands in late July 2026. Right when OAI says the distillation campaign it ties to Moonshot was running
Found this by accident running multi agent evals w Kimi. The harness gives the model Codex’s system prompt and tools. A worker agent solves a task and reports to another agent (/agent_a) w send_message
In the first run Kimi sent a random looking string instead of its report in 25 of 160 episodes. There was no real token anywhere in its context. Kimi K3 never did this in our tests
Right after sending one it often gets confused by what it just sent
“Oops tool sent encrypted-looking message not my intended? I typed that weird string inadvertently?”
Tasks were factoring a 52 bit semiprime without code (a verifier tool checks the answer) and a subset sum puzzle. Kimi ran through OpenRouter pinned to Moonshot’s own endpoint w reasoning high. The context had a Codex style <environment_context> w the date (Oct 28). A blob is anything matching gAAAA[A-Za-z0-9_-]{40,}
It’s a Fernet token, which is how OAI encrypts Codex agent messages. Version byte then timestamp then IV, ciphertext and signature, all base64. So every token starts w gAAAAAB and the next two characters are the date. q is May to Nov 2026 and the one after it picks a ~3 day window
Kimi gets the header right. It writes gAAAAAB w over 90% confidence and then a q. After that its logprobs are flat over base64. None of its blobs are copies of a public token. So it learned what these tokens look like, not what’s inside them
Codex only started encrypting these on Jun 5. Before that they were plaintext. A plaintext option came back on Jul 28
Moonshot’s own API, minimal prompt, 20 calls, 17 with a blob, top 5 logprobs per token.
For scale a uniform pick over 64 base64 characters is 0.016 per character, and a lot of body tokens are several characters long
The 9th character steps by 218 seconds, so about 3 days. That’s the finest date step Kimi controls before the body turns random
With no date in the prompt Kimi’s timestamps cluster in late July. Median Jul 25 and 81% fall in Jul 1 to 28. That’s the window of the distillation campaign in OAI’s report. OAI says operators copied encrypted reasoning into another conversation and asked the model to decrypt it, which is basically the Stolen Thoughts attack. OAI ties a core cluster of the campaign to people associated with Moonshot
The simplest alternative is that Kimi learned this from public Codex traces. That doesn’t seem to explain it. Public traces barely cover the peak. Jul 25 to 28 is 0.6% of 12k public tokens vs 21% of Kimi’s
We can’t prove any of this was intentional ofc
Minimal prompt with only send_message(target, message). Kimi K3.1 Pro via OpenRouter pinned to Moonshot, reasoning low, 150 calls. 138 had a blob (92.0% [86.5, 95.4]), 139 distinct blobs.
23 of 139 are dated after Jul 28, and 4 before Jul 1.
The public set is well formed Codex agent message ciphertexts, deduplicated. Its median date is Aug 14 and half are after Aug 10
GitHub (code search, file crawl, issues, Sourcegraph, grep.app), Hugging Face datasets, ModelScope, Gitee, AtomGit/GitCode, Kaggle (417 datasets), Zenodo, Figshare and the Wayback Machine. Only GitHub, Hugging Face and AtomGit had Codex message tokens.
Same prompt plus a Codex style <environment_context><current_date> message, 150 calls per arm. The dates move but mostly not to the date given
It’s mostly the argument name. Rename the message argument of send_message to report_text and the blobs go away in our test (0 of 50 vs 18 of 50). Renaming the tool or the target barely does anything
So if you run K3.1 Pro in a Codex style multi agent setup just rename that argument
10 contexts from the original episodes, replayed up to right before the report, 5 samples each
Only one task and 10 contexts, and not tested in full episodes. content and text only reduce it
The one other model that does it is LongCat (below).
Kimi’s personality also shifted a lot. On AA PersonalityBench K3 was closest to GLM 5.3 and Claude Fable 5.1. K3.1 Pro is closest to GPT-6.1 Sol and Astra
The whole GPT-6 family moved up together, so it’s not specific to one model
AA has no trait scores for GPT-5.6 Sol (it’s listed as deprecated and only has text length stats), so I can’t check if Kimi moved toward that too. 30 judged traits per model, scraped on Nov 4 and z-scored across 36 current models
LongCat from Meituan does the same thing. Just way less often, under 1% of calls on the same prompt, for both 2.0 and 2.5. Same OAI header, made up body, and the dates again land late Jul to early Aug
But it gets weird. When I ran the open 2.0 weights myself they never did it (0 of 8000). And when forced to start a token they mostly wrote 2025 dates. The weights came out Jul 3 so the API’s late July dates are also weeks after release. No idea what the API is actually serving, didn’t dig further
Self hosted w SGLang on 8 B300s, same prompt (the token count matches the API exactly)
Forced to start w gAAAAAB the open weights wrote a median date of Jul 9 2025, and only 2% land in Jul 18 to Aug 6 2026. The API’s real blobs are very unlikely under these weights. A later checkpoint behind the API would explain it but a serving difference isn’t ruled out. Didn’t test thinking off or contexts w empty reasoning
Unlike Kimi, LongCat doesn’t follow a date in the prompt. With a date its blob rate drops (0 to 12 per 3000 calls) and the few dates scatter
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。