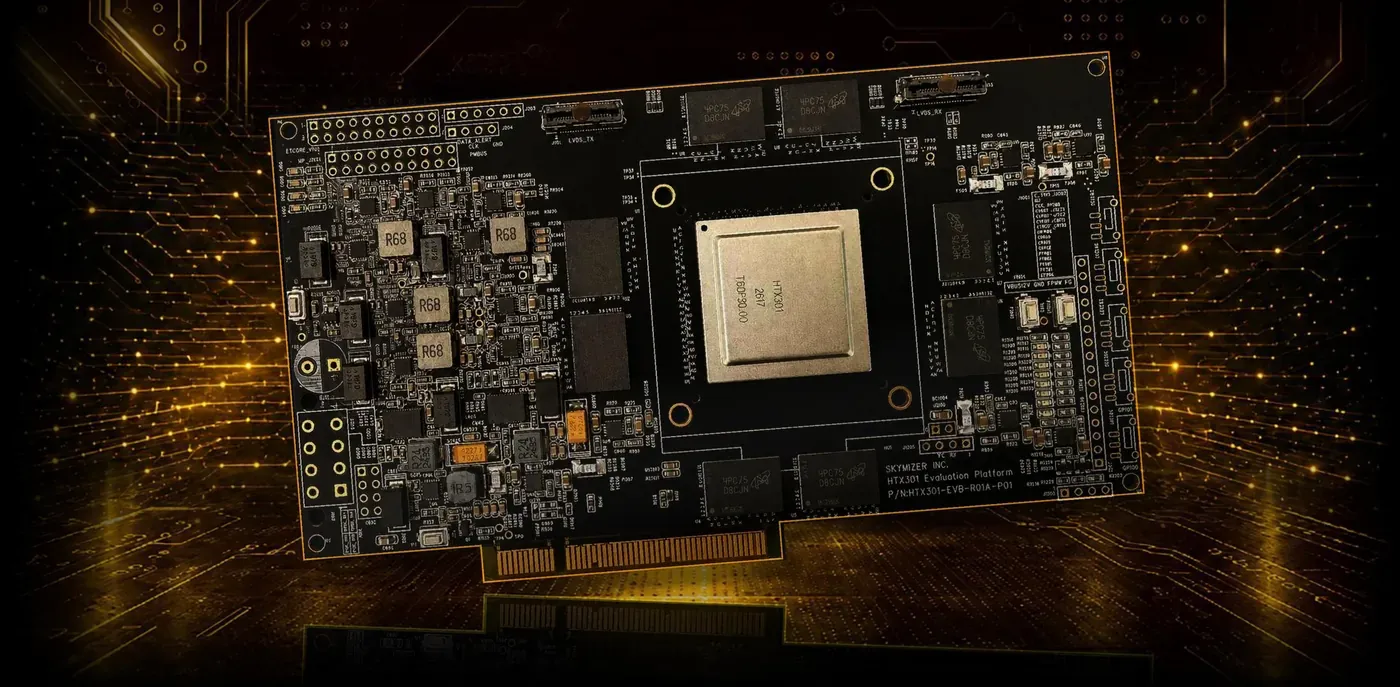
Skymizer HTX301 – IP Licensable AI Accelerator Card with 384GB for 700B Models
The first reference chip on the HyperThought™ platform to run ultra-large models on a single PCIe card.700B-parameter LLM inference, on-prem, at about 240W — no GPU cluster required.
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
The first reference chip on the HyperThought™ platform to run ultra-large models on a single PCIe card.700B-parameter LLM inference, on-prem, at about 240W — no GPU cluster required.
Ultra-large models don't need a superscalar GPU cluster. HTX301 disaggregates prefill and decode workloads and prioritizes a decode-first silicon design, using the LISA™ instruction set to scale from 4B to 700B parameters on the same architecture.
The result eliminates massive GPU clusters, NVLink/NVSwitch interconnects, and complex liquid cooling — delivering data sovereignty, predictable cost, and deterministic performance for agentic AI.
Skip NVLink/NVSwitch, multi-node orchestration, and the cooling that comes with them.
Inference never leaves your premises — data, weights, and prompts stay in-house.
One architecture from 4B to 700B; provision for the model you run, not the worst case.
Figures reflect the HTX301 reference platform and are subject to change ahead of general availability.
Built for ultra-large model inference with enterprise-grade privacy, power efficiency, and deployment simplicity. Register below and our team will follow up with specifications, evaluation details, and next steps.
We'll only use your details to respond to this request. See our Privacy Policy.
We'll reach out from sales@skymizer.ai with next steps for HTX301 preview access.
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。