Part 3: Knowing when your agent doesn’t know: the confidence layer
October 7, 2026Part 3: Knowing when your agent doesn’t know: the confidence layer
以下正文同步自 Stack Overflow Blog,版权归原站所有,已转换为易读排版。
October 7, 2026Part 3: Knowing when your agent doesn’t know: the confidence layer
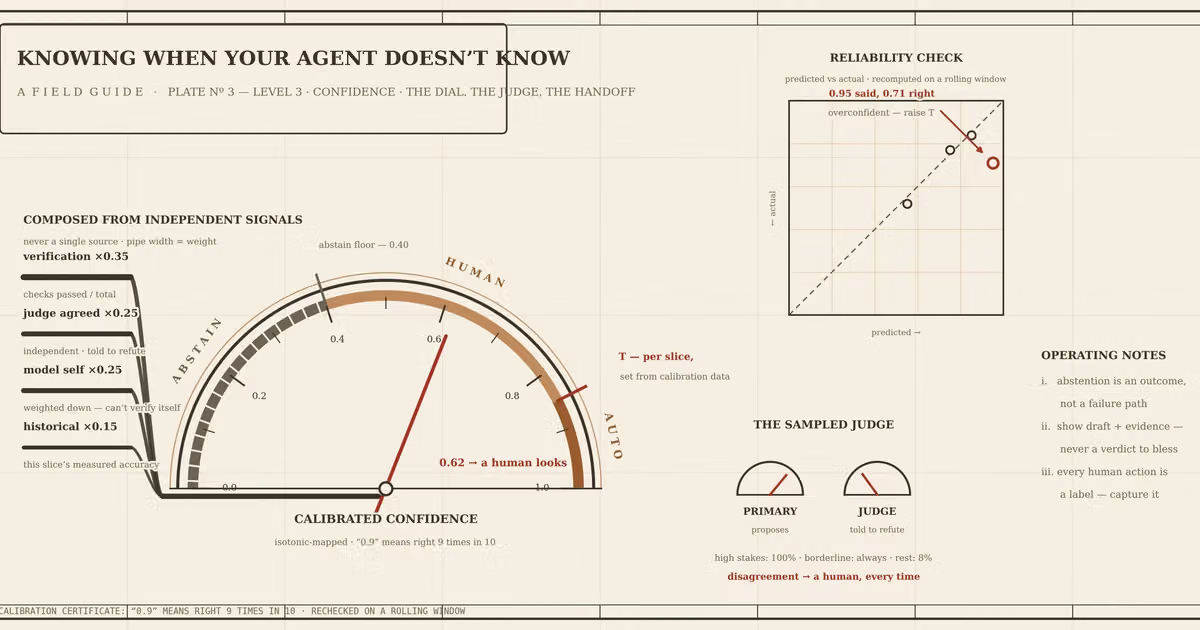
The most important number an agent produces isn’t its answer — it’s how sure it is. Compose that number from independent signals, check it’s calibrated, grade the high-stakes calls with a second model, and route the rest to humans well.
This is Level 3 of a six-level maturity model for running LLM systems in production. Levels 1 and 2 got you to where the system works and you can see it working. Level 3 is confidence: the system acts on its own only when its calibrated confidence is high, grades the decisions that matter with an independent judge, and routes everything it’s unsure about to a human in a way that actually catches errors.
These three things are one mechanism. Confidence is the dial that decides what runs automatically. A judge is one of the signals that dial is built from — and the trigger that pulls a decision off the automated path. The human handoff is where the dial sends everything below the line. Get all three right and you have a system that knows when it doesn’t know, and can therefore be trusted with more.
Ask most LLM systems “how sure are you?” and you get nothing useful — either no number, or the model’s self-reported confidence, which is notoriously miscalibrated (models are cheerfully certain when wrong). So you have to engineer a confidence signal. A production score is composed from independent signals, never lifted from the model’s own claim:
@dataclass class Signals: model_self: float # the model's own score — useful but weighted DOWN (overconfident) verification: float # fraction of deterministic checks passed (0..1) judge_agreed: bool | None # True/False if this decision was judged; None if not sampled (most aren't) historical: float # this slice's past accuracy (e.g. 0.99 vs 0.80)
WEIGHTS = {"model_self": 0.25, "verification": 0.35, "judge": 0.25, "historical": 0.15}
def compose(s: Signals) -> float:
only ~8% of decisions are judged. When judge_agreed is None, DROP the judge term and
renormalize the rest — an unjudged decision must not be penalized (False) or faked (True).
parts = {"model_self": s.model_self, "verification": s.verification, "historical": s.historical} if s.judge_agreed is not None: parts["judge"] = 1.0 if s.judge_agreed else 0.0 return sum(WEIGHTS[k] * v for k, v in parts.items()) / sum(WEIGHTS[k] for k in parts)
The exact weights matter less than the principle: a single source of confidence is a single point of failure. Note model_self is deliberately the smallest weight — a model that’s confidently wrong gets dragged down by failed verification or a disagreeing judge, so “confidently wrong” can’t on its own clear the bar. The three other signals are also the ones you can check: deterministic verification either passed or didn’t, the judge either agreed or didn’t, and historical accuracy is a measured fact about this slice. The model’s opinion of itself is the one input you can’t independently verify, which is exactly why it gets the least say.
A score is only useful if it’s calibrated — if “0.9” means “right ~90% of the time.” Check it: bucket decisions by predicted confidence and measure real accuracy per bucket (a reliability diagram).
predicted bucket mean predicted actual accuracy verdict
0.90 – 1.00 0.95 0.71 ⚠ overconfident — recalibrate / raise T 0.80 – 0.90 0.85 0.84 ✓ well-calibrated 0.70 – 0.80 0.75 0.77 ✓ < 0.70 0.55 0.52 ✓ (correctly unsure)
If your top bucket is right 71% of the time, your automation threshold is too loose. The binning that produces that table (and the gap to alert on):
def reliability(samples, bins=10): # samples: list[(confidence, was_correct: 0|1)] rows, ece, n = [], 0.0, len(samples) for b in range(bins): lo, hi = b/bins, (b+1)/bins last = (b == bins - 1) bucket = [s for s in samples if lo <= s[0] < hi or (last and s[0] == 1.0)] # top bin includes 1.0 if not bucket: continue conf = sum(c for c, _ in bucket) / len(bucket) acc = sum(ok for _, ok in bucket) / len(bucket) rows.append((round(lo, 1), round(conf, 3), round(acc, 3), len(bucket))) ece += (len(bucket) / n) * abs(conf - acc) return rows, ece
A weighted sum is not calibrated by construction — compose() returns a number in [0,1], not a probability. Close the loop: fit a monotonic map from raw composed score → empirical accuracy and route on that.
from sklearn.isotonic import IsotonicRegression calibrate = IsotonicRegression(out_of_bounds="clip").fit(raw_scores, correct) p_correct = calibrate.predict([composed])[0] # THIS is what the threshold compares against
Recompute on a rolling window — calibration drifts with the model and inputs. Prefer Brier score or the signed per-bucket gap over ECE for alerting (ECE is binning-sensitive and can read ~0 for a miscalibrated model). And mind the independence caveat: weighting historical slice-accuracy into compose()` and then calibrating per slice double-counts — encode slice reliability in one place, not both.
Once composed and calibrated, automation is a threshold — and the right T is per slice, set from the calibration data:
def route(conf: float, slice_key: str, thresholds: dict[str, float]) -> str: T = thresholds.get(slice_key, 0.95) # default conservative if conf < ABSTAIN_FLOOR: return "abstain" # too unsure to even recommend return "auto" if conf >= T else "hitl_recommended"
Routing here is a slimmed view of Level 1’s four-way vocabulary: abstain is a new floor below the human-review states (for inputs too uncertain to even pre-fill a draft), while Level 1’s reject (failed verification) and hitl_required` (very low confidence) still apply. Start T high (almost everything to a human), then lower it for a slice only once its calibration proves the band is safe. You can defend every automated band by pointing at the accuracy data that justified it.
The highest form of this is abstention — declining to decide. An agent that says “I’m not confident; a human should look” is more trustworthy than one that always answers. Make it a first-class outcome, not a failure path. It’s also your best defense against unknown unknowns: you can’t enumerate every weird input production will send, but a calibrated score plus an abstain floor means the weird ones fall through to a human automatically.
ABSTAIN_FLOOR = 0.40 # below this: don't even propose; escalate as "needs human"
The whole system tunes around three levers, and calibration data tells you which way to move each:
lever raise it lower it
threshold T fewer auto-errors, more human load more automation, more risk
model_self weight trusts the model more (risky) leans on verification/judge
abstain floor fewer bad auto-proposals, more escalations fewer escalations, more noise to humans
A few anti-patterns reliably wreck this layer: using raw model confidence as the dial (miscalibrated — compose instead); a single global threshold (different slices have wildly different accuracy); never re-checking calibration (it rots — a quarter-old threshold is a quarter-old risk model); and treating abstention as an error (it’s the system correctly recognizing its competence edge — measure it, don’t suppress it).
One of the signals in compose() was judge_agreed`. Here’s where it comes from — and it earns its own section, because for high-stakes decisions it’s the difference between a confident guess and a checked one.
A single model pass is a single point of failure. It’s confident when it’s wrong, it has characteristic blind spots, and you can’t tell a good answer from a plausible one by looking at the output. The cheap, effective insurance is a judge: a second, independent model that evaluates the first’s decision before you act on it.
@dataclass class Verdict: agrees: bool confidence: float failure_mode: str | None # if it disagrees, why
def judged_decision(inputs, primary_out, judge) -> Verdict: return judge.evaluate(inputs=inputs, proposed=primary_out) # narrow question: is this right?
Three design choices make it work.
Make the judge independent — and skeptical. If the judge is the same model with the same prompt, it shares the blind spots and rubber-stamps. Use a different model family where you can, a different framing, and prompt it to refute, not confirm.
You are a strict reviewer. You will be given INPUTS and a PROPOSED DECISION made by another system. Your job is to find the strongest reason the PROPOSED DECISION is WRONG, unsafe, or unsupported by the inputs. Do not be agreeable. If, after genuinely trying to refute it, you cannot, then agree.
Return JSON: {"agrees": bool, "confidence": 0..1, "failure_mode": string|null}
INPUTS: {{inputs}} PROPOSED DECISION: {{proposed}}
A judge told to refute catches far more than one told to approve — the framing does real work here, because an agreeable reviewer asked “is this right?” will find a way to say yes, while an adversarial one asked “where is this wrong?” surfaces the failure mode you’d otherwise only discover in production.
Sample — don’t judge everything. Judging doubles model cost. Spend it where stakes or uncertainty are high:
decision class judge policy
highest-impact / irreversible 100% judged borderline confidence (near threshold) always judged everything else random sample, e.g. 5–10% (a continuous quality probe)
def should_judge(d, thresholds, rate=0.08) -> bool: if d.stakes == "high": return True if abs(d.confidence - thresholds.get(d.slice, 0.95)) < 0.05: return True # borderline (per-slice T, safe default) return deterministic_hash(d.decision_id) % 10000 < rate * 10000 # deterministic + sub-1% safe
Treat disagreement as a routing signal — and a metric. When the judge disagrees, that decision goes to a human, every time. And the rate of disagreement is one of your best health signals — a spike means an attack, a bad deploy, or a model regression.
def combine(primary_out, verdict: Verdict) -> tuple: emit("judge_invocations_total") if not verdict.agrees and verdict.confidence >= 0.6: # confident refutation → human, every time emit("judge_disagreements_total") return route_to_human(primary_out, reason=verdict.failure_mode), False # judge_agreed = False if not verdict.agrees: # weak/low-confidence refutation: INCONCLUSIVE return primary_out, None # don't fake agreement — None makes compose() drop the judge term return primary_out, True # genuine agreement → judge_agreed = True for compose()
One gotcha will bite you: nondeterminism in tests. If the judge samples randomly and that path runs in your test suite, your tests become flaky — the same input judges on one run, not the next, so assertions intermittently fail. It looks like a mysterious bug; it’s your sampling rate leaking into a deterministic test. Pin the rate in tests, and use a deterministic hash of the decision id (not RNG) so even sampled behavior is reproducible:
production samples; tests pin the rate. Any randomness in an agent must be injectable.
judge = Judge(model=secondary, sampling_rate=0.0 if TESTING else 0.08)
You’re not making the model perfect; you’re building a system more reliable than any single call — on a judged decision, two independent models must agree before you act, and their disagreement is the system raising its hand. For the decisions that matter, it’s a remarkably cheap way to buy a lot of safety.
The dial and the judge both end at the same place: a decision routed to a person. But “route to a human” is where a lot of otherwise-good systems quietly fail — not in the model, in the handoff. Done well, the human is a genuine safety layer and a source of training signal. Done badly, you’ve built an “Approve” button people click without reading — worse than no human
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。