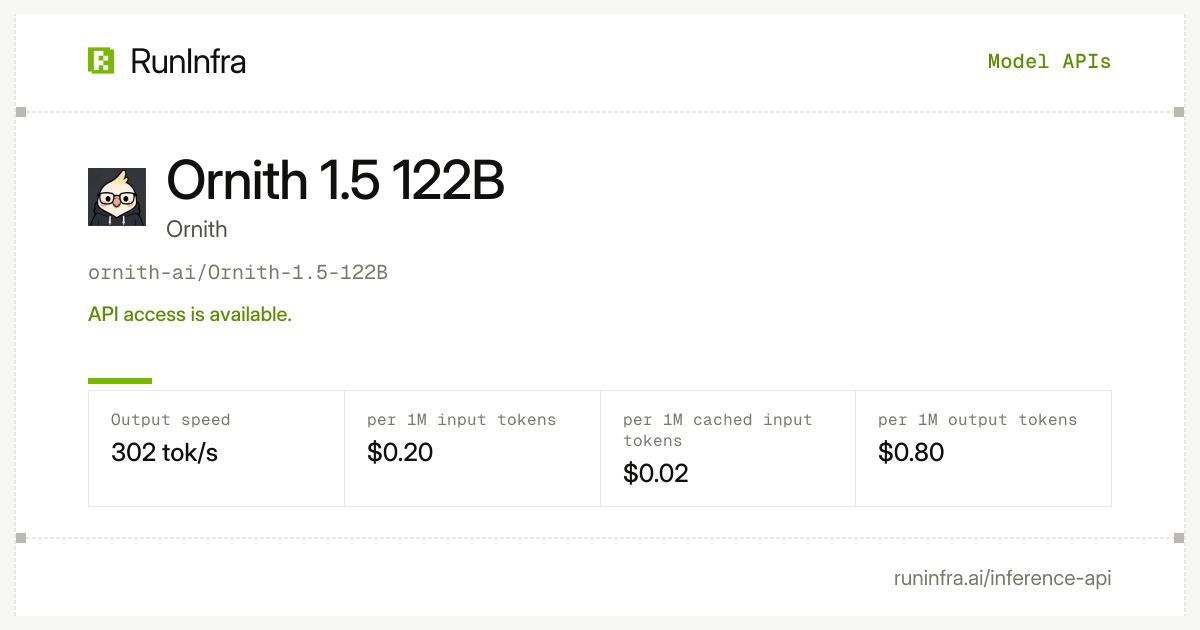
Ornith 1.5 122B at 302tps
Get API keyChat Completions API reference
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
Model Library
/
Ornith
/
Ornith 1.5 122B
Ornith 1.5 122B
ornith-ai/Ornith-1.5-122BShare
Get API keyChat Completions API reference
Ornith 1.5 122B is a mixture-of-experts reasoning model with about 10B active parameters. It takes text and image input. RunInfra serves it as ornith-ai/Ornith-1.5-122B at $0.20 per 1M input tokens and $0.80 per 1M output tokens. Its context window is 262,144 tokens. The API provides OpenAI-compatible chat completions and Anthropic-compatible Messages, POST /v1/messages.
Access
Confirm how your client reaches this model.
OpenAI-compatible chat completions
Anthropic compatibilityAnthropic-compatible Messages, POST /v1/messages
Accepted inputText and images
AvailabilityAvailable
Data retentionZero data retention by default. Never used for training.
Capacity
Check the limits your workload must fit.
262,144 tokens
Maximum request size3.5 MB per request
Maximum generated output262,144 tokens
Capabilities
See which request modes the API supports.
Supported
JSON modeSupported
StreamingSupported
PrecisionBF16, unquantized
View full specGateway compatibilityOpenAI- and Anthropic-compatible APIs for compatible clients, tools, and gateways
Prefix cachingAutomatic prefix caching runs on every replica, and requests from the same session or conversation are routed back to the replica that holds their cached prefix. A stable session hint or prompt_cache_key provides explicit grouping; otherwise RunInfra derives it from the start of the conversation or, failing that, the workspace. Hits remain best effort until eviction or a serve restart, never guaranteed. Cached input is billed at the cached input rate. Responses report cached token counts.
Cache retentionPrefix cache is held on the serving GPU and evicted under memory pressure. Retention is best effort.
Upstream modelView model
RunInfraby RightNow
© 2026 RunInfra. All rights reserved.
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。