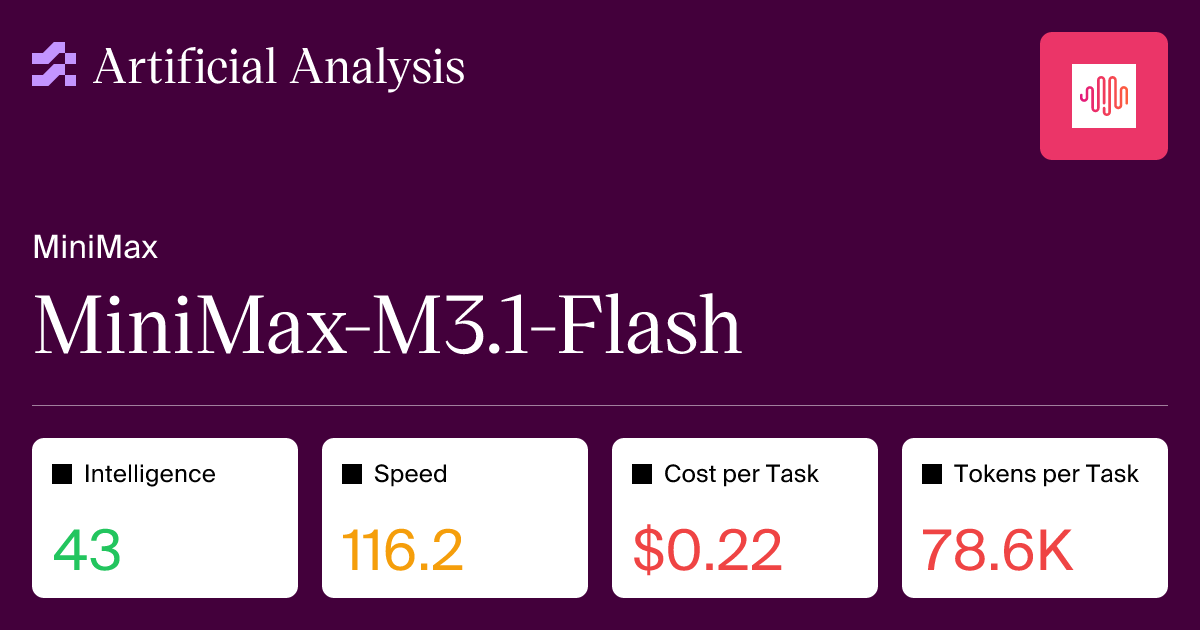
MiniMax-M3.1-Flash Artificial Analysis Performance and Price Analysis
CompareTry it out API Provider Benchmarks
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
Artificial AnalysisK
Artificial AnalysisModels
Coding Agents
Image, Speech, Video
Inference
Leaderboards
About
AI Trends
K
MiniMax
•Proprietary model
CompareTry it out API Provider Benchmarks
Model summary
Intelligence
#4 / 173
42
Artificial Analysis Intelligence Index
4 out of 4 units for Intelligence.
Speed
N/A
Output tokens per second
Unknown out of 4 units for Speed.
Cost
#50 / 66
In $0.15Out $0.60Cache Discount 90%
$0.22
Cost per Intelligence Index task
4 out of 4 units for Cost.
Verbosity
#54 / 68
180M
Output tokens from Intelligence Index
4 out of 4 units for Verbosity.
Comparison Summary
MiniMax-M3.1-Flash is amongst the leading models in intelligence and well priced when comparing to other models of similar price. The model supports text and image input, outputs text, and has a 1M tokens context window.
MiniMax-M3.1-Flash scores 42 on the Artificial Analysis Intelligence Index, placing it well above average among comparable models (median: 13). When evaluating the Intelligence Index, it generated 180M tokens, which is very verbose in comparison to the median of 99M.
Pricing for MiniMax-M3.1-Flash is $0.15 per 1M input tokens (competitively priced, median: $0.24) and $0.60 per 1M output tokens (moderately priced, median: $0.87). On average, it costs $0.22 per task to evaluate MiniMax-M3.1-Flash on the Intelligence Index.
ReasoningYesThis page shows the reasoning version of this model.
Context window1M~1500 A4 pages of size 12 Arial font
173 models in this class
Metrics are compared against models of the same class:
Intelligence
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 incorporates 10 evaluations: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1
27 of 706 models
Add model from specific provider
No publicly available API
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
27 of 706 models
Add model from specific provider
No publicly available API
ProprietaryOpen WeightsOpen Weights (Commercial Use Restricted)
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
Open Weights
Indicates whether the model weights are available. Models are labelled as 'Commercial Use Restricted' if commercial use is limited by conditions, and as 'Non-commercial' if the license prohibits commercial use.
27 of 706 models
Most attractive quadrant
Pareto line
StepFunZ AIXiaomiOpenAIAnthropicMistralMetaSpaceXAIReflectionGoogleAlibabaMiniMaxNVIDIADeepSeekKimi
Cost per Intelligence Index Task
Weighted average cost per Intelligence Index task. Each evaluation’s cost is calculated from input, cache hit, cache write, reasoning, and answer token prices, divided by task count, and weighted by its Intelligence Index weight.
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
Measures the performance of models on specific capabilities and industries
Incorporates 7 evaluations: AA-Omniscience, GDPval-AA v2.1, AA-Briefcase v1.1, Humanity's Last Exam, AutomationBench-AA, AA-LCR v1.1, GDP.pdf · Higher is better
27 of 225 models
Add model from specific provider
No publicly available API
Benchmarks
Evaluations
Intelligence evaluations measured independently by Artificial Analysis · Higher is better
CodingAgenticTool UsePrivate DatasetUser InteractionFinanceMedicalLegalIntelligence IndexLong ContextMultimodalInstruction FollowingFaithfulnessWritingBusinessSee more
19 of 28 evaluations27 of 706 models
Add model from specific provider
No publicly available API
AA-Briefcase v1.1Updated
Agentic knowledge work, (Elo-500)/2000
AA-Omniscience Non-Hallucination Rate
1 - hallucination rate
AutomationBench-AA
Agentic SaaS workflows
GDPval-AA v2.1Updated
Agentic real-world work tasks, (Elo-500)/2000
Humanity's Last Exam
Reasoning & knowledge
GDP.pdf
Professional document reasoning, All-pass
Terminal-Bench 4.0
Agentic coding & terminal use
Terminal-Bench-Science 0.1New
Agentic scientific research workflows in a terminal
FrontierCode 1.1New
Agentic software engineering in open-source repositories
AA-AnalystAgent
Quantitative analysis on spreadsheets & documents
Harvey LAB-AA v1.1Updated
Legal agentic work, Hallucination-Gated All-Pass Rate
EnterpriseOps-Gym-AA
Agentic business operations
ITBench-AA
Kubernetes incident root-cause analysis
Intelligence Evaluation Relevance
While model intelligence generally translates across use cases, specific evaluations may be more relevant for certain use cases.
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
27 of 235 models
Add model from specific provider
No publicly available API
AA-Briefcase Elo
AA-Briefcase Elo is a combined metric that aggregates analytical quality Elo, presentation Elo, and rubric pass rate, with rubric performance converted into Elo via synthetic head-to-head matches. Elo and 95% confidence interval bounds are clamped at 0.
27 of 580 models
Add model from specific provider
No publicly available API
AA-Omniscience Index
AA-Omniscience Index (higher is better) measures knowledge reliability and hallucination. It rewards correct answers, penalizes hallucinations, and has no penalty for refusing to answer. Scores range from -100 to 100, where 0 means as many correct as incorrect answers, and negative scores mean more incorrect than correct.
27 of 706 models
Most attractive quadrant
Pareto line
StepFunZ AIXiaomiOpenAIAnthropicMistralMetaSpaceXAIReflectionGoogleAlibabaMiniMaxNVIDIADeepSeekKimi
Cost per Intelligence Index Task
Weighted average cost per Intelligence Index task. Each evaluation’s cost is calculated from input, cache hit, cache write, reasoning, and answer token prices, divided by task count, and weighted by its Intelligence Index weight.
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
27 of 706 models
No publicly available API
AnswerReasoning
Output Tokens per Intelligence Index Task
The number of tokens required per Intelligence Index task. This is calculated by multiplying the output tokens per eval by the relative weights of each benchmark in the Intelligence Index, then dividing by task count (excluding repeats).
27 of 706 models
AnswerReasoningCache WriteCache HitInput
Cost per Intelligence Index Task
Weighted average cost per Intelligence Index task. Each evaluation’s cost is calculated from input, cache hit, cache write, reasoning, and answer token prices, divided by task count, and weighted by its Intelligence Index weight.
27 of 706 models
Add model from specific provider
OutputReasoningCache WriteCache ReadNon-Cache Input
Cost to Run Artificial Analysis Intelligence Index
The cost to run the evaluations in the Artificial Analysis Intelligence Index, calculated using the model's input, cache hit, cache write, reasoning, and answer token prices and the number of tokens used across evaluations (excluding repeats).
27 of 706 models
Add model from specific provider
Cache HitInputOutput
Cache Hit
Price per token for cached prompts (previously processed), typically offering a significant discount compared to regular input price, represented as USD per million tokens. The values shown here are the cache hit price; cache write and cache storage are billed separately and vary by provider — see "Cache pricing by provider" for detail.
4 more notes
Context Window
Context WindowIntelligence Index vs. Context Window
Context Window
Context window: tokens limit · Higher is better
27 of 706 models
Add model from specific provider
No publicly available API
Context Window for RAG
Larger context windows are relevant to RAG (Retrieval Augmented Generation) LLM workflows which typically involve reasoning and information retrieval of large amounts of data.
Context Window
Maximum number of combined input & output tokens. Output tokens commonly have a significantly lower limit (varied by model).
Common questions about MiniMax-M3.1-Flash
MiniMax-M3.1-Flash was released on October 19, 2026.
MiniMax-M3.1-Flash was created by MiniMax.
MiniMax-M3.1-Flash scores 42 on the Artificial Analysis Intelligence Index, placing it well above average among other models in a similar price tier (median: 13).
MiniMax-M3.1-Flash costs $0.15 per 1M input tokens (very competitive, median: $0.24) and $0.60 per 1M output tokens (better than average, median: $0.87), based on MiniMax's API.
MiniMax-M3.1-Flash costs $0.15 per 1M input tokens and $0.60 per 1M output tokens (based on MiniMax's API). For a blended rate (7:2:1 cache hit/input/output ratio), this is $0.10 per 1M tokens. Pricing may vary by provider. Compare provider pricing
When evaluated on the Intelligence Index, MiniMax-M3.1-Flash generated 180M output tokens, which is at the higher end compared to other models in a similar price tier (median: 99M).
Yes, MiniMax-M3.1-Flash is a reasoning model. It uses extended thinking or chain-of-thought reasoning to work through complex problems before providing an answer.
MiniMax-M3.1-Flash supports text and image input.
Yes, MiniMax-M3.1-Flash supports image input and can analyze, describe, and answer questions about images.
Yes, MiniMax-M3.1-Flash is multimodal. It can process text and image input and generate text output.
MiniMax-M3.1-Flash has a context window of 1.0M tokens. This determines how much text and conversation history the model can process in a single request.
No, MiniMax-M3.1-Flash is proprietary. The model weights are not publicly available.
MiniMax-M3.1-Flash is a proprietary model and MiniMax has not disclosed the model size or parameter count.
MiniMax-M3.1-Flash achieves a score of 42 on the Artificial Analysis Intelligence Index. This composite benchmark evaluates models across reasoning, knowledge, mathematics, and coding.
Yes, MiniMax-M3.1-Flash is available via API through 1 provider. Compare API providers
MiniMax-M3.1-Flash is available through 1 API provider. Compare providers
XLinkedInYouTubeRednoteDiscord
© 2026 Artificial Analysis
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。