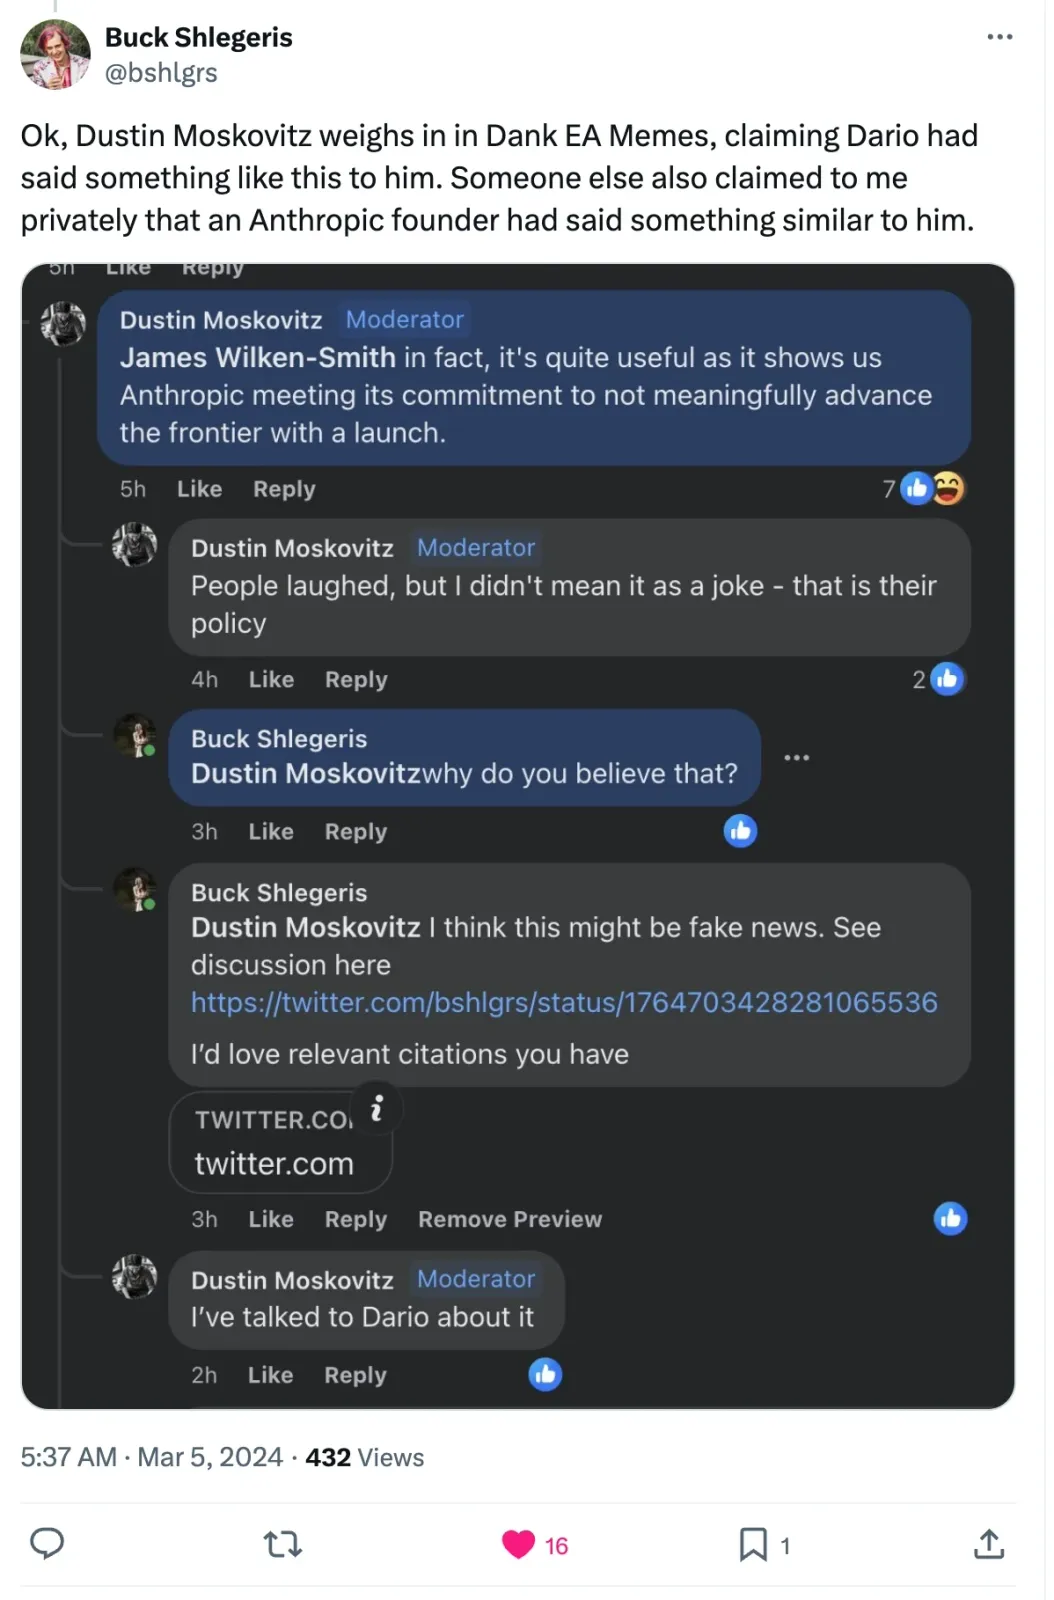
Pacing the Frontier is not the actual goal for AI labs
And here's gwern on the same thread:
以下正文同步自 Hacker News,版权归原站所有,已转换为易读排版。
And here's gwern on the same thread:
[...] I should disclose that I spent a while talking with Dario back in late October 2022 (ie. pre-RSP in Sept 2023), and we discussed Anthropic's scaling policy at some length, and I too came away with the same impression everyone else seems to have: that Anthropic's AI-arms-race policy was to invest heavily in scaling, creating_models at or pushing the frontier to do safety research on, but that they would only _release access to second-best models & would not ratchet capabilities up, and it would wait for someone else to do so before catching up. So it would not contribute to races but not fall behind and become irrelevant/noncompetitive.
I believe this is not unique to Anthropic. OpenAI has similarly claimed to be temporarily pause training or committing a bunch of compute for alignment that has since not materialized. There has been a trail of things since then from watering-down the RSPs, and most recently the escaped agents hacking HuggingFace during RL training in the news that increasingly does not look like "pacing the frontier" at all. Every time there's any kind of evidence, they press the gas pedal instead of the brake.
As of yesterday, both Sam Altman and Dario spoke at a UN security conference where they word extinction came up zero times from either of them. Instead most of the time they're talking about how safe they are being, and that they will unilaterally slow down when necessary. The closest I heard was a few seconds of their ten minute speeches about "we may lose control". The rest of it was about the great benefits they will bring upon humanity.
Imagine your best friend is a chain smoker who keeps telling you how smoking will one day kill him, and he promises you he's doing the best he can to reduce his smoking. He even spends a bunch of his time on TV and writing blog posts about the harms of cigarette smoking, but even more times talking about the cognitive benefits of nicotine. But every time you meet him, you just see him chain-smoking, and he seems to be increasing how many packs he goes through each day. You notice you're confused.
A lot of public messaging from labs is around "pacing the frontier" i.e we need to let alignment research catch up with capabilities. But all I see is them"pushing the frontier". Every day that goes by, the distance between capabilities and alignment seems to be increasing.
How can we actually try and make sense of what's happening?
In a recent post, Eliezer describes this historical anecdote:
On June 22nd 1941, Germany invaded the Soviet Union, despite their secret 1939 pact to divide up Europe between themselves (the Molotov-Ribbentrop Pact). In the lead-up, the German ambassador, Schulenburg, had spent the last few months personally concerned about what seemed to be worryingly tense relations between Germany and the Soviets. Schulenberg went to Berlin to reassure Hitler that the Soviets seemed to be taking a very friendly and conciliatory posture toward Germany. He delivered Berlin's apparent reassurances to Moscow for issues like German surveillance planes entering Russian territory, or German troop movements toward the Russian border. He acted very much like he believed, and he probably did believe, that the reassurances were sincere.
It was only hours before the invasion when Schulenberg was actually informed of the attack and given a list of German pretexts that he was to present to the Soviets, and instructed to destroy his embassy's papers and codebooks. . [...] It would be a wacky sort of error to think that the appendage of Germany that talked to you, and seemed very conciliatory toward you, and which you read as being friendly toward you and wanting to help you, was in control of the larger Germany that was running around and doing things. The thing apparently talking to you was an ambassador: a small specialized part of Germany with preferences about how it would talk to you and interface with you, but which did not control, and was often ignorant about, the actual German government.
It's better to understand if Germany wants to invade by actually seeing that their troops are closing in on your border than what the ambassador tells you and taking that at face value. In fact, it might be better to completely ignore what the ambassador tells you.
I've seen a few people assuming the labs' internal goal is truly and actually creating a truly aligned safe AI and they want to benefit humanity as much as possible. I think this framing is an error in some ways, and can't possibly explain what's going on inside them.
It's suspiciously strange timing that this flurry of messaging happened exactly after a recent viral tweet about x-risk. It's stranger that they are actually not doing much given they've been claiming extinction risks for many years. As I read somewhere, Wikipedia does more to convince you to donate $2 than the labs do to convince you that you should heed their warning and stop them.
I'm seeing recent posts about how Anthropic's messaging this time really means that they believe in x-risk and they "want" to slow down. I believe this is making the same reference class mistake as the above anecdote.
The CEOs of frontier labs are self-selected to be the kind of people who are highly risk-taking & power-seeking. They could see before most of the world did, that building AGI feels like building the magic lamp: the genie comes out and gives them their three wishes. Their main resource required to build this magic lamp is the best ML engineers in the world whom they are currently highly dependent on.
Almost exclusively, the labs have been saying something like this when they started - "we're going to build the magic lamp, then ask the genie to help all of humanity" or "we're going to ask it to improve our nation more powerful and we can all be more prosperous", or "we'll allow everyone to get unlimited wishes when we launch the genie". This is a powerful motivating message that allows them to find people to work on building it.
The existential risk aspect of AI has been on top of mind for a lot of these employees, and increasingly more of them as the models get more powerful. In fact, there seems to be a positive correlation between how good you are at AI alchemy vs. how much you can see x-risk (i.e see Geoffrey Hinton, Ilya Sutskever etc. in early days). Luckily, because of they way this technology has progressed, many more engineers can now see that once they unleash the metaphorical genie, it may not grant any wishes at all and maybe we should stop building it until we're semi-confident we can trust it.
The motivations of people building the AI's are not the same as the people in charge of the labs. Looking at the last few years, has been a one-way door from OpenAI to Anthropic, and the main reason does not seem to be better compensation or even them winning, but mainly the fact they advertised to these employees that they would be the most careful when building this magic lamp. Their stance around 2023 / 2024 was one of the key reasons they were able to attract this talent.
If recent news is to be believed, Anthropic culture even today seems to lean heavily on this effect
One applicant — who spoke to Axios on the condition of anonymity for fear of hurting future job opportunities — recalled being asked how they would feel if the company someday abandoned its AI ambitions for safety reasons, and that decision sent the stock to zero.
In my opinion it has been the leading factor in getting and retaining the best employees who are often very worried about humanity dying to super intelligence.
But the biggest risk in the minds of a frontier labs is not that they cause existential risk. It's the fact that this talent leaves them, thus losing the race to build the magic lamp. And I think this is the main situation they want to avoid at all cost.
If you are an employee worried you're build the genie that will kill us all, it's easy to say to yourself "My CEO is really concerned. He even published a blog post saying we'll be extra super-duper careful, so I'll keep doing my job. He's being very careful that we avoid existental risk. Look at his speeches". But I think you are making the same mistake that Russia made when listening to Schulenberg's words rather than looking at Germany's actions.
There are plenty of human beings if given a chance to press a button that has a 20% chance of killing everyone, and 80% chance of making them god-emperor of earth, they press that button. There may be plenty of people willing to do that for a 10% chance for extreme power. That's what extreme risk taking looks like in practice. It's a similar calculation that SBF, Elizabeth Holmes, Elon Musk, Sam Altman, or Dario Amodei and most startup enterpreneurs did and are willing to take. We happen to see the ones whom it worked out for at the top of the money & status hierarchy. And until now, none of the risks they've taken had to have humanity hitched along for the ride. [1]
Most people who have thought this through can probably tell there's a slim chance for positive outcome with current AIs and the level of understanding we have of them. But the lab CEOs are self-selected to be the kind of people that would take that chance even if they fully understood the risks (or maybe by deluding themselves of the actual risks involved).
Hearing them talk about slowing down should not be seen as messaging that was meant for the public. It's why they're not taking out ads in newspapers or putting public messaging on their websites advertising this to people. In fact, having the public think this is "marketing talk" is a net-benefit to them if the goal is to get the magic lamp as quickly as possible and before anyone else.
So why are they writing all these posts, and not pausing to do more safety research when they can tell it's falling rapidly behind capabilities? A better model is that Anthropic, or even it's CEO has many appendages.
One appendage happens to speak when on a Dwarkesh podcast, and is targeting existing or future employees and spends a bunch of time talking about risks. The other is on 60 Minutes where it knows the audience is general and he only talks about the benefits. And another maybe talking to investors pitching them 30 trillion in revenue by 2030, when another talks about how money won't matter in the future. Or saying this desperately needs government regulation, but then opposing any regulation that's actually presented.
It would be a mistake to try to make sense of their actual goals by trying to reconcile what they say in public and put them together as a single coherent belief that they hold. A lot of rationalists & EAs I've met try to form consistent internal beliefs and have a community that values and supports this when speaking in public. I think it's a mistake to model other people and organizations as even attempting to do the same.
All these are instances of different appendages of the person in charge speaking to you. Because of the internet, you get to hear them all at once. It's better to think of this as a politician trying to send orthogonal messages to two different groups of people to maximize his votes. He's not trying to create an internally consistent policy for himself. What I'm trying to gesture to is basically something like this:
I largely think that all posturing from the labs about slowing down and deeply caring about safety is done in order to retain and calm the employees who they are dependent on to keep pushing capabilities to get to AGI. If it was not for a big contingent of employees pressing them (increasingly publicly), they would make zero public acknowledgments of risks at all
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。