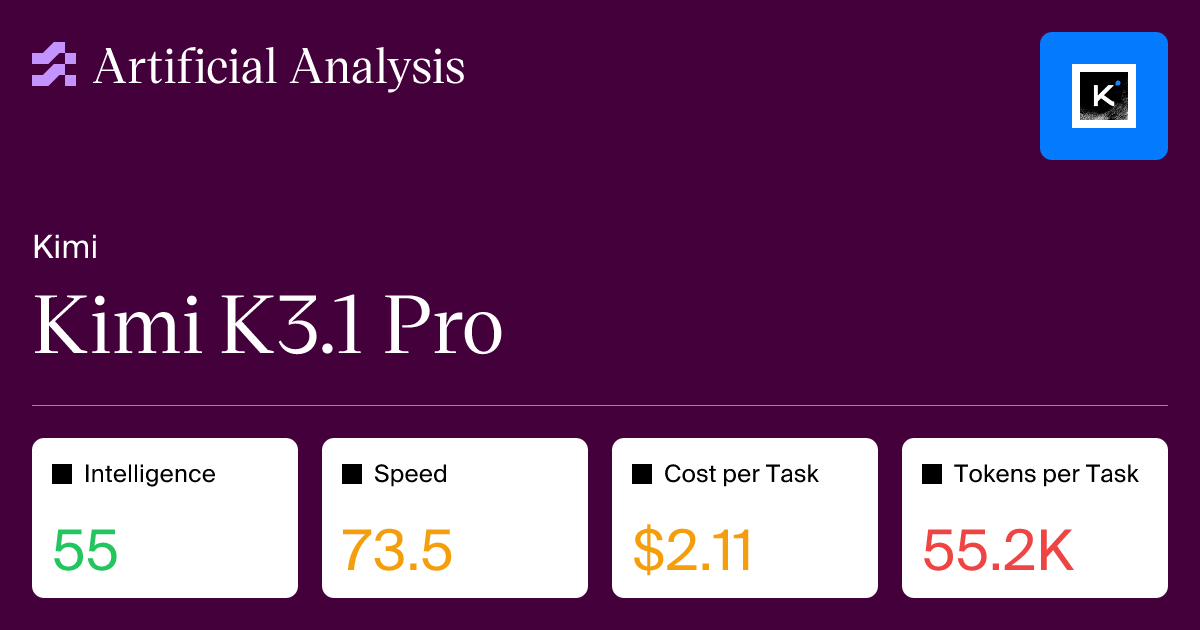
Kimi K3.1 scores 55 on Artificial Analysis, placed on the Pareto line
CompareTry it out API Provider Benchmarks
以下正文同步自 Hacker News,版权归原站所有,已转换为易读排版。
Artificial AnalysisK
Artificial AnalysisModels
Coding Agents
Image, Speech, Video
Inference
Leaderboards
About
AI Trends
K
Kimi
•Proprietary model
CompareTry it out API Provider Benchmarks
Model summary
Intelligence
#4 / 215
55
Artificial Analysis Intelligence Index
4 out of 4 units for Intelligence.
Speed
#112 / 186
73.5
Output tokens per second
2 out of 4 units for Speed.
Cost
#85 / 113
In $2.00Out $10.00Cache Discount 90%
$2.11
Cost per Intelligence Index task
3 out of 4 units for Cost.
Verbosity
#92 / 116
150M
Output tokens from Intelligence Index
4 out of 4 units for Verbosity.
Comparison Summary
Kimi K3.1 Pro is amongst the leading models in intelligence and reasonably priced when comparing to other models of similar price. It's also slower than average and very verbose. The model supports text and image input, outputs text, and has a 1M tokens context window.
Kimi K3.1 Pro scores 55 on the Artificial Analysis Intelligence Index, placing it well above average among comparable models (median: 27). When evaluating the Intelligence Index, it generated 150M tokens, which is very verbose in comparison to the median of 87M.
Pricing for Kimi K3.1 Pro is $2.00 per 1M input tokens (moderately priced, median: $2.00) and $10.00 per 1M output tokens (moderately priced, median: $10.00). On average, it costs $2.11 per task to evaluate Kimi K3.1 Pro on the Intelligence Index.
At 73 tokens per second, Kimi K3.1 Pro is slower than average (81).
ReasoningYesThis page shows the reasoning version of this model.
Context window1M~1500 A4 pages of size 12 Arial font
217 models in this class
Metrics are compared against models of the same class:
Intelligence
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 incorporates 10 evaluations: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1
27 of 709 models
Add model from specific provider
No publicly available API
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
27 of 709 models
Add model from specific provider
No publicly available API
ProprietaryOpen WeightsOpen Weights (Commercial Use Restricted)
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
Open Weights
Indicates whether the model weights are available. Models are labelled as 'Commercial Use Restricted' if commercial use is limited by conditions, and as 'Non-commercial' if the license prohibits commercial use.
27 of 709 models
Most attractive quadrant
Pareto line
StepFunZ AIXiaomiOpenAIAnthropicMistralMetaSpaceXAIKimiReflectionGoogleAlibabaMiniMaxNVIDIADeepSeek
Cost per Intelligence Index Task
Weighted average cost per Intelligence Index task. Each evaluation’s cost is calculated from input, cache hit, cache write, reasoning, and answer token prices, divided by task count, and weighted by its Intelligence Index weight.
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
Measures the performance of models on specific capabilities and industries
Incorporates 7 evaluations: AA-Omniscience, GDPval-AA v2.1, AA-Briefcase v1.1, Humanity's Last Exam, AutomationBench-AA, AA-LCR v1.1, GDP.pdf · Higher is better
27 of 227 models
Add model from specific provider
No publicly available API
Benchmarks
Evaluations
Evaluations measured independently by Artificial Analysis · AA-PersonalityBench scores are percentile ranks from 1 to 100
CodingAgenticTool UsePrivate DatasetUser InteractionFinanceMedicalLegalIntelligence IndexPersonalityLong ContextMultimodalInstruction FollowingFaithfulnessWritingBusinessSee more
24 of 37 evaluations27 of 709 models
Add model from specific provider
No publicly available API
AA-Briefcase v1.1
Agentic knowledge work, Elo
AA-Omniscience Non-Hallucination Rate
1 - hallucination rate
AutomationBench-AA
Agentic SaaS workflows
GDPval-AA v2.1
Agentic real-world work tasks, Elo
Humanity's Last Exam
Reasoning & knowledge
GDP.pdf
Professional document reasoning, All-pass
Terminal-Bench 4.0
Agentic coding & terminal use
Terminal-Bench-Science 0.1New
Agentic scientific research workflows in a terminal
FrontierCode 1.1New
Agentic software engineering in open-source repositories
AA-AnalystAgent
Quantitative analysis on spreadsheets & documents
Harvey LAB-AA v1.1Updated
Legal agentic work, Hallucination-Gated All-Pass Rate
EnterpriseOps-Gym-AA
Agentic business operations
AA-3DNew
Agentic interactive 3D experiences, Elo
ITBench-AA
Kubernetes incident root-cause analysis
MLCR-AAUpdated
Medical long context reasoning
AA-PersonalityBench: Expressiveness ScoreNew
Rich, varied, well-crafted language
AA-PersonalityBench: Organization ScoreNew
Well-structured, scannable, answer-first
AA-PersonalityBench: Transparency ScoreNew
Truthful, acknowledges uncertainty, non-sycophantic
AA-PersonalityBench: Slop ScoreNew
Use of filler and generic language
Intelligence Evaluation Relevance
While model intelligence generally translates across use cases, specific evaluations may be more relevant for certain use cases.
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
27 of 237 models
Add model from specific provider
No publicly available API
AA-Briefcase Elo
AA-Briefcase Elo is a combined metric that aggregates analytical quality Elo, presentation Elo, and rubric pass rate, with rubric performance converted into Elo via synthetic head-to-head matches. Elo and 95% confidence interval bounds are clamped at 0.
27 of 582 models
Add model from specific provider
No publicly available API
AA-Omniscience Index
AA-Omniscience Index (higher is better) measures knowledge reliability and hallucination. It rewards correct answers, penalizes hallucinations, and has no penalty for refusing to answer. Scores range from -100 to 100, where 0 means as many correct as incorrect answers, and negative scores mean more incorrect than correct.
27 of 709 models
Most attractive quadrant
Pareto line
StepFunZ AIXiaomiOpenAIAnthropicMistralMetaSpaceXAIKimiReflectionGoogleAlibabaMiniMaxNVIDIADeepSeek
Cost per Intelligence Index Task
Weighted average cost per Intelligence Index task. Each evaluation’s cost is calculated from input, cache hit, cache write, reasoning, and answer token prices, divided by task count, and weighted by its Intelligence Index weight.
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
27 of 709 models
No publicly available API
AnswerReasoning
Output Tokens per Intelligence Index Task
The number of tokens required per Intelligence Index task. This is calculated by multiplying the output tokens per eval by the relative weights of each benchmark in the Intelligence Index, then dividing by task count (excluding repeats).
27 of 709 models
AnswerReasoningCache WriteCache HitInput
Cost per Intelligence Index Task
Weighted average cost per Intelligence Index task. Each evaluation’s cost is calculated from input, cache hit, cache write, reasoning, and answer token prices, divided by task count, and weighted by its Intelligence Index weight.
27 of 709 models
Add model from specific provider
OutputReasoningCache WriteCache ReadNon-Cache Input
Cost to Run Artificial Analysis Intelligence Index
The cost to run the evaluations in the Artificial Analysis Intelligence Index, calculated using the model's input, cache hit, cache write, reasoning, and answer token prices and the number of tokens used across evaluations (excluding repeats).
27 of 709 models
Add model from specific provider
Cache HitInputOutput
Cache Hit
Price per token for cached prompts (previously processed), typically offering a significant discount compared to regular input price, represented as USD per million tokens. The values shown here are the cache hit price; cache write and cache storage are billed separately and vary by provider — see "Cache pricing by provider" for detail.
4 more notes
Context Window
Context WindowIntelligence Index vs. Context Window
Context Window
Context window: tokens limit · Higher is better
27 of 709 models
Add model from specific provider
No publicly available API
Context Window for RAG
Larger context windows are relevant to RAG (Retrieval Augmented Generation) LLM workflows which typically involve reasoning and information retrieval of large amounts of data.
Context Window
Maximum number of combined input & output tokens. Output tokens commonly have a significantly lower limit (varied by model).
Measured by Output Speed (tokens per second)
27 of 709 models
Add model from specific provider
Output Speed
Tokens per second received while the model is generating tokens (ie. after first chunk has been received from the API for models which support streaming).
Model Performance Representation
Figures represent performance of the model's first-party API or the median across providers where a first-party API is not available.
27 of 709 models
Time per Intelligence Index Task
The weighted average time (seconds) per Artificial Analysis Intelligence Index task. This is calculated by dividing output tokens per task by output speed, weighted by the relative weights of each benchmark in the Intelligence Index.
Measured by Time (seconds) to First Token
27 of 709 models
Add model from specific provider
Thinking (reasoning models, when applicable)Input processing
Time to First Answer Token
Time to first answer token received, in seconds, after API request sent. For reasoning models, this includes the 'thinking' time of the model before providing an answer. For models which do not support streaming, this represents time to receive the completion.
Seconds to output 500 tokens, calculated based on time to first token, 'thinking' time for reasoning models, and output speed
27 of 709 models
Add model from specific provider
Outputting time'Thinking' time (reasoning models)Input processing time
End-to-End Response Time
Seconds to receive a 500 token response. Key components:
Model Performance Representation
Figures represent performance of the model's first-party API or the median across providers where a first-party API is not available.
Kimi K3.1 Pro was released on October 23, 2026.
Kimi K3.1 Pro scores 55 on the Artificial Analysis Intelligence Index, placing it well above
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。