We turned EmbeddingGemma 2 into a speech-to-text model
Google's EmbeddingGemma 2 is an embedding model. We turned it into a speech-to-text model:
以下正文同步自 Hacker News,版权归原站所有,已转换为易读排版。
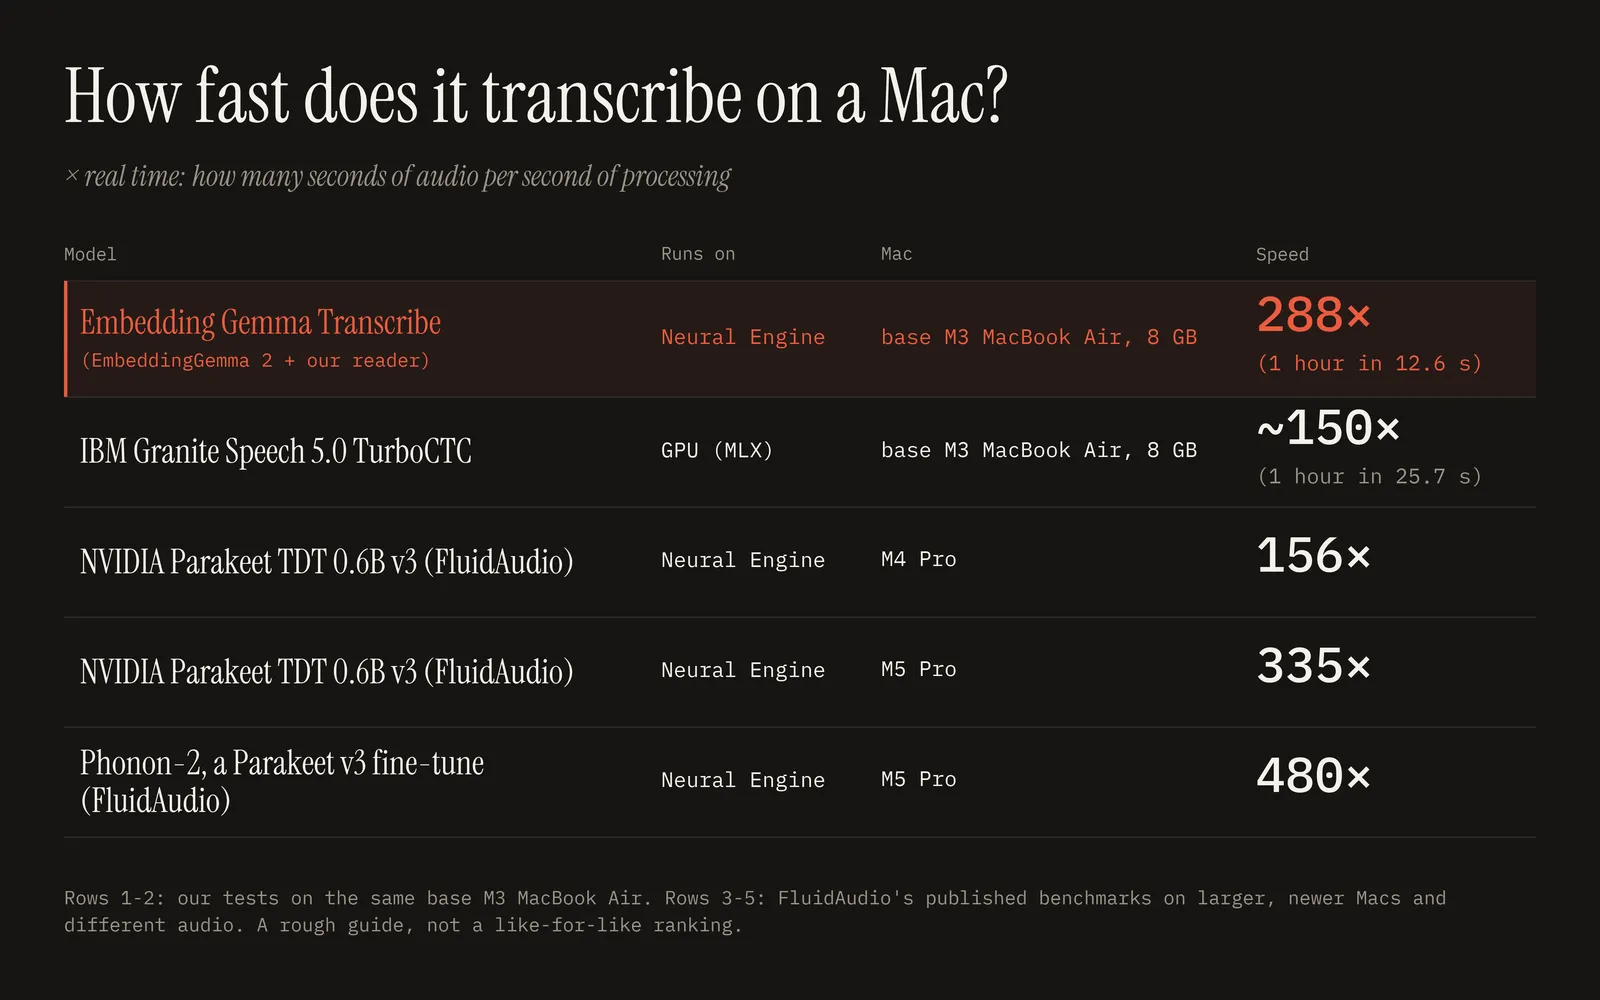
Google's EmbeddingGemma 2 is an embedding model. We turned it into a speech-to-text model: an hour of audio in about 13 seconds on a base MacBook Air, entirely on device.
EmbeddingGemma 2 is a multimodal embedding model: text, images, audio and video in one shared space. Say a word out loud and its audio lands close to the written word.
So we tried reading words straight out of that space.
Only the reader is trained: under two hours on 8×H100, on openly licensed English speech. The base model was never trained for speech-to-text.
× real time: seconds of audio per second of processing. Rows 1–2: our tests on the same base M3 MacBook Air. Rows 3–5: FluidAudio's published benchmarks on larger, newer Macs and different audio. A rough guide, not a like-for-like ranking.
Its word error rate is about 5% right now, against 2–3% for leading speech models. We believe a better-trained reader can close that gap; that's the next iteration.
Drop in an audio file, or hold Right Option, speak and release to dictate into any app. It runs on the Mac's Neural Engine; your audio never leaves the machine.
EmbeddingGemma 2 is made by Google DeepMind and released under Apache 2.0. This is an independent project, not affiliated with or endorsed by Google.
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。