Part 1: Make your AI agents boring: the determinism layer
October 7, 2026Part 1: Make your AI agents boring: the determinism layer
以下正文同步自 Stack Overflow Blog,版权归原站所有,已转换为易读排版。
October 7, 2026Part 1: Make your AI agents boring: the determinism layer
The trick to putting LLM agents in high-stakes systems isn’t a smarter model — it’s containing the model to one node so the rest of the system is ordinary, testable code. Here are the structural moves, with the contracts and types to implement them.
Demos love autonomous agents that loop, call tools, and “figure it out.” Production hates them. The moment an agent’s behavior depends on which path the model wandered down today, you can’t test it, can’t audit it, and can’t let it touch anything that matters. In a regulated or high-consequence system — money movement, healthcare, infrastructure — “it usually works” is a non-starter.
This is Level 1 of a six-level maturity model for running LLM systems in production: the determinism layer. Before you can do evals, confidence routing, or anything else higher up the stack, you need the part underneath to hold still. The whole game at this level is one idea — contain the model to a single node so everything around it is ordinary, testable code — expressed through a handful of design moves. You keep the model’s intelligence and remove almost all of the unpredictability. This post gives the contracts, not just the concepts.
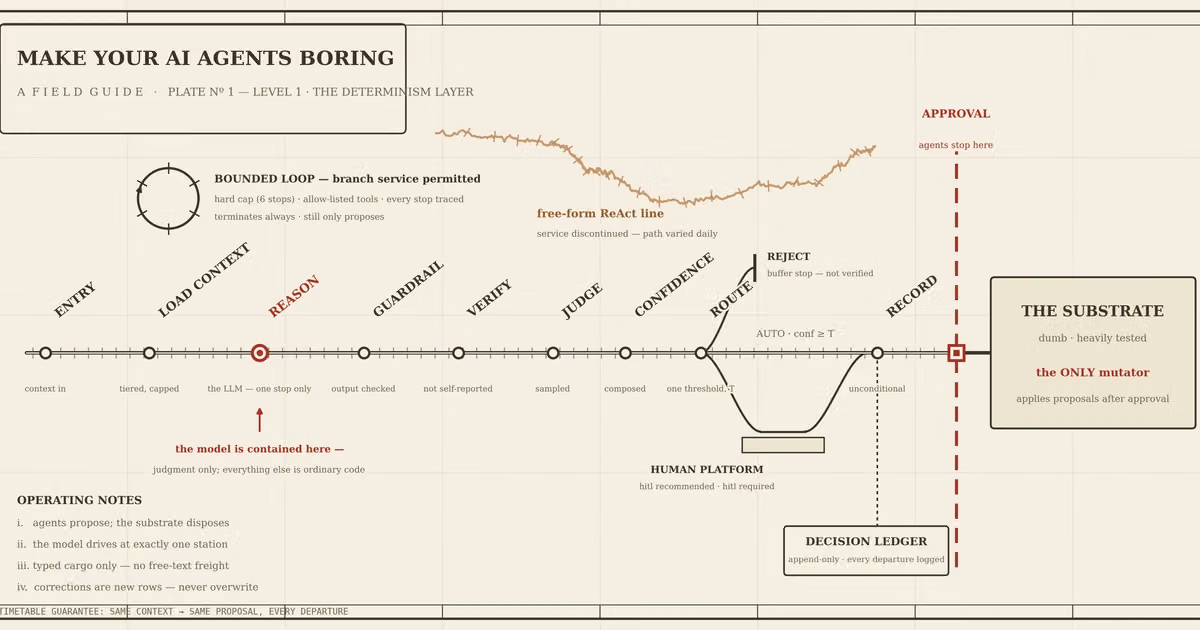
The most important rule: an agent is a pure function from context to a proposed decision — pure with respect to business state, and deterministic given its gateway (the one nondeterministic call, the model, is injected so tests can fake it). It has no authority to change the world. A separate, dumb, heavily-tested component — the substrate — applies proposals, and only after the required approval.
from typing import Protocol, Literal from dataclasses import dataclass
@dataclass(frozen=True) class Proposal: decision_id: str capability: str action: dict # the structured, proposed change — NOT yet applied confidence: float routing: Literal["auto", "hitl_recommended", "hitl_required", "reject"] reasoning: list[str] evidence: list[dict]
class Agent(Protocol): def propose(self, ctx: "Context") -> Proposal: ... # pure: no side effects on business state
class Substrate(Protocol): def apply(self, proposal: Proposal, approval: "Approval") -> "Effect": ... # the ONLY mutator
Because propose() is pure, its headline property is one assertion:
def test_propose_is_pure(): agent = ClassifyAgent(gateway=FakeGateway(scripted)) assert agent.propose(ctx) == agent.propose(ctx) # same context → same proposal; no world touched
The boundary buys you three properties:
This single constraint turns “an AI did something we can’t explain” into “an AI suggested something, and here’s exactly what approved it.”
Free-form ReAct loops are great for exploration and terrible for guarantees. Model each capability as a fixed sequence of nodes where the model is used only where judgment is needed and everything else is ordinary code. The arrow sketch below is abridged for readability; the full node list (with pre_check and memory_write`) is in the next section.
entry → load context → reason (LLM) → output guardrail → verify → judge (sampled) → compose confidence → route → prepare proposal → record → exit
Free-form ReAct loop Fixed-graph (this)
Control flow model decides next step known in advance Testable hard (path varies) each node in isolation Latency / cost unbounded bounded, predictable Audit reconstruct from trace uniform row every time Right for open-ended exploration decisions that must be guaranteed
You give up some cleverness; you get back the ability to reason about what the system will do. The clever part — judgment on messy inputs — stays exactly where the model is good at it, in one node, surrounded by code you can read.
“Make agents deterministic” is hard to act on until you’ve seen the shape of one. So let’s walk a single request through the graph, node by node — the implementation behind the diagram above.
The state object. Every node reads and writes one typed state value threaded through the graph. Making this explicit is half the battle — it’s what lets you test a node in isolation by constructing a state and asserting on the result.
from typing import TypedDict, Literal, Optional
class GraphState(TypedDict): decision_id: str tenant_id: str identity: dict # who/what authority (set at entry) inputs: dict # validated request context: dict # loaded memory/reference slices model_output: Optional[dict] # raw structured output from the LLM node guardrail: dict # blocks/redactions applied verification: dict # deterministic check results judge: Optional[dict] # second-opinion result (if sampled) confidence: Optional[float] # composed score routing: Optional[Literal["auto", "hitl_recommended", "hitl_required", "reject"]] proposal: Optional[dict] # final shaped proposal ledger_entry_id: Optional[str]
The node contract. Every node is the same shape: state -> state. Deterministic except the one model node. This uniformity is why you can unit-test each node and reason about the whole.
from typing import Protocol
class Node(Protocol): name: str def run(self, state: GraphState, deps: "Deps") -> GraphState: ...
The graph. Eight nodes are shared across every capability; only a few are capability-specific. New capability = implement ~4 nodes, inherit the other 8.
1 entry mint decision_id, bind tenant + identity [shared] 2 pre_check validate inputs, resolve refs, cheap early-outs [capability] 3 context_load fetch only the context this decision needs [shared] 4 llm_decision the reasoning step — structured in, structured out [capability] 5 output_guardrail PII / policy scrub on the model output [shared] 6 verification deterministic, capability-specific correctness checks [capability] 7 judge sampled second-model review (high-stakes) [shared] 8 confidence_compose composed score from the signals [shared] 9 routing auto vs hitl vs reject [shared] 10 prepare_proposal shape the final proposal [capability] 11 memory_write write the agent's own audit memory (not business state)[shared] 12 exit append the immutable ledger entry [shared]
The two load-bearing nodes are llm_decision and verification`. The first is the only nondeterministic node — structured input, schema-constrained output, retry-on-mismatch — and everything around it treats its output as untrusted until checked (more on that next section). The second is deterministic, capability-specific code that the whole “contain the model” thesis rests on:
def run(self, state, deps): out = state["model_output"] checks = { "in_enum": out["decision"] in ALLOWED_DECISIONS, # can't return an off-list action "schema_ok": matches_schema(out, DECISION_SCHEMA), "rules_ok": deps.rules.check(out, state["inputs"]), # business invariants } state["verification"] = {"checks": checks, "score": sum(checks.values()) / len(checks)} return state
The point of the fixed shape: you can read the control flow (the path is the graph), the model stays contained to one node, and every decision is uniform — same shape every time means the same audit row every time, and the same place to add a check, a metric, or a guardrail.
Node 4 deserves its own treatment, because a surprising amount of LLM fragility comes from one choice: letting the model return free text and then parsing it. Prose is ambiguous, the format drifts between calls, and your downstream code is one unexpected phrasing away from breaking. “Sure! It’s probably Approve, though it could be Escalate” — now you own an NLU problem to extract Approve, and tomorrow's rephrase breaks your regex. You've coupled your system to the model's prose style, the least stable thing about it.
The fix is boring and powerful: constrain the model to emit a validated structure, and treat anything else as a failed call to retry. There are three ways to constrain, picked by how hard the guarantee must be:
method how guarantee use when
Schema-guided (JSON Schema / response_format) ask for JSON matching a schema strong, provider-enforced most cases Tool / function call model emits a typed tool call strong; natural for "do X with args" the decision maps to an action Grammar-constrained decoding constrain tokens to a grammar hard guarantee (can't emit invalid) strict/regulated formats, local models
the contract as types — downstream consumes a typed object, never prose
from pydantic import BaseModel from typing import Literal
class Decision(BaseModel): decision: Literal["approve", "escalate", "reject"] # an enum is itself a guardrail confidence: float reasons: list[str]
Constrained generation reduces malformed output; it doesn’t eliminate it. So close the loop: validate every response, and on a mismatch retry — feeding the validation error back. Bound the retries and fail closed.
from pydantic import ValidationError class NonConformingOutput(Exception): ...
def decide(base_prompt, model, max_retries=2) -> Decision: prompt = base_prompt for _ in range(max_retries + 1): raw = model.generate(prompt, schema=Decision.model_json_schema()) try: return Decision.model_validate_json(raw) # success: typed object except ValidationError as e:
rebuild from base_prompt — don't append onto the already-appended prompt (it compounds)
prompt = f"{base_prompt}\n\nYour previous output was invalid: {e}. Return JSON only." raise NonConformingOutput() # fail closed — never hand downstream a guess
Validation at the boundary means the rest of the system only ever sees well-formed decisions; the messy “did the model behave” question is contained to this one function. You trade a vague NLU problem for a crisp validation problem — no parsing layer, stability across model/prompt swaps, a built-in guardrail (a fixed enum cannot return something off-list), and a typed contract golden tests can assert against.
One caveat worth stating loudly: structure constrains form, not correctness. A perfectly valid {"decision":"approve","confidence":0.99} can be completely wrong. Structured output removes the parsing failure mode, not the judgment failure mode — which is why it's the floor of a production system, under evals, verification, and confidence, not a substitute for them.
Confidence (model signal + verification + sampled judge) is composed at the confidence node; the routing node turns it into one of four paths with a single threshold, and prepare_proposal later stamps that result onto the proposal:
def route(confidence: float, verified: bool, T: float = 0.85) -> str: # T is per-capability config, not a constant if not verified: return "reject" if confidence >= T: return "auto" if confidence >= T - 0.2: return "hitl_recommended" # close: pre-fill the proposal for a human return "hitl_required" # low: a human decides from scratch
verified is derived from the verification node (verified = all(checks.values())), not a field the agent sets on itself, and the router emits all four routing states. Note the order: routing runs before the proposal is shaped (node 9 → node 10), so it takes a plain confidence and a verified flag — not a Proposal. Start T conservative — everything to a human — and lower it per slice only as data proves it safe. Human attention, the expensive resource, gets spent exactly where the system is unsure.
Every proposed decision becomes one immutable row — written as the last node of every decision, unconditionally. Not a log line; the canonical record of what happened and why.
CREATE TABLE decision_ledger ( decision_id TEXT PRIMARY KEY, ts TIMESTAMPTZ NOT NULL, tenant_id TEXT NOT NULL, capability TEXT NOT NULL, inputs_hash TEXT NOT NULL, -- hash, not the raw sensitive payload model_version TEXT NOT NULL, prompt_version TEXT NOT NULL, decision JSONB NOT NULL, confidence REAL NOT NULL, routing TEXT NOT NULL, -- auto |
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。