Show HN: A Lego-like composable Framework for RSI
* Equal contribution · † Corresponding author
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
- Equal contribution · † Corresponding author
Star on GitHub🤗PaperarXiv Coming soon
GPT 5.6 Luna · performance & evolutionExpand figure ↗
01 / The frameworkWithin tasks · Across tasks
Learn from experience. Improve across tasks.
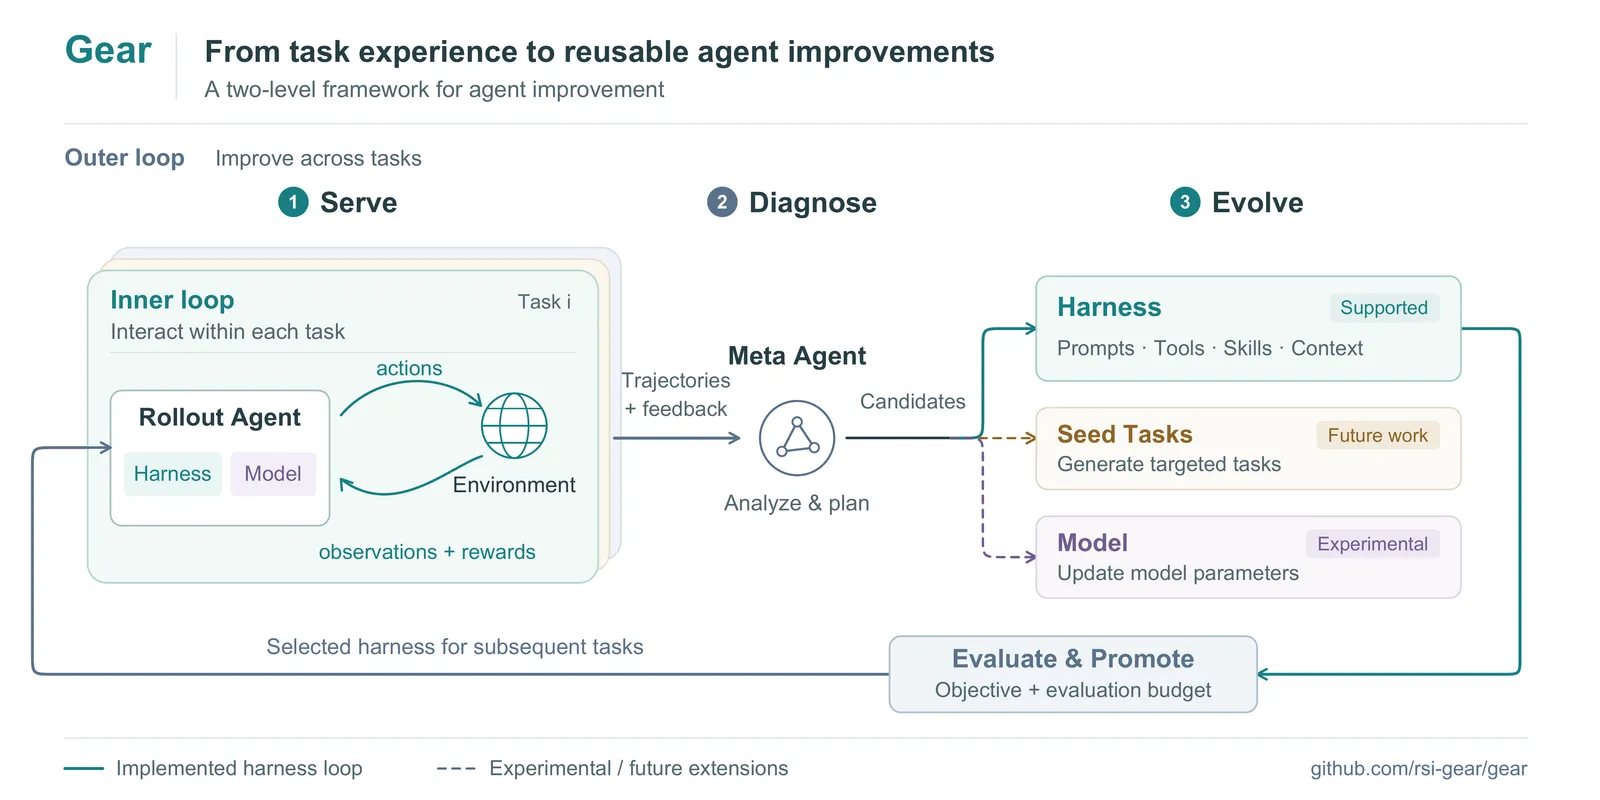
GEAR organizes recursive self-improvement as a two-level meta-learning process. In the inner loop, a rollout agent uses task feedback to refine its reasoning, planning, and actions within a task.
In the outer loop, a Meta Agent identifies common patterns across task experiences, including recurring failures and effective strategies, and proposes reusable improvements to enhance cross-task performance. GEAR evaluates and promotes these changes for subsequent tasks. The two loops can be optimized independently and are connected by experience.
Animation could not load. Use the video or GIF link above.
GEAR organizes evolutionary search into replaceable algorithm components, providing a common framework for studying different search strategies. Staged GEPA is one concrete instantiation, illustrated below.
Animation could not load. Use the video or GIF link above.
Choose which archived harness to improve next. Staged GEPA uses task-level fronts to retain useful specialists and sample parents from the frozen archive.
Policy modules express the framework’s design boundaries. The current staged implementation exposes parent selection as a public policy hook; evidence validation, evaluation stages, and final promotion remain controlled by the runtime.
Improvements across coding, marketing, and support. Same-model comparisons, with reasoning effort made explicit.
Δ is the absolute improvement in percentage points.
AutomationBench reports task pass rate and objective completion; Terminal-Bench 2.1 reports task pass rate. Luna max is a separate evaluation at a higher reasoning effort. Result data ↗
Separate responsibilities, connected by versioned evidence.
Code, experiment records, and the tools to start your own research.
Explore the framework, search components, and examples.
Set up a task benchmark and connect the Refine Skill.
Inspect the staged Marketing experiment and its evaluation evidence.
Preprint · October 2026. arXiv link will be added when available.
@unpublished{tang2026gear, title = {{GEAR}: An Open General Evolutionary Architecture for Recursive Self-Improvement of {LLM} Agent Harness}, author = {Tang, Yehui and Zhu, Guanqi and Xia, Shao-Jun and Chen, Xin and Geng, Mengzhe and Du, Hongyang and Tang, Yuhao}, year = {2026}, note = {Preprint}, url = {https://github.com/rsi-gear/gear} }
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。