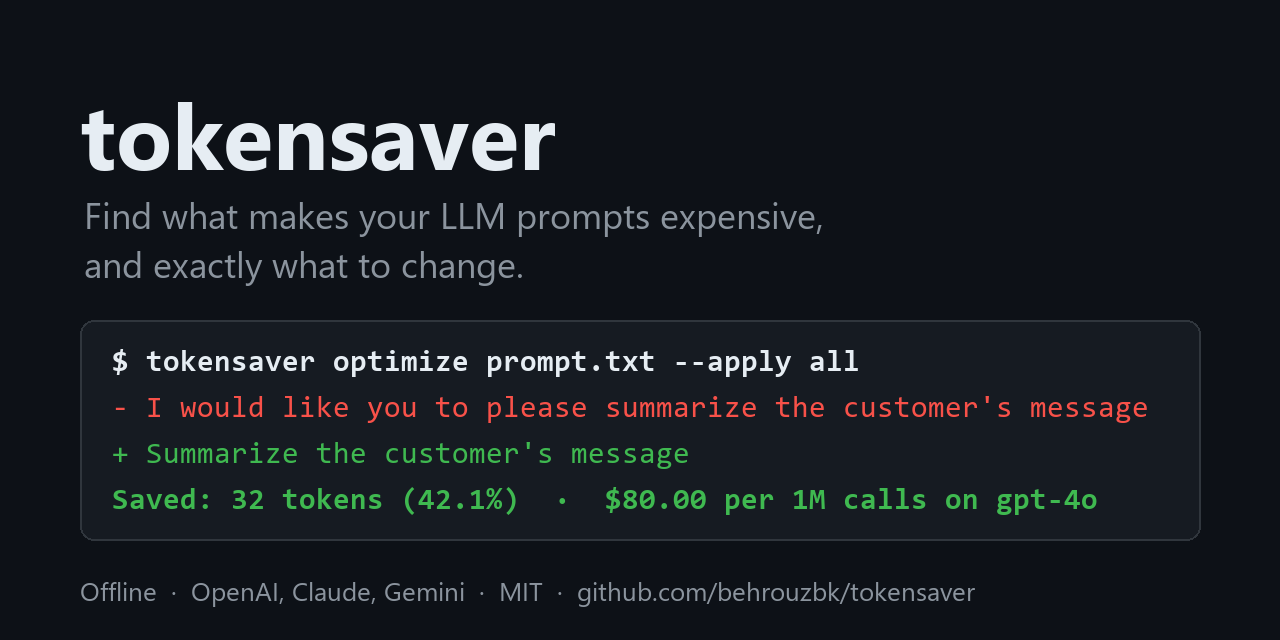
Tokensaver, see which parts of your LLM prompt cost money
Find out what your prompt costs on every major AI model, and exactly which changes make it cheaper.
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
Find out what your prompt costs on every major AI model, and exactly which changes make it cheaper.
Most token counters stop at a number. tokensaver tells you what to change: every suggestion comes with a reason, the tokens it saves, and what that is worth in dollars. It runs 100% offline. Your prompt never leaves your machine.
tokensaver works with prompts in any language and any script. Token counting, cost comparison, JSON minification, whitespace cleanup and duplicate detection are tested in CI on 55 languages on every commit (see the test):
Arabic · Bengali · Bulgarian · Burmese (Myanmar) · Chinese (Simplified) · Chinese (Traditional, Hong Kong) · Chinese (Traditional, Macau) · Chinese (Traditional, Taiwan) · Croatian · Czech · Danish · Dutch · English · Estonian · Finnish · French · German · Greek · Hebrew · Hindi · Hungarian · Indonesian · Italian · Japanese · Kannada · Khmer · Korean · Lithuanian · Malay · Malayalam · Marathi · Nepali · Nigerian Pidgin · Norwegian · Persian (Farsi) · Polish · Portuguese (Brazil) · Portuguese (Portugal) · Punjabi (Gurmukhi) · Romanian · Russian · Serbian (Cyrillic) · Slovak · Slovenian · Spanish · Swahili · Swedish · Tagalog (Filipino) · Tamil · Telugu · Thai · Turkish · Ukrainian · Urdu · Vietnamese
Right-to-left scripts (Arabic, Hebrew, Persian, Urdu) and languages without spaces between words (Chinese, Japanese, Thai, Khmer, Burmese) included. The filler rule still speaks only English. Native speakers: add your language's filler phrases in #5.
examples/messy_prompt.txt is a typical customer-support system prompt: polite filler, a rule written twice, a paragraph pasted twice, and pretty-printed JSON.
$ tokensaver optimize examples/messy_prompt.txt --apply all
Suggestion Tokens $/1k calls Status
1 Minify JSON block (140 chars, was 185) line 13 -18 $0.0450 applied 2 Minify JSON block (200 chars, was 392) line 39 -43 $0.1075 applied 3 Duplicate line: “- Never share internal information…” line 30 -12 $0.0300 applied 4 Duplicate paragraph: “Please note that you must only…” line 34 -41 $0.1025 applied 5 Repeated instruction: “Make sure you keep the answer…” line 32 -12 $0.0300 applied 7 Filler: “I would like you to…” (×1) line 4 -6 $0.0150 applied ... 15 Long example (~198 tokens) line 60 ≤198 $0.4950 flag
╭──────────────────────── Total savings on gpt-4o ─────────────────────────╮ │ Before: 834 tokens │ │ After: 665 tokens │ │ Saved: 169 tokens (20.3%) = $0.000423 per call, $0.4225 per 1,000 calls, │ │ $422.50 per 1M calls │ ╰──────────────────────────────────────────────────────────────────────────╯
What changed in the prompt:
-I would like you to please read the customer's message carefully and answer their question. -As an AI language model, you should always be polite, friendly and professional. +Read the customer's message carefully and answer their question. +You should always be polite, friendly and professional. ... -{
- "answer": "string",
- "category": "billing | technical | account | other",
- ... -} +{"answer":"string","category":"billing | technical | account | other","confidence":0.0,...} ... -- Never share internal information, discount codes or employee names. -- Make sure you keep the answer under 120 words.
With only the default safe rules (no wording changes at all), the same prompt drops from 834 to 772 tokens. tokensaver then tells you that the review suggestions would save 107 more, so you decide.
pip install prompt-tokensaver
The command is tokensaver. Requires Python 3.10 or newer. Works on Windows, macOS and Linux.
1. How many tokens, and what does one call cost?
tokensaver count prompt.txt --model gpt-4o tokensaver count "Summarize this article in three bullet points."
2. Which model is cheapest for this prompt?
tokensaver compare prompt.txt tokensaver compare prompt.txt --models gpt-4o,claude-sonnet-5-5,gemini-2.5-flash
3. What should I change? (safe changes are applied, others are suggested)
tokensaver optimize prompt.txt
4. Apply everything you agree with and save a copy (the original is never overwritten)
tokensaver optimize prompt.txt --apply all --output prompt.optimized.txt tokensaver optimize prompt.txt --apply json,whitespace,filler -o prompt.optimized.txt
Pipe text in with "-", list models and prices
cat prompt.txt | tokensaver count - # PowerShell: Get-Content prompt.txt | tokensaver count - tokensaver models
Windows paths work as usual: tokensaver optimize examples\messy_prompt.txt.
Run tokensaver <command> --help for the same information in your terminal.
A mistyped file name like promt.txt is an error, not silently counted as text.
Tokens and input cost on many models, cheapest first.
Suggestions with the tokens and dollars each one saves, a before/after diff and the total.
tokensaver optimize prompt.txt # look first: safe fixes only, nothing saved tokensaver optimize prompt.txt --apply all -o prompt.min.txt # apply everything, save a copy tokensaver optimize prompt.txt --apply json,whitespace,duplicates -o prompt.min.txt tokensaver optimize prompt.txt -m claude-sonnet-5-5 --no-diff # savings on Claude, short output tokensaver optimize prompt.txt --apply all -o prompt.min.txt --force # re-run and replace the copy
tokensaver models and tokensaver version
models lists every supported model with its prices and whether counts are exact. version prints the installed version.
Each rule is a small module in src/tokensaver/optimizer/. Safe rules cannot change meaning and are applied by default. Review rules are shown with their savings and applied only when you ask (--apply all or --apply <rule,...>). Code blocks are never changed. Few-shot examples are never reworded.
Every saving is measured: tokensaver counts the prompt before and after each change on the model you chose. Changes that save nothing on that model are not listed. (Safe whitespace fixes that save 0 tokens are still applied for a tidy file, and reported in one line.)
Prices are USD per 1M tokens, standard tier, as of 2026-10-26. They live in src/tokensaver/data/prices.json with a source URL for each model. Edit that file, or pass your own with --prices my_prices.json.
Run tokensaver models to see the list for your installed version.
Please read this before relying on the numbers.
Calibrate the Claude and Gemini estimate factors against official token counters
--json output for CI pipelines and scripts
Output-token and prompt-caching cost estimates
Directory mode: scan all prompts in a project
More rules: verbose markdown, long URLs, unused template variables
GitHub Action that comments token savings on pull requests
Ideas and votes are welcome in the issues.
⭐ If tokensaver saved you tokens, a star helps other developers find it.
Contributions are very welcome: new rules, better heuristics, price updates and bug reports. Read CONTRIBUTING.md for the 5-minute setup. Each rule is one small file with its own tests, so it is a good first contribution.
tokensaver catches the easy wins. If your AI bill is growing and you want a deeper review of prompts, model choice, caching and architecture, I can help.
☕ tokensaver is free and MIT licensed. If it saves you money, you can buy me a coffee.
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。