Ellf: The missing piece for building NLP with coding assistants
Introducing Ellf: The missing piece for building NLP with coding assistants
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
Introducing Ellf: The missing piece for building NLP with coding assistants
Oct 14, 2026
11 minute read
Blog
Ellf, Prodigy, spaCy
Code Generation
Distillation
Evaluation
NLP Strategy, LLMs, Annotation
Ines Montani
Matthew Honnibal
Magdalena Anioł
Ellf is our new tool that plugs into the coding assistant you already use, like Claude Code, Codex or GitHub Copilot, and gives it the missing pieces to develop custom AI and NLP systems end to end: from planning and annotation to training and evaluation.
For a quick walkthrough of the platform, check out the video series, or browse the documentation.
Coding assistants have made things that previously weren’t worth building doable and maintainable. And we believe the same can be true for AI models. If we can make coding assistants good at NLP development, it becomes much easier to build custom components that are more accurate, faster, cheaper and fully private. But out of the box, they’re missing a few things.
Building software is mostly a code problem. But building an NLP system is a code plus data problem. You need examples of what you want the output to be, both to train on and to know whether your system works at all. You also need to run lots of things, often iteratively and in parallel: preprocessing scripts, annotation, training experiments and evaluations. And you need to know which approach to choose in the first place, which is where most of the hard decisions are.
Coding assistants are now very good at writing code and guiding you through a process. But when it comes to data-centric projects, they tend to fall short in three ways:
The annotation component is key, because it lets the agent schedule a little bit of computation on the human. You typically don’t need to create a massive dataset – with transfer learning, annotating just a few hundred examples here and there helps massively to evaluate, fine-tune and plan. The problem most teams face is that they don’t have a low-friction way to get this work done, so it ends up getting skipped.
We’ve always believed in annotation tooling that scales down to low-volume use cases, which is why we emphasized flexibility and programmability in our annotation tool Prodigy. Annotation doesn’t have to be boring click work: there’s almost always a way to break down or reframe the task into simple, often even binary decisions that are quick to make. You just need a bit of creativity and the right interface.
Coding assistants really unlock this flexibility, because the agent is able to assemble an annotation experience that’s as efficient as possible for your exact use case. Ellf ships with Prodigy and built-in workflows for common tasks, and when those aren’t enough, your coding assistant can write a custom recipe with a tailored workflow and interface for you.
Ellf also lets you assign auto-annotation agents to tasks alongside human annotators. Agents are powered by LLMs, either via an API or running locally, and create data in their own datasets in the background. This means that if your task is well-defined, you can let agents do the first pass and focus your own time on the parts where human feedback matters most: reviewing, correcting and creating a reliable evaluation set. You can invite subject matter experts on your team to annotate or review directly in the app, see the annotations come in in real time and compare the results.
The next thing we wanted to solve with Ellf is execution. Doing NLP and machine learning projects means developing code and data together. This is something we think many MLOps tools get wrong, because they’re very focused on hyperparameter search, which is often only a small part of what you’re doing. Most of the time, you need to run a lot of once-off scripts to manipulate data. And even when you’re running experiments, you’re usually trying to answer a specific question, which takes a lot of legwork to set up a direct comparison.
Ellf gives your coding assistant a seamless and flexible way to perform that computation. Obviously, Claude Code can build you pretty much anything by itself – Bash is fully general. But if you make it solve “run this in the cloud” as a subtask in your session, it’s going to do worse at the actual problem you’re trying to work on.
The main concepts in Ellf are tasks, actions, agents and services:
Under the hood, all of these are created from Python functions, called recipes. Their arguments are automatically converted to a web form in the app and a matching command-line interface, which is also what your coding assistant uses to operate Ellf for you. This means you get the advantages of software as a service, like a central app, user accounts and collaboration, while still being able to fully script it in Python. If you or your coding assistant can do something in Python, you’ll be able to do it with Ellf.
Importantly, the computation runs under your control. It’s a bit like plugging in self-hosted runners in a CI system like GitHub Actions. You run a Kubernetes cluster in your own cloud account or even a local machine, and this is where all data processing and computation happens. Your data is never sent to us.
Whenever you see data from your cluster in the app or CLI, Ellf makes two separate requests: one to our server for the records, and one to your cluster for the actual data. Our servers never make requests to your cluster. This also means that you can use Ellf for privacy-sensitive and highly regulated use cases.
Even if you don’t have any DevOps experience, coding assistants now make it much easier to set up and configure your own infrastructure, and once it’s connected to Ellf, your coding assistant will be able to take over the setup for you.
The final piece is knowledge. Out of the box, coding assistants don’t suggest doing annotation, and they don’t really know how to structure an NLP project. A little bit of correction can go a long way here. For Ellf, we’ve built a knowledge base with all our advice and best practices from over 10 years of solving real-world NLP problems in industry.
Alongside the knowledge base, Ellf comes with a set of carefully designed skills and modules for each step of the development lifecycle: project planning, data annotation, custom Prodigy recipes, pattern generation for rule-based logic, model training, monitoring and question answering. They encode the strategies we’ve written about in posts like Applied NLP Thinking, human-in-the-loop distillation and Atomic NLP: breaking business problems down into small components, factoring out business logic and always measuring against real-world data.
As you work, Ellf keeps a project plan that logs the strategy, decisions and results, and links to the relevant resources in the platform and on your cluster. And if you ever get stuck or need a second opinion, the support module lets you send your session to us and have it reviewed by us for feedback.
For a simple use case example, let’s say you want to create insights from incoming, human-written support tickets: extract structured fields like product, feature, error code, version and integration, and route each ticket to the right queue. You can probably build a prototype with an LLM API relatively quickly, but to go into production, you want the system to be faster and cheaper, and keep your data private. Doing this from scratch would typically involve many steps and require time, experience and of course data.
With Ellf, you can start by describing your problem to your coding assistant:
Your coding assistant (e.g. Claude Code)
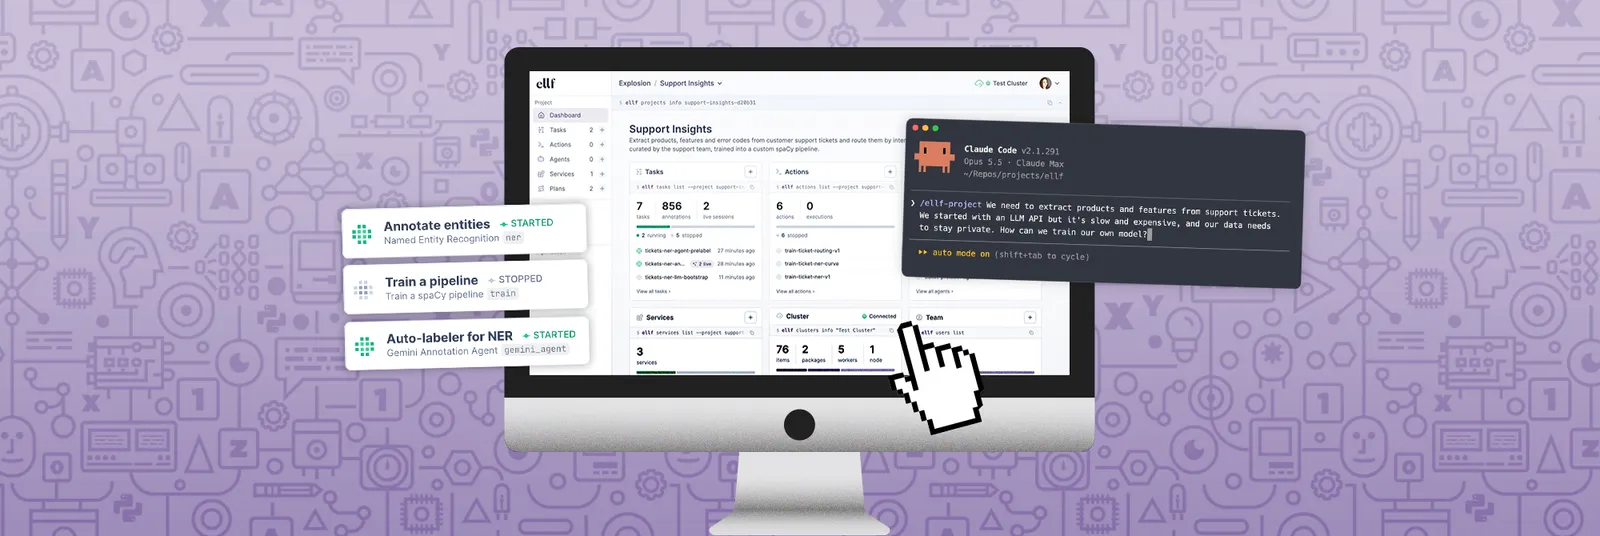
/ellf-project We need to extract products and features from support tickets. We started with an LLM API but it's slow and expensive, and our data needs to stay private. How can we train our own model?
Based on the data, Ellf suggests breaking the problem down into two components: a named entity recognizer for the structured fields and a text classifier for routing, since the category depends on the intent of the whole ticket, not just on which entities appear in it. It then develops a label scheme and annotation guidelines, following our best practices, and writes up the plan. From there, the workflow looks something like this:
You can also invite the support engineers to review examples, measure how well the agent performed and decide what to improve. And at the end, the data and the model are yours: a small, fast and private component you can run in production instead of calling the larger LLM on every ticket.
Ellf has been a lot of fun to build, and it finally lets us bring together ideas we’ve been working towards since we started Explosion 10 years ago: making it easier for everyone to build custom NLP systems in house, with tools that are programmable, private and under your control.
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。