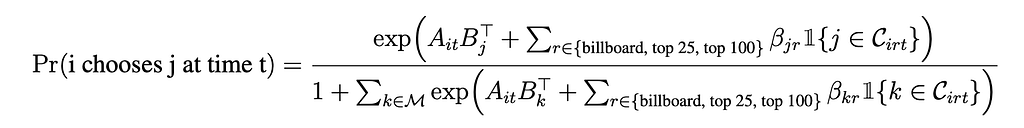
Measuring the Impact of Personalized Recommendations
By Kevin Zielnicki, Guy Aridor, Aurélien Bibaut, Allen Tran, Winston Chou, and Nathan Kallus ### Introduction Personalization is everywhere on the internet. It shapes the products we discover, the stories we read, the m…
以下正文同步自 Netflix TechBlog,版权归原站所有,已转换为易读排版。
By Kevin Zielnicki, Guy Aridor, Aurélien Bibaut, Allen Tran, Winston Chou, and Nathan Kallus Introduction Personalization is everywhere on the internet. It shapes the products we discover, the stories we read, the music we hear, and the movies and TV shows we watch. At Netflix, personalization has been central to the member experience for decades — from the Netflix Prize to our modern recommender system that helps members navigate a large and constantly changing catalog. But personalization is not only an algorithmic problem, it is also a measurement problem. How do we know how much value personalization creates? More precisely, how do we separate the appeal of a title from the value created by recommending that title to the right member at the right time? In a new article in the International Journal of Industrial Organization — which we are also presenting at this year’s ACM Conference on Economics & Computation (EC ‘26) — we develop a model of member behavior, title choice, and personalized recommendations. The model lets us estimate how recommendations affect both whether members choose to watch and, if so, which titles they choose. In this post, we summarize our approach and main findings. The Measurement Challenge A natural first attempt at valuing recommendations is to ask: what share of viewing comes from titles that were recommended? This is an intuitive metric, but it fails to answer the causal question at hand. The problem is that recommendations are not randomly assigned. A title appears on a member’s homepage precisely because the recommender system predicts that the member might want to watch it. If a member watches that title, was it because the recommendation caused the member to watch it? Or would she have watched it anyway because of her underlying preference for that kind of title? This is the core measurement challenge: recommendations are targeted to demand, so viewing a recommended title combines the effect of personalization with the member’s underlying preferences. One way to solve this would be to run a large experiment that replaces Netflix’s personalized experience with an unpersonalized one. That would create clean variation — but it would also be a poor member experience. Personalization is a central part of how members locate valuable titles in a large catalog, so turning it off broadly is not an acceptable measurement strategy. Instead, we take a hybrid approach. We build a behavioral model that separates members’ underlying preferences from the incremental effect of recommendations. The model uses the natural variation in the recommendation system, for example due to algorithmic exploration, to estimate how recommendations affect choice. Then, to validate the model predictions about title substitutability, we use small-scale A/B tests that “nudge” the salience of a handful of titles exogenously, generating ground-truth substitution patterns for a subset of titles. This lets us combine the scale and richness of modeling with the credibility of experimental evidence. A Model of Member Choice To measure the value of personalization, we need a model of what members would watch under different recommendation systems. Our model treats Netflix viewing as a day-by-day choice process. On each day, a member chooses among the titles available in the catalog, or she chooses not to watch anything. This gives us a concrete target to estimate: the probability that a member watches each title on a given day, as a function of their preferences, their viewing history, and the recommendations they see. A simple version of this model would be too restrictive. It might assume, for example, that removing one title from the catalog shifts viewing toward all other titles in roughly proportional ways. But that isn’t how member choice works. If a member is considering a romantic comedy, the closest substitutes are likely other romantic comedies, not every title on Netflix equally. For similar reasons, two members may react very differently to the same recommendation. To capture this complexity, we use a low-rank choice model. The model learns a representation of each title and a corresponding representation of each member’s current preferences. These representations are not limited to manually specified features like genre, cast, or language. Instead, they are learned from viewing behavior itself, allowing the model to capture nuanced similarities between titles that may be difficult to describe with coarse features, such as genre or release date, alone. Our Model Attributes Choices to Dynamic Member-Title Affinity and the Effect of Recommendations Member preferences are dynamic. What someone wants to watch today depends on what they have watched recently. A member who just finished a crime thriller may be in a different preference state than the same member after watching a stand-up special or a kids’ movie. Rather than estimate a fixed preference vector for each member, the model summarizes each member’s past viewing history into a current preference state. This lets us capture heterogeneous and time-varying tastes while also scaling to millions of members. Our Model Architecture Allows Us to Scale to Millions of Members Efficiently The key component for our purposes is that the model explicitly parameterizes the effect of recommendations. When a title is recommended, the model gives it an additional recommendation effect, or “bonus,” that increases its probability of being chosen. This bonus is a reduced-form way to capture two related mechanisms. First, recommendations can create awareness by helping members discover titles they may not have known about. Second, recommendations can provide information by signaling that a title is likely to be a good match. Once estimated, the model becomes an engine for predicting counterfactuals. We can ask what would happen if a title were not recommended, if a different set of titles were recommended, or if the current recommender system were replaced with simpler alternatives. Because the model separately represents member preferences, title appeal, and recommendation effects, it lets us estimate not only how recommendations affect total viewing, but also how they change which titles are watched. The model is only useful, however, if it captures real substitution patterns. The next step is therefore validation: comparing the model’s predictions to randomized experiments that directly perturb, on a small scale, the visibility that each title receives. Validating the Model with Randomized Experiments The model relies on an important assumption. After conditioning on the member, title, and state information available to the recommender system, we treat the remaining variation in whether a title is recommended as if it were randomly assigned. In our setting, this assumption is reasonable: we observe all of the information available to the recommender system, so we should be able to model its behavior accurately. But it is still an assumption. A useful model should not only fit historical viewing patterns; it should also predict what happens when recommendations change for external reasons. Thus, to validate the model, we used randomized experiments that introduce variation in title visibility exogenously. These experiments mirror the kinds of variation that occur routinely when recommendation algorithms are updated: some titles receive more impressions, while others receive fewer. The key difference is that, in the validation experiment, this variation was prespecified so that we could estimate clean experimental benchmarks. Specifically, we randomly assigned members to treatment arms that slightly nudged recommendations towards and away from different categories of titles. This let us measure diversion ratios: when a set of titles becomes less visible, how much viewing shifts to other titles, and how much shifts out of Netflix viewing altogether? We then asked whether the model could reproduce those experimentally measured substitution patterns. We estimated the model on the control group, simulated the same recommendation changes, and compared the model-implied diversion ratios to the experimental ones. The agreement was strong: the model’s predicted diversion ratios had a correlation of 0.86 with the experimental estimates and an R-squared of 0.73. Our Model Predicts Out-of-Sample Experimental Diversion Ratios Well This validation gives us confidence that the model captures counterfactual substitution patterns accurately. Subsequently, we ask what would happen under more dramatic changes, such as different recommender systems. Counterfactuals: Aggregate Consumption and Diversity With a validated model in hand, we can move from measurement to counterfactuals. Instead of asking only what happened under the current Netflix experience, we can ask what would have happened if members had seen recommendations generated by a different system. We compare the current recommender system to three baselines:
- The first is random recommendations: every member receives titles selected uniformly at random from the catalog. This is not intended as a realistic product experience, but it helps isolate the value of having recommendations that are relevant.
- The second is popularity-based recommendations: every member receives broadly popular titles. This is a natural non-personalized benchmark.
- The third is a basic matrix factorization model, a classic personalized recommendation approach and a useful baseline for older generations of recommender systems. In each counterfactual, we replace the recommended titles while keeping the rest of the choice environment fixed. This lets us estimate how much viewing would change if the recommendation policy changed, holding constant the catalog, members, and model of member choice. The results show that the current recommender system generates substantially more engagement than each benchmark. Relative to the current system, random recommendations reduce engagement by 16%, popularity-based recommendations reduce engagement by 12%, and matrix factorization reduces engagement by 4%. These are large differences at Netflix scale. Even the comparison to matrix factorization — a personalized baseline — suggests that continued improvements in personalization translate into meaningful gains in how effectively members find titles they want to watch. Personalized Recommendations Increase Engagement and its Diversity Engagement is only part of the story. A recommender system could increase viewing while concentrating attention on a narrow set of already-popular titles. That would be a worse experience for members whose tastes are not well represented by those titles, and it would make poorer use of a broad catalog. We therefore also examine consumption diversity: how broadly viewing is distributed across titles. The current system performs well on this dimension too. Popularity-based and matrix-factorization recommendations both substantially increase concentration, meaning that fewer titles receive meaningful viewership. Random recommendations produce slightly more diversity, as expected, but at a large cost to engagement. Taken together, these counterfactuals show that the value of personalization is not just that members watch more. It is also that members are matched to a broader set of titles. The current recommender system increases engagement while preserving a wide distribution of viewing, reflecting the diversity of member tastes across the Netflix catalog. Decomposing the Impact on Titles The aggregate counterfactuals show that personalization increases engagement while maintaining broad consumption across the catalog. We can also use the model to ask a more granular question: why does a recommended title get watched? There are three conceptually distinct channels:
- The first is exposure: simply showing a title to a member can increase the probability that the member watches it. This captures the bas
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。