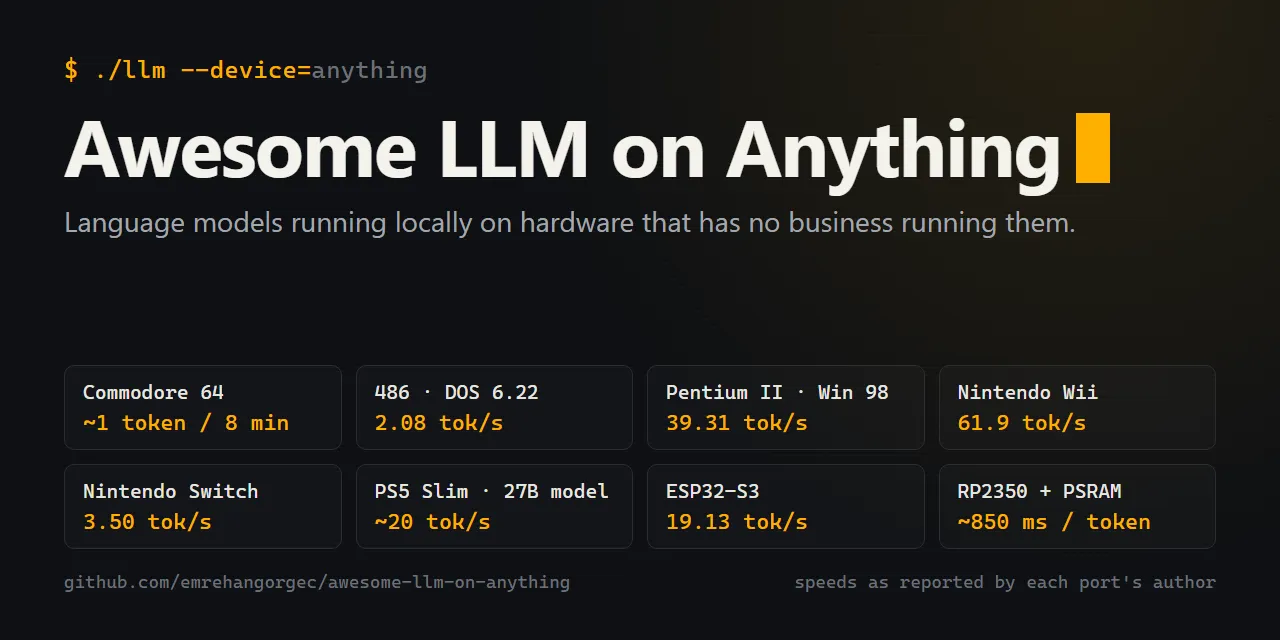
Language models running locally on hardware that has no business running them
Language models running locally on hardware that has no business running them.
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
Language models running locally on hardware that has no business running them.
Retro PCs, game consoles, handhelds, microcontrollers. If it has a CPU and someone got tokens out of it, it belongs here.
The one rule: inference must run on the device itself, on real hardware. Devices that only talk to a model elsewhere go in Thin clients. Ports shown only in an emulator go in Emulator only.
Seen one we're missing? Paste a link, we fill in the rest.
About the speeds: every number is what the port's author reported, linked to its source. Nobody here re-benchmarked them. Models, quantization and tokenizers differ between rows, so treat speeds as flavor, not a ranking. ? means no speed is recorded in this list yet.
Retro computers
Consoles and handhelds
Microcontrollers
Wearables
Emulator only
Thin clients
Extremes
Wanted
Foundations
Related
Retro computers
Device Model Reported speed Project
Commodore 64 with 2MB REU stories260K ~1 token per 8 min (author estimate) llama2.c64
486 DX2 66 MHz, 32MB RAM, DOS 6.22 stories260K 2.08 tok/s dosllam2 · write-up
Pentium II, 128MB RAM, Windows 98 stories260K / stories15M 39.31 / 1.03 tok/s llama98.c · write-up
Consoles and handhelds
Device Model Reported speed Project
Nintendo 64, VR4300 93.75 MHz, 4 to 8MB RAM, EverDrive 64 Legend of Elya, 819K, quantized (precision not reported) ? write-up
PlayStation 2, Emotion Engine 294 MHz, 32MB RAM, weights streamed from CD brandon-tiny-10m-instruct, Q8 ? ps2-llm
PlayStation Portable stories260K ? llama2-psp
Nintendo Wii, 88MB RAM, 729 MHz PowerPC stories15M, int8 61.9 tok/s (GPU engine), 12.7 tok/s (CPU) iiama2.c
PS Vita PCH-1000, ARM Cortex-A9 overclocked to 555 MHz stories260K / stories15M ~120 / ~1.8 tok/s psvita-llm
New Nintendo 3DS, ARM11 804 MHz with L2, Homebrew Launcher stories15M, Q8_0 / Q4 18.46 / 23.28 tok/s generation 3DS port
Nintendo Switch, Tegra X1, Switchroot Linux Llama 3.2 3B Instruct, Q4_K_M 3.50 tok/s generation write-up
PowKiddy V90, MiyooCFW (CPU and RAM not specified in write-up) stories260K, precision not reported ? Tiny LLM
Xbox Series S, Developer Mode, 6 CPU threads, 311MB peak model RAM LFM2.5-350M, Q4_0 QAD 101.6 tok/s CPU generation (median of 3) xllama · measurements
Nintendo 64: the author reports running on real hardware, but the linked source repository is currently unavailable. The author withdrew earlier speed claims, so no speed is listed. The V90 write-up is credited to Ordinary_Tension5730. New 3DS inference runs on the handheld; WiFi only carries the generated output to a laptop. Xbox measurements are for Series S only; Series X is untested.
Device Model Reported speed Project
ESP32-S3 with 2MB PSRAM stories260K 19.13 tok/s esp32-llm
Four ESP32 boards, with and without PSRAM 260K, FP32 2.32 to 22.00 tok/s ESP32-Tiny-LLM
Raspberry Pi Pico (RP2040) stories260K ? picollama260k
RP2350 board with 16MB flash and 8MB PSRAM (standard Pico 2 boards won't work) bundled 14MB model ~850 ms per token PicoLlama
Wearables
Device Model Reported speed Project
Google Pixel Watch 3, Wear OS 5, 32 bit ARM, ~0.5GB free RAM SmolLM2-360M-Instruct, Q4_K_M ~1 to 4 tok/s wear-llm
Emulator only
Real ports, but so far only shown running in an emulator. Moves to the tables above once someone runs it on real hardware.
The model runs elsewhere, but the device is still delightfully wrong.
Not a benchmark, just an extreme example from the list.
We haven't found a documented on-device port for these yet. If one exists, or you build one, tell us (see Contributing below).
llama2.c - Karpathy's single file C inference. Almost every tiny port above starts here.
llama.cpp - The engine behind most ports to bigger hardware.
Related
Can It Run AI? - A museum style catalog of AI and local compute on vintage hardware, with evidence links.
Contributing
Got a model running on a toaster? Two ways in.
No Git needed: share a port by pasting one link. We fill in the details, add the row and credit you.
Open a PR: read CONTRIBUTING.md and add one row.
Missing a speed or spotted a wrong number? Fix an entry. Only have a rumor? Drop it in the tips thread.
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。