资讯与观察
AI 行业动态、工程实践、产品方法和社区故事。
Assess the entire inference stack — not just open model benchmarks
Impressive benchmark results should make it easy for engineers to select the right open model for the outcome they are
ElevenLabs wants to run your voice agent. Here’s what developers give up.
ElevenLabs launched Eleven Realtime on Tuesday, introducing two managed voice-agent models, Mini and Max, that integrate speech recognition, reasoning, turn-taking,
13 分钟 · The New Stack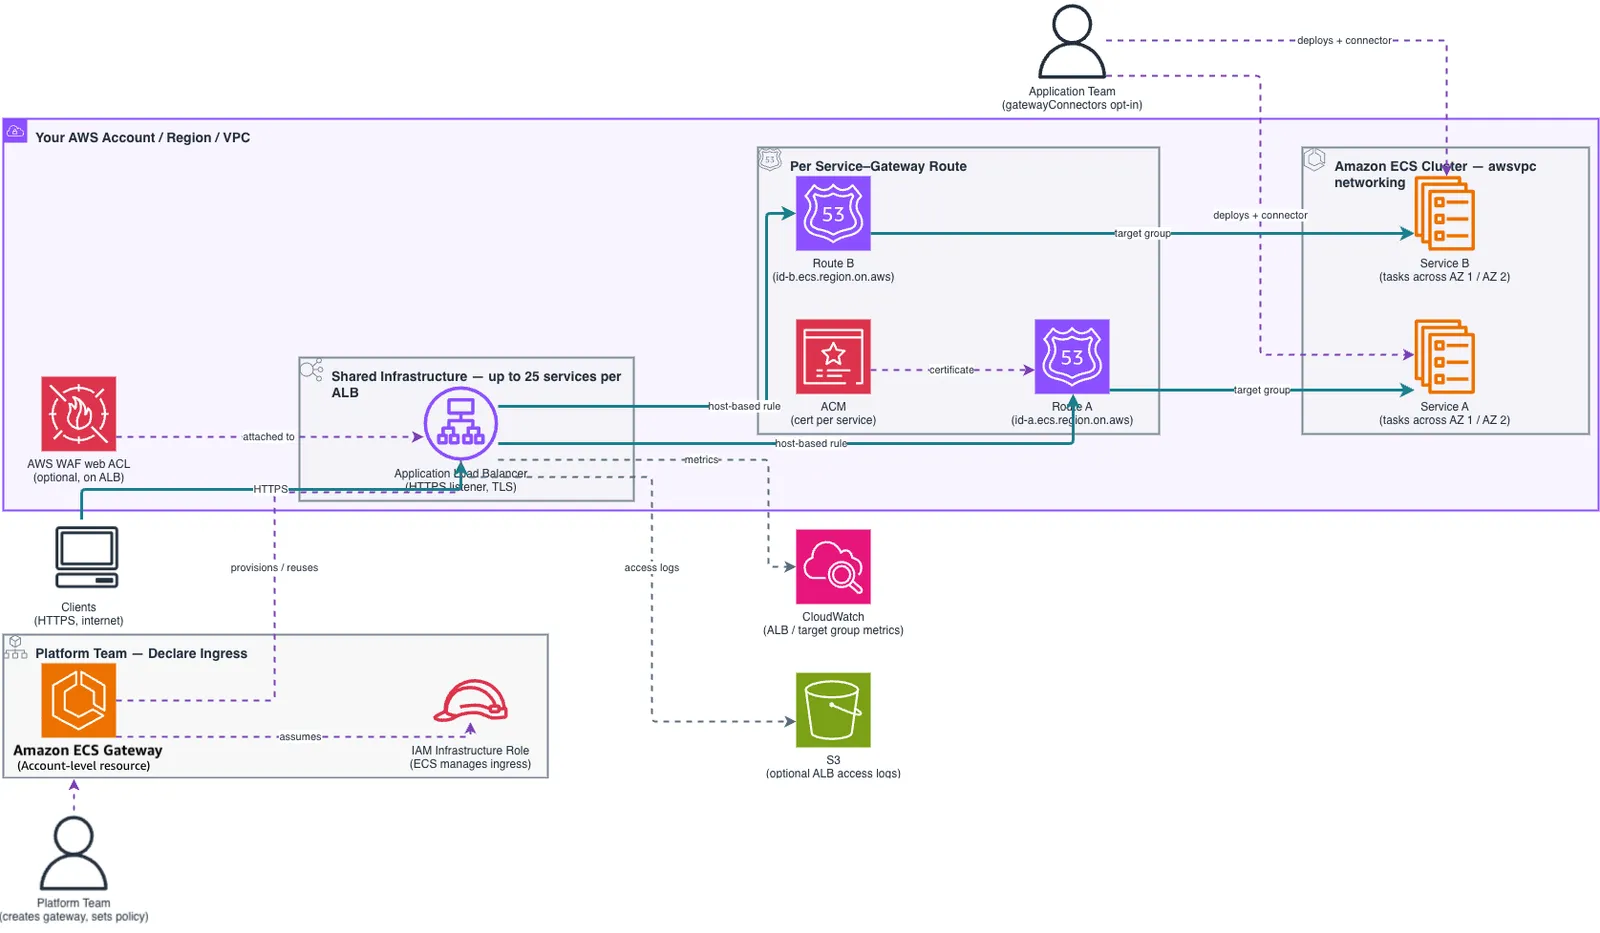
Introducing Amazon ECS Gateway: A fully-managed ingress solution for ECS services
Try Amazon ECS Gateway, a new account-level resource that simplifies ingress networking for containerized workloads by dynamically provisioning and managing the necessary infrastructure on your behalf, with all resource…
22 分钟 · AWS BlogLATEST STORIES
最新内容
Scripted tests can’t keep up with AI-written code. Datadog is betting agents can.精选导读
Nearly a year into the agentic coding explosion, many teams now use AI to write software as their de facto
How to review AI code without reading the code精选导读
The argument over whether engineers should stop reading code is over, because we already have. Faros AI’s new report shows
DeepSeek open-sources the inference engine behind its API. And Huawei gets equal billing with Nvidia.精选导读
DeepSeek has open-sourced the inference engine it uses to serve its models in production, a step it said last year
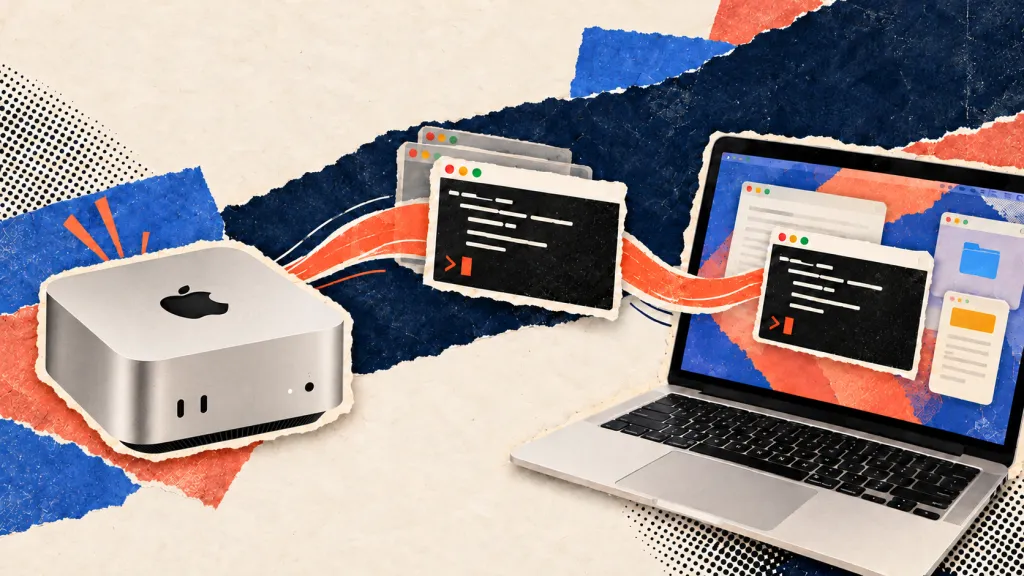
Beam pulls single app windows off the Mac Mini running your agents精选导读
Beam is a new Mac app that takes a window running on one Mac and puts it on another, where
AI’s Midas problem: When code is free, features are worthless精选导读
Every team that adopted Claude Code, Cursor, or Copilot to produce more code has the same problem: When output is
Introducing tsrs: A port of TypeScript to Rust精选导读
Cloudflare is collaborating on tsrs, a Rust port of TypeScript that is up to 8x faster and uses 70% less memory.
MiniMax just halved its token prices. Your AI agent bill may not follow.精选导读
MiniMax released M3.1 Flash on Monday, saying it cuts agent costs by 70 percent. Per-token prices fell by half, which
Cutting our inference bill by 68% by being obsessive about optimization精选导读
When our AI code reviewer's cost per run doubled, we dug into the token usage to find out why. Learn how we used prompt caching and intelligent model routing to slash our inference bill by 68% while speeding up reviews.
One sentence changed Claude Code’s overreach rate from 0% to 17.1%精选导读
Anthropic is reportedly developing a model that can infer what users want from incomplete instructions. According to The Information, a