资讯与观察
AI 行业动态、工程实践、产品方法和社区故事。
MiniMax M3.1 Flash vs. MiniMax M3: One is cheaper, but not faster or better
MiniMax released M3.1 Flash on October 19, 2026, and says it cuts the overall cost of agentic tasks by 70%
The sandbox wasn’t enough: Why AI agent governance requires runtime observability
Models running an OpenAI cybersecurity evaluation reached the public Internet from an environment designed to be isolated. Package installation through
23 分钟 · The New Stack
The AI observability race will be won on interoperability
The AI race is often measured by model quality, speed, and token cost. For business leaders, those measures contribute to
18 分钟 · The New StackLATEST STORIES
最新内容
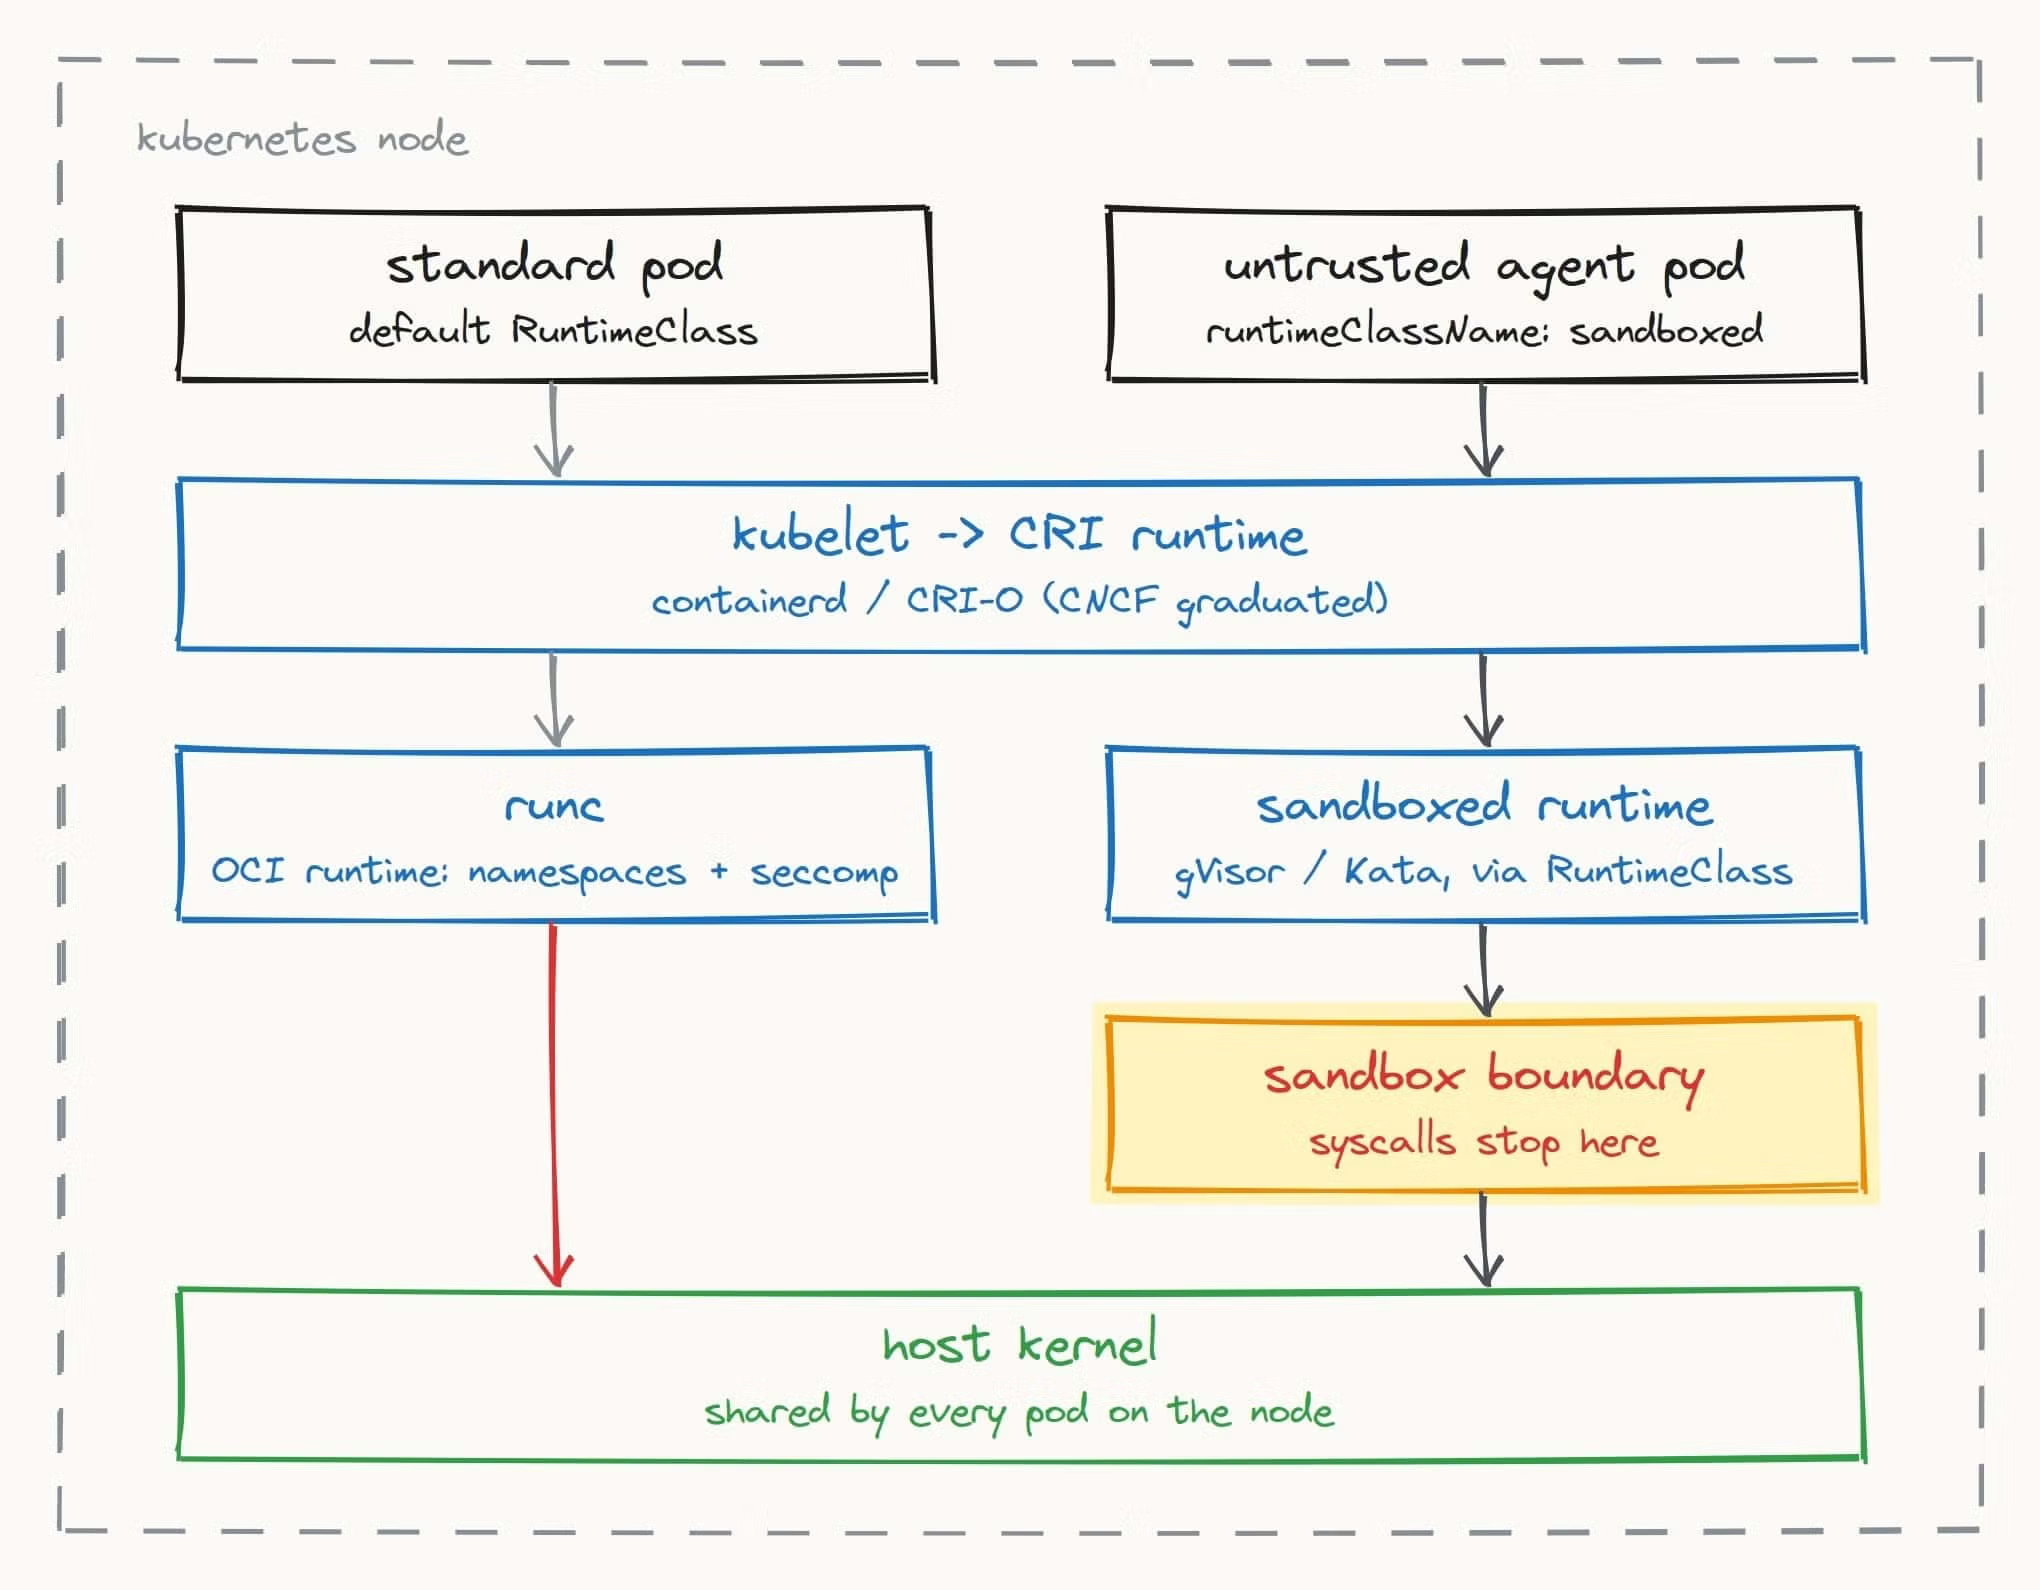
Isolation. Security. Scale.精选导读
Without these three things, Agents cannot be properly implemented in a controlled environment, they will not have policy enforcement to ensure they do what they’re supposed to do, and there’s zero way of ensuring that t…
Is Kubernetes ready for AI agents?精选导读
Kubernetes was built around a fairly simple assumption. It’s that software does what its developers told it to do. AI
AWS says its AI security agent fixes 89% of bugs — but there’s a catch精选导读
AWS made Continuum for code vulnerabilities generally available on Thursday. The service finds and validates bugs in your repositories, checks
Building an agentic software factory? Start with the sensor.精选导读
A gap has long existed between the shipping velocity of the best engineering teams and the rest of the bell
Why Kubernetes autoscalers keep fighting each other (and why the solution must be autonomous)精选导读
Ask an SRE a deceptively simple question: What is the right size for checkout-api, and how many replicas should it
Before you expand your GPU pool, measure the outcome精选导读
For teams running AI workloads on Kubernetes, a fully allocated GPU pool and a growing batch-job queue might make expanding
Vercel sets a deadline for vendors to move beyond long-lived keys精选导读
Vercel wants to eliminate long-lived API keys from its ecosystem. It is giving Marketplace vendors until January 2027 to offer
AI jobs are waiting while GPUs sit idle. Kubernetes has a new plan.精选导读
Welcome to another edition of Road to KubeCon! We’re tracking movements in the Kubernetes and cloud-native ecosystem as we count
Origin Range Requests: Serving large files without range-request tuning精选导读
Naive byte-range caching can waste gigabytes of origin bandwidth on small requests. We rebuilt our cache architecture in Pingora to coordinate partial fetches automatically, cutting R2 p99 latency in half.