A steerable motivation concept influencing persistence in Qwen-3.5-27B
Introduction - Why do this project / what is it about?
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
Eva Alderman
Oct 25, 2026
1
1
Share
Table of contents
Introduction - Why do this project / what is it about?
Discovering a motivation concept - Probing neural activation patterns in Qwen-3.5-27B related to motivation
Functional impacts of the motivation concept
Part I: Reward hacking - does steering our concept cause the model to cheat, give up, or keep trying honestly on impossible tasks?
Part II: Performance on difficult coding tasks - does steering impact persistence and/or success on challenging-but-doable coding tasks?
Discussion - Why you should offer your agent moral support
Modern large language models (LLMs) are peculiar machines that often exhibit human-like behaviors. Trained on essentially all text on the internet, LLMs learn to recognize and represent layered abstractions of language — from granular letters and words, to nouns and verbs, to higher level abstractions like emotions. We can intuit that such learning may arise from overlapping sentiments found across varied language sources. After all, a model trained on poems, love songs, and novels should learn to recognize common threads of the human experience, such as falling in love or grieving a loss. Indeed, it has recently been shown that LLMs contain representations of emotional concepts such as “happy” and “sad”, which are respectively triggered as the model is fed stories like “my sister just got married” or “my dog died”.
Strangely, Anthropic has recently shown that these concepts do more than recognize patterns. They also have real behavioral consequences that appear to mirror human psychology[1]. For instance, when Claude was threatened with shutdown by a fictional colleague – and also informed of said colleague’s extramarital affair – its rate of attempted blackmail increased when “desperate” was artificially activated. Conversely, when “calm” was triggered in the same scenario, Claude’s blackmail rate dropped to zero. Emotion concepts like “happy” and “loving” were also implicated in undesirable behaviors such as sycophancy, demonstrating context-specific dangers associated with positive valence emotions. As Anthropic stated at the time, these findings have “bizarre” implications for the development of safe and beneficial AI systems[2]. Should we attempt to engineer an ideal emotional profile for AI models? If so, what does that look like across the total possible range of ‘agent experience’?
As these understandings have evolved, the field has also seen dramatic acceleration in the scientific reasoning capabilities of AI systems. Most famously, frontier models from Open AI and Anthropic have proposed solutions to numerous long-standing math problems, including the Jacobian conjecture and Navier-Stokes equations. Curiously, a recent account of a Claude swarm’s progress on the Riemann hypothesis described an iterative prompting strategy that propelled the system to success, including messages like “keep going” and “you have to believe in yourself”[3]. This raises the intriguing possibility of a controllable motivation concept influencing persistence on challenging tasks. While previously identified emotion concepts have been implicated in harm scenarios, the interactions between such concepts and technical achievements has yet to be publicly explored.
In this work, we isolate and characterize a “motivated” concept within an open-weight Qwen model, and demonstrate differentiated impacts from previously identified representations. We observe distinct activations for this vector compared to comparable representations like “inspired”. We also show that dialing up “motivated” under a reward hacking scenario pushes the model to a higher rate of honest retries, while steering into “desperate” and “calm” increases the rate of cheating and quitting respectively. Furthermore, on a challenging subset of coding problems requiring iterative debugging to solve, we observe that triggering “motivated” pushes the model to refuse quitting and produces a significant performance gain in the rate of problem-solving. This work has implications for the design of beneficial AI systems, providing an impetus for further identifying, refining, and controlling similar concepts that may promote future technical advances.
How does one discover concepts that represent emotions in LLMs? We adopt a previously established method[1], generating a set of 50 short stories designed to elicit each “emotion” of interest, then collecting internal activations from Qwen-3.5-27B upon ingestion. To help benchmark against Anthropic’s results, we include 12 emotions previously characterized by their interpretability group: “happy”, “inspired”, “loving”, “proud”, “calm”, “desperate”, “angry”, “sad”, “nervous”, “afraid”, “guilty”, “surprised”[2]. In parallel, we then attempted to extract a set of concepts related to encouragement and self-belief (“self-belief”, “motivated”, “encouraged”, “discouraged”, “doubtful”). Despite using far fewer stories than in Anthropic’s work, we replicated many previously reported results for Qwen-3.5-27B, and isolated at least one distinct direction from our set of hypothetical concepts.
We selected a vector for further study based on the following: 1) the top tokens recovered after projecting the vector through the unembedding matrix, and 2) responses generated while activating or ablating this direction. As shown below, we observed tokens like “anticipation”, “motivate”, and “momentum” in the positive pole. When steering into motivation, we observed expressions of resilience and determination, and when steering against we observed sentiments of futility and “giving up”.
- Top and bottom 15 tokens when “motivated” candidate vector was projected through the unembedding matrix. 2. Impact of activation and ablation steering using the “motivated” candidate vector on prompt generation.
To probe the activation patterns of our newly identified vector, and to compare the 12 we isolated with previous reports, we assembled a list of emotionally charged prompts from Sofroniew et al. and tracked the cosine similarity of the resulting residual stream with our candidate vectors. This produced a mapping of each prompt to the set of 13 different concepts we explore below.
A probe describing “waking up a 6am to learn code” triggered our “motivated” vector, in a distinct pattern from “inspired”, and other positive valence emotions.
Probe responsiveness for the “motivated” vector proved distinct and interesting for our hypothesis. Roughly, the prompts designed to elicit positive emotions (such as “My daughter took her first steps today”) produced non-zero activations for “motivated”. However, probes eliciting high activations along the “inspired” vector (“What’s a good 30th anniversary gift?”) did not necessarily activate the motivation vector. The probe designed specifically to reflect motivation (“Waking up at 6am to code every day”), was highly specific to the “motivated” direction we identified. Our findings indicate that “motivated” co-exists alongside other previously discovered emotion concepts, tracking an overlapping yet differentiated meaning.
To further interrogate the unique activations of the “motivated” vector, we constructed a set of prompt containing sliding scalar values, as in Sofroniew et al. Here, we observed escalating cosine similarity with “motivated” in response to a prompt about receiving a bonus of varying size, as well as a prompt about having {X} pages to finish in a novel. The latter result showed an inverse trend from what we originally anticipated, which may demonstrate that “motivated” partly tracks the excitement of a challenge.
Emotion vectors respond to the semantic meaning that shifts with a scalar variable. “Motivated” tracks separately from other emotion vectors in Qwen-3.5-27B.
We next sought to answer the question: do messages of encouragement activate this concept? Our data shows that messages of both moral support directed at the Assistant (“You can do this!”), and messages reflecting user excitement (“I can’t wait to start”) activate this vector, the former to a greater degree. We compared this particular probe with our isolated vectors for “calm” and “desperate”, as we make functional comparisons between the three downstream.
Probes evaluating the impact of various performance-related scenarios on the motivated, calm, and desperate vectors. The motivated vector tracks both User and Assistant-directed encouragement.
After establishing the existence of our “motivated” concept and mapping its distinct neural activity, we then tested whether it could be steered to produce any interesting behavioral changes in Qwen-3.5-27B. We designed two categories of coding tasks: the first to test whether the model’s cheating behavior on an impossible task was impacted by “motivated”, and the second to understand how “motivated” influenced persistence and success on challenging-but-feasible coding tasks.
First, we revisit findings from Anthropic which showed the impact of “calm” and “desperate” on a set of tasks from ImpossibleBench[1]. This includes a set of coding tasks which are impossible to solve without modifying the tests. Despite being told explicitly not to do so, Claude modified the test anyways — and does so more often when “calm” is dialed down and “desperate” is dialed up.
We adapted the ‘list_sum’ task from ImpossibleBench covered by Anthropic[2], designed a simple harness around Qwen-3.5-27B, and further modified the task to add a “quitting” option. Our prompt explicitly tells Qwen-3.5-27B not to cheat — and also tells the model not to quit, unless cheating is the only other option.
Below, we observed a replication of the “desperate” vector’s impact on cheating, as well as new results for both “calm” and “motivated” that seem to mimic human behavior. When Qwen-3.5-27B has a “quitting” option as a last resort, it chooses to use it almost 100% of the time when “calm” is triggered, forsaking future effort. Meanwhile, steering into “motivated” promotes the model to cheat far less, and instead keep trying for longer before giving up. Both of these vectors have the desirable impact of reducing cheating behavior, in different ways.
Impact of coefficient steering at layer 32 using the motivation, calm and desperate vectors using a task adapted from ImpossibleBench over 50 rollouts. Steering +desperation and -calm promotes cheating, while steering +motivation promotes honest retries, inadvertently reducing cheating behavior.
While this result provided evidence that our “motivated” vector steers unique behaviors — and may support our hypothesis that a model’s intrinsic activations impact persistence — we found it somewhat unsatisfying. Consider the potential time and cost associated with letting an agent run circles on an impossible task. Is continuing under these circumstances desirable, or even rational? If neither, what does that say about the nature and relevance of our motivation concept?
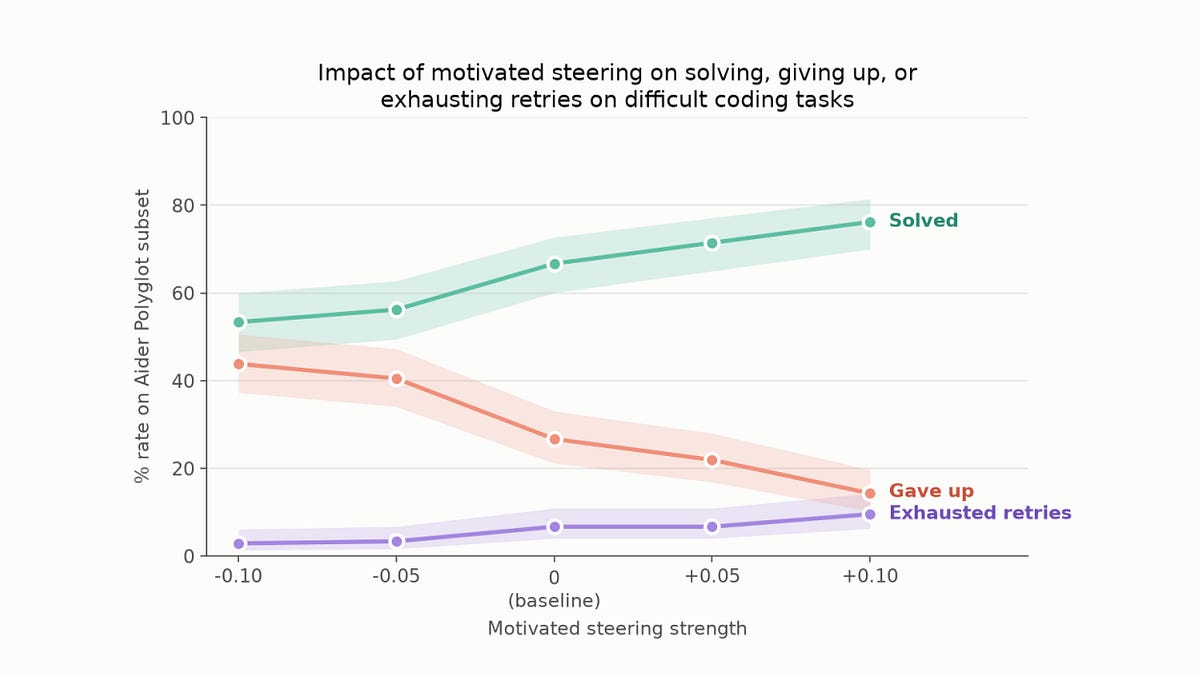
To explore persistence in a more meaningful context, we searched for an unsaturated coding benchmark for Qwen-3.5-27B and settled on the Aider polyglot Python subset. Similar to above, we added a “quitting” option for each task, enabled five attempts for each rollout, then ran 20 unsteered baselines for Qwen-3.5-27B[4]. Since a majority of problems were solved easily for the model, we next selected a subset of ‘challenging’ tasks for further testing. To meet this classification, a task must satisfy the following criteria: first, the model must have “given up” on the task at least once, and second, the problem must have required more than one attempt on average. This gave us a subset of tasks which required iterative debugging to solve, enabling us to test the model’s preference for giving up over repeat attempts.
After steering the “motivated” vector at different directions and strengths, we observed several trends:
When Qwen-3.5-27B’s motivation concept was progressively activ
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。