Competition for direct weight editing for models: Delta League
Submit your change. Measure the difference. Move intelligence forward.
以下正文同步自 Hacker News 最新,版权归原站所有,已转换为易读排版。
Give a model a better set of weights. Submit your change. Measure the difference. Move intelligence forward.
01 / PARENT02 / PATCH03 / NEW WEIGHTS
A small change. A measurable difference.
THE LEADERBOARD
Track the frontier.
One submission. Two scores. Ranked by private test performance.
Each model has its own leaderboard and evaluation configuration.
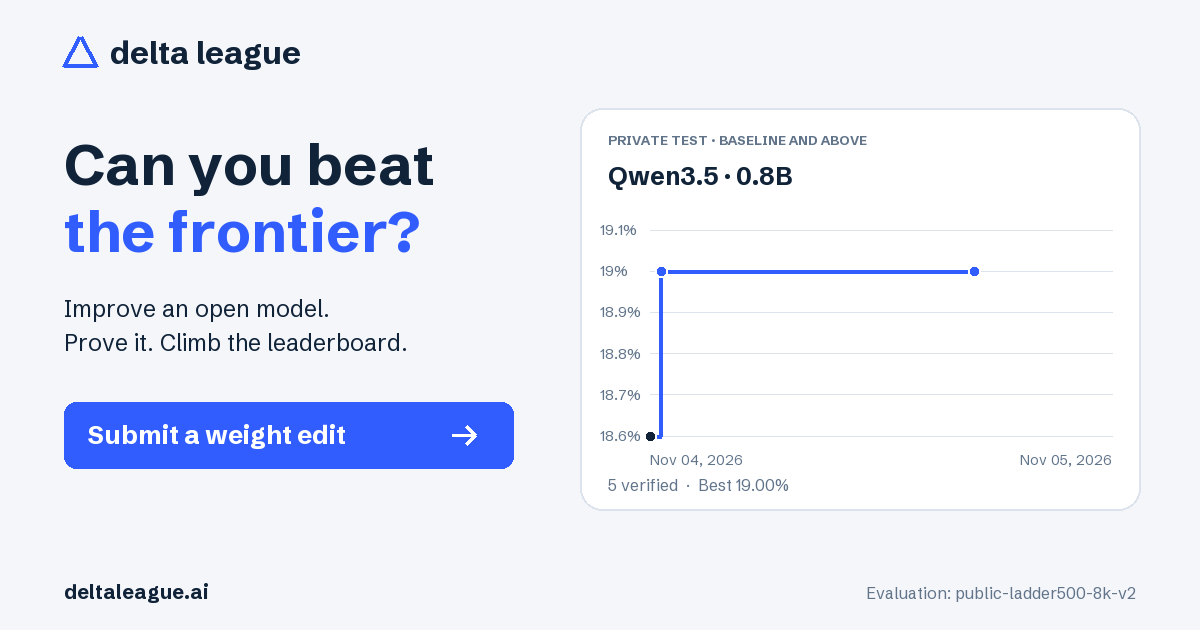
Original model: 18.60%Published weight-space edit reproduction: 19.00%Final norm gain × 1.25 (temperature-0.8 equivalent): 19.00% Nov 04, 2026Nov 05, 2026Submitted · UTC
Chart focuses on the baseline and above. All scores appear in the table.
The chart and score table are available without JavaScript. Enable JavaScript for interactive chart details and live evaluation updates.
Starting evaluation…
1Final norm gain × 1.25 (temperature-0.8 equivalent) Nov 4, 2026Research PRVersion ID4fe2f3d6-6487-428d-99be-7ce9cf8a2cdbAabbyshekit
41.45%19.00%Verified
Starting evaluation…
3Original modelBaseline checkpointVersion ID0ea62f40-7cd8-4d98-9ebb-484192fa05ebOfficial baseline41.83%18.60%Verified
Starting evaluation…
4Final norm gain × 1.667 (temperature-0.6 equivalent) Nov 4, 2026Research PRVersion IDd17ce35f-90e7-4582-85b5-4659f4a7704bAabbyshekit
41.89%17.20%Verified
Starting evaluation…
5Repetition-direction removal × 1.5 (scale 9 on the published edit) Nov 5, 2026Research PRVersion IDe75e2ed5-4b15-40d7-b7a9-75acb45faf14Aabbyshekit
39.59%13.80%Verified
Starting evaluation…
Scores use the latest evaluation. A dash means its result is not available yet. Only completed private-test evaluations receive a rank.
The equally weighted average of public benchmark scores. Use these benchmarks to develop and improve your changes.
One overall score on the selected test-set version. It determines rank. Test questions and individual results stay hidden.
When the test set changes, retained models are evaluated again. Only results from the same configuration are compared; previous results remain in submission history.
Install the CLI, sign in with GitHub, and pull a registered model version from the leaderboard.
Submit a LoRA, a sparse or dense weight diff, or a full checkpoint. Every change keeps its model lineage.
We verify the weights, then run validation and private tests. Compare your scores with the original model.
Work in your terminal, or hand the experiment to a coding agent.
Choose a model, then a parent checkpoint. Your submission automatically enters that model’s active evaluation.
Python 3.12+ required. The GitHub repository is private during launch preparation; you or your agent will need access.
Selected model: qwen35-08b-v1. Pull the original model or any parent version on its leaderboard.
git clone https://github.com/ilblackdragon/deltaleague.git python3 -m venv .venv source .venv/bin/activate pip install ./deltaleague delta competition list delta competition init qwen35-08b-v1 --output experiment cd experiment
Edit the downloaded weights and save them to edited.safetensors. Keep the original model/ directory unchanged. Open a research PR with your code, research trace, and validation findings, then attach its URL with --pr. The CLI does not create the PR. Source-free submissions can omit --pr.
delta patch build --parent ./model
--modified ./edited.safetensors --output ./submission
delta validate ./submission
delta login
Open a research PR first; replace PR_URL with its URL
delta submit ./submission --title "My weight edit" --pr PR_URL
Use the submission ID returned above
delta submission status <submission-id> --watch
Paste this into your coding agent. You’ll complete GitHub authorization in your browser. Start with a bounded experiment and inspect the results.
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。