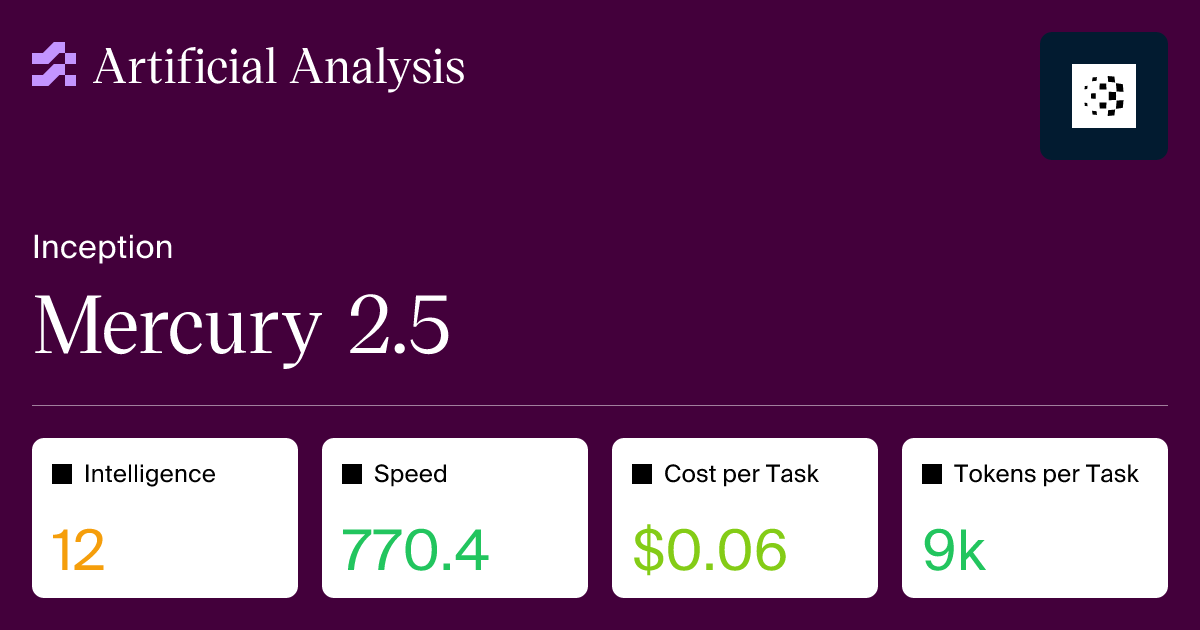
Mercury 2.5 LLM hits 770 tokens per second
CompareTry it out API Provider Benchmarks
以下正文同步自 Hacker News,版权归原站所有,已转换为易读排版。
Artificial AnalysisK
Artificial AnalysisModels
Coding Agents
Image, Speech, Video
Inference
Leaderboards
About
AI Trends
K
Inception
•Proprietary model
CompareTry it out API Provider Benchmarks
Model summary
IntelligenceUpdated
#91 / 175
12
Artificial Analysis Intelligence Index
2 out of 4 units for Intelligence.
Speed
#2 / 175
770.4
Output tokens per second
4 out of 4 units for Speed.
Cost
#21 / 175
In $0.25Out $0.75Cache Discount 90%
$0.06
Cost per Intelligence Index task
2 out of 4 units for Cost.
Verbosity
#14 / 175
35M
Output tokens from Intelligence Index
2 out of 4 units for Verbosity.
Comparison Summary
Mercury 2.5 is below average in intelligence, but well priced when comparing to other models of similar price. It's also notably fast and fairly concise. The model supports text input, outputs text, and has a 260k tokens context window.
Mercury 2.5 scores 12 on the Artificial Analysis Intelligence Index, placing it below average among comparable models (median: 13). When evaluating the Intelligence Index, it generated 35M tokens, which is fairly concise in comparison to the median of 85M.
Pricing for Mercury 2.5 is $0.25 per 1M input tokens (moderately priced, median: $0.25) and $0.75 per 1M output tokens (moderately priced, median: $0.90). On average, it costs $0.06 per task to evaluate Mercury 2.5 on the Intelligence Index.
At 770 tokens per second, Mercury 2.5 is notably fast (109).
ReasoningYesThis page shows the reasoning version of this model.
Context window260k~390 A4 pages of size 12 Arial font
175 models in this class
Metrics are compared against models of the same class:
IntelligenceUpdated
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 incorporates 10 evaluations: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1
28 of 674 models
Add model from specific provider
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
28 of 674 models
Add model from specific provider
ProprietaryOpen WeightsOpen Weights (Commercial Use Restricted)
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
Open Weights
Indicates whether the model weights are available. Models are labelled as 'Commercial Use Restricted' if commercial use is limited by conditions, and as 'Non-commercial' if the license prohibits commercial use.
Measures the performance of models on specific capabilities and industries
Incorporates 7 evaluations: AA-Omniscience, GDPval-AA v2.1, AA-Briefcase v1.1, Humanity's Last Exam, AutomationBench-AA, AA-LCR v1.1, GDP.pdf · Higher is better
28 of 171 models
Add model from specific provider
Benchmarks
Intelligence Evaluations
Intelligence evaluations measured independently by Artificial Analysis · Higher is better
CodingAgenticTool UsePrivate DatasetUser InteractionFinanceMedicalLegalIntelligence IndexLong ContextMultimodalInstruction FollowingFaithfulnessWritingBusinessSee more
18 of 26 evaluations28 of 674 models
Add model from specific provider
AA-Briefcase v1.1Updated
Agentic knowledge work, (Elo-500)/2000
GDPval-AA v2.1Updated
Agentic real-world work tasks, (Elo-500)/2000
AutomationBench-AAUpdated
Agentic SaaS workflows
Terminal-Bench 4.0New
Agentic coding & terminal use
Humanity's Last Exam
Reasoning & knowledge
GDP.pdfNew
Professional document reasoning, All-pass
AA-Omniscience Non-Hallucination Rate
1 - hallucination rate
Harvey LAB-AA
Legal agentic work, criterion pass rate
EnterpriseOps-Gym-AA
Agentic business operations
AA-AnalystAgent
Quantitative analysis on spreadsheets & documents
ITBench-AA
Kubernetes incident root-cause analysis
MLCR-AANew
Medical long context reasoning
Intelligence Evaluation Relevance
While model intelligence generally translates across use cases, specific evaluations may be more relevant for certain use cases.
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
28 of 192 models
Add model from specific provider
AA-Briefcase Elo
AA-Briefcase Elo is a combined metric that aggregates analytical quality Elo, presentation Elo, and rubric pass rate, with rubric performance converted into Elo via synthetic head-to-head matches. Elo and 95% confidence interval bounds are clamped at 0.
28 of 549 models
Add model from specific provider
AA-Omniscience Index
AA-Omniscience Index (higher is better) measures knowledge reliability and hallucination. It rewards correct answers, penalizes hallucinations, and has no penalty for refusing to answer. Scores range from -100 to 100, where 0 means as many correct as incorrect answers, and negative scores mean more incorrect than correct.
28 of 674 models
Most attractive quadrant
Pareto line
InceptionXiaomiOpenAIAnthropicSpaceXAIGoogleMetaZ AIDeepSeekAlibabaMiniMaxMultiverse ComputingTencent
Cost per Intelligence Index Task
Weighted average cost per Intelligence Index task. Each evaluation’s cost is calculated from input, cache hit, cache write, reasoning, and answer token prices, divided by task count, and weighted by its Intelligence Index weight.
Artificial Analysis Intelligence Index
Artificial Analysis Intelligence Index v4.3.2 includes: AA-Briefcase v1.1, GDPval-AA v2.1, AutomationBench-AA, Terminal-Bench 4.0, SciCode, Humanity's Last Exam, GDP.pdf, CritPt, AA-Omniscience, AA-LCR v1.1. See Intelligence Index methodology for further details, including a breakdown of each evaluation and how we run them.
28 of 674 models
AnswerReasoning
Output Tokens per Intelligence Index Task
The number of tokens required per Intelligence Index task. This is calculated by multiplying the output tokens per eval by the relative weights of each benchmark in the Intelligence Index, then dividing by task count (excluding repeats).
28 of 674 models
AnswerReasoningCache WriteCache HitInput
Cost per Intelligence Index Task
Weighted average cost per Intelligence Index task. Each evaluation’s cost is calculated from input, cache hit, cache write, reasoning, and answer token prices, divided by task count, and weighted by its Intelligence Index weight.
28 of 674 models
Add model from specific provider
OutputReasoningCache WriteCache ReadNon-Cache Input
Cost to Run Artificial Analysis Intelligence Index
The cost to run the evaluations in the Artificial Analysis Intelligence Index, calculated using the model's input, cache hit, cache write, reasoning, and answer token prices and the number of tokens used across evaluations (excluding repeats).
28 of 674 models
Add model from specific provider
Cache HitInputOutput
Cache Hit
Price per token for cached prompts (previously processed), typically offering a significant discount compared to regular input price, represented as USD per million tokens. The values shown here are the cache hit price; cache write and cache storage are billed separately and vary by provider — see "Cache pricing by provider" for detail.
4 more notes
Context Window
Context WindowIntelligence Index vs. Context Window
Context Window
Context window: tokens limit · Higher is better
28 of 674 models
Add model from specific provider
Context Window for RAG
Larger context windows are relevant to RAG (Retrieval Augmented Generation) LLM workflows which typically involve reasoning and information retrieval of large amounts of data.
Context Window
Maximum number of combined input & output tokens. Output tokens commonly have a significantly lower limit (varied by model).
Measured by Output Speed (tokens per second)
28 of 674 models
Add model from specific provider
Output Speed
Tokens per second received while the model is generating tokens (ie. after first chunk has been received from the API for models which support streaming).
Model Performance Representation
Figures represent performance of the model's first-party API or the median across providers where a first-party API is not available.
28 of 674 models
Time per Intelligence Index Task
The weighted average time (seconds) per Artificial Analysis Intelligence Index task. This is calculated by dividing output tokens per task by output speed, weighted by the relative weights of each benchmark in the Intelligence Index.
Measured by Time (seconds) to First Token
28 of 674 models
Add model from specific provider
Thinking (reasoning models, when applicable)Input processing
Time to First Answer Token
Time to first answer token received, in seconds, after API request sent. For reasoning models, this includes the 'thinking' time of the model before providing an answer. For models which do not support streaming, this represents time to receive the completion.
Seconds to output 500 tokens, calculated based on time to first token, 'thinking' time for reasoning models, and output speed
28 of 674 models
Add model from specific provider
Outputting time'Thinking' time (reasoning models)Input processing time
End-to-End Response Time
Seconds to receive a 500 token response. Key components:
Model Performance Representation
Figures represent performance of the model's first-party API or the median across providers where a first-party API is not available.
Mercury 2.5 was released on September 8, 2026.
Mercury 2.5 scores 12 on the Artificial Analysis Intelligence Index, placing it below average among other reasoning models in a similar price tier (median: 13).
Mercury 2.5 generates output at 770.4 tokens per second (based on Inception's API), which is well above average compared to other reasoning models in a similar price tier (median: 108.6 t/s).
Mercury 2.5 has a time to first token (TTFT) of 2.95s (based on Inception's API), which is somewhat higher than average compared to other reasoning models in a similar price tier (median: 2.23s).
Mercury 2.5 costs $0.25 per 1M input tokens (better than average, median: $0.25) and $0.75 per 1M output tokens (better than average, median: $0.90), based on Inception's API.
Mercury 2.5 costs $0.25 per 1M input tokens and $0.75 per 1M output tokens (based on Inception's API). For a blended rate (7:2:1 cache hit/input/output ratio), this is $0.14 per 1M tokens. Pricing may vary by provider. Compare provider pricing
When evaluated on the Intelligence Index, Mercury 2.5 generated 35M output tokens, which is better than average compared to other reasoning models in a similar price tier (median: 85M).
Yes, Mercury 2.5 is a reasoning model. It uses extended thinking or chain-of-thought reasoning to work through complex problems before providing an answer.
No, Mercury 2.5 does not support image input. It can only process text.
No, Mercury 2.5 is not multimodal. It only supports text input.
Mercury 2.5 has a context window of 260k tokens. This determines how much text and conversation history the model can process in a single request.
No, Mercury 2.5 is proprietary. The model weights are not publicly available
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。