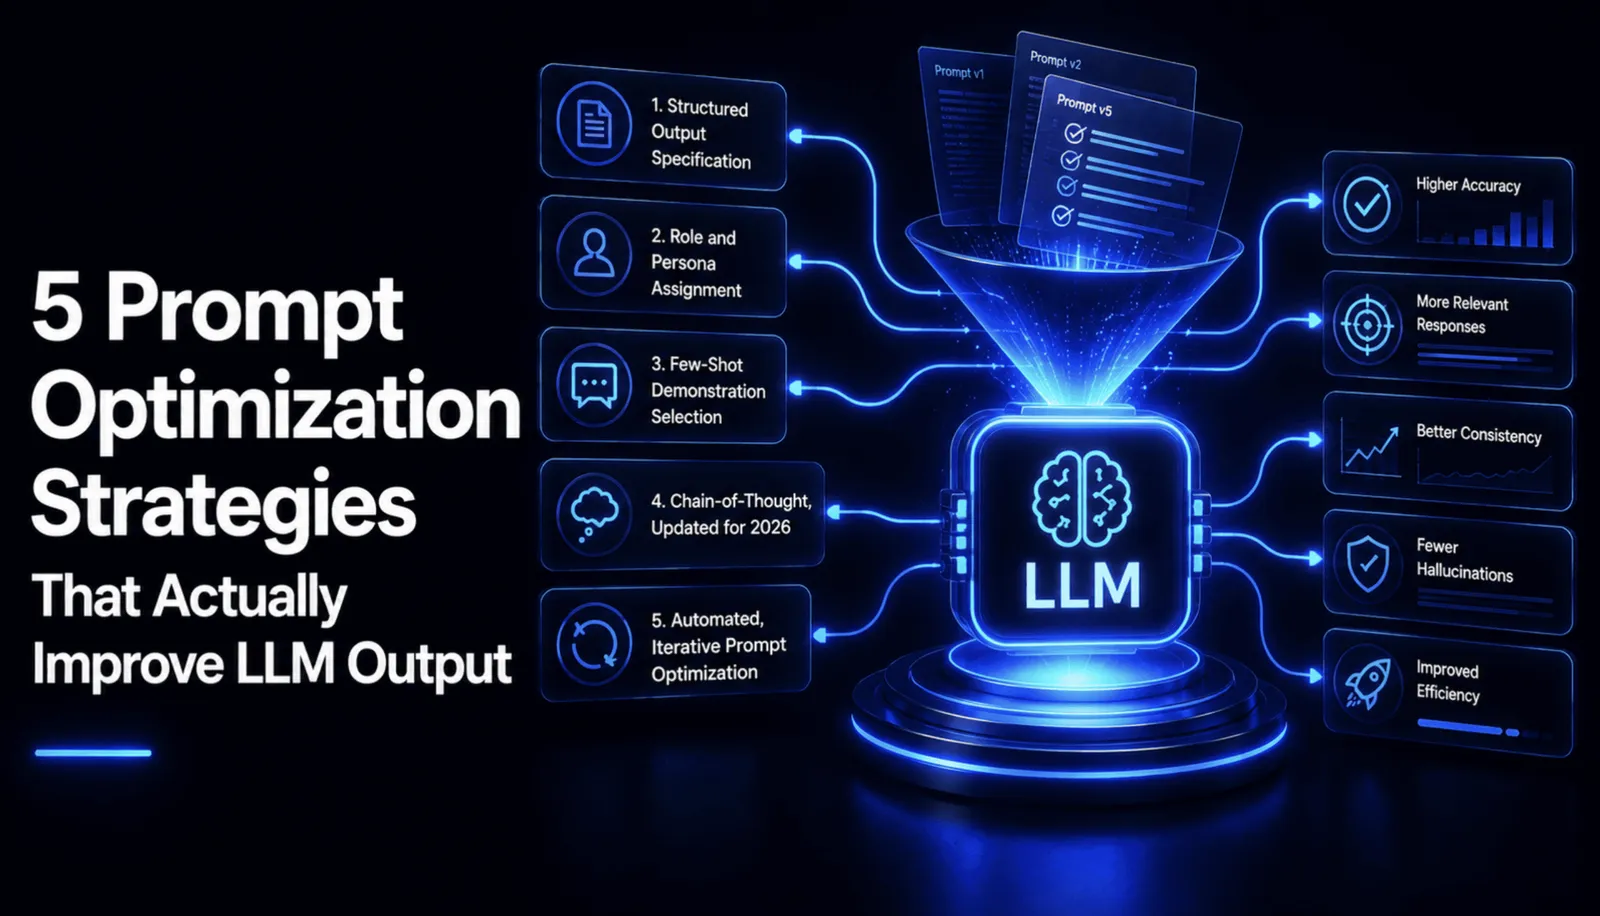
5 Prompt Optimization Strategies That Actually Improve LLM Output
This article covers five prompt optimization strategies such as: prompt optimization, prompt engineering, LLM output quality, few-shot prompting, chain-of-thought, structured outputs.
以下正文同步自 KDnuggets,版权归原站所有,已转换为易读排版。
You are a meticulous executive assistant who has sat through hundreds of these meetings. You know that people change their minds mid-sentence, that assignments get reassigned, and that a good notes-taker never guesses at an owner who wasn't actually confirmed. Extract the action items from this meeting transcript.
Run against the transcript above, the generic instruction has no reason to watch specifically for the mid-conversation reassignment or the unresolved triage owner, since nothing in the prompt flagged those as things to watch for. The role-based version primes the model to expect exactly that kind of ambiguity before it starts reading, which matters most on transcripts messy enough that a careless first pass would miss it — precisely the kind this article is using.
A well-known synthesis of prompt-optimization research found something worth taking seriously: demonstration selection strategies can have a greater impact on output quality than instruction wording itself, and combining the two deliberately outperforms either alone. The detail most people miss is that it's not "add a few examples" — it's which examples. A set that's accidentally three variations on the same pattern teaches the model almost nothing it didn't already know.
from sklearn.feature_extraction.text import TfidfVectorizer from sklearn.metrics.pairwise import cosine_similarity
def select_diverse_examples(candidates: list[str], k: int = 3) -> list[str]: """Greedily picks k examples that are maximally dissimilar from each other, so the few-shot set covers different patterns instead of k near-duplicates of the same case.""" vectorizer = TfidfVectorizer(stop_words="english") vectors = vectorizer.fit_transform(candidates) similarity_matrix = cosine_similarity(vectors)
selected_idx = [0] while len(selected_idx)
I ran this against a candidate pool that deliberately included a near-duplicate pair — two examples both following the identical "owner confirms a deadline, high priority" pattern, placed early in the list. Naively grabbing the first three candidates pulled in both near-duplicates, wasting two of three demonstration slots on essentially the same lesson. The diversity-aware selection correctly caught the duplicate pair (the two most similar examples in the whole set) and swapped one out for a genuinely different pattern instead. Applied to the transcript task specifically, that means a few-shot set worth building should include one example with a confirmed owner, one with an explicitly unresolved owner, and one where an item gets merged into an earlier one — three different real patterns, not three restatements of the easy case.
Chain-of-thought prompting — asking a model to reason step by step before answering — remains genuinely useful, but its role has shifted. Frontier models now reason natively, meaning explicitly requesting step-by-step reasoning matters less for models that already do it internally than it did in 2022 and 2023, when the original chain-of-thought research first showed dramatic gains on models that didn't. Where it still earns its cost is on genuinely ambiguous cases — and this transcript has one: the mobile-review reassignment.
Without reasoning prompted: a model can easily latch onto the first mention — "I can do that" from Priya — and miss the correction two lines later.
With reasoning prompted: "Before extracting each action item, first trace who was assigned across the whole conversation, since assignments sometimes change mid-discussion. Only report the final, confirmed owner."
This forces the model to hold the full exchange in view rather than pattern-matching on the first plausible-sounding assignment, and it's specifically the kind of ambiguity where reasoning-before-answering visibly changes the result rather than just adding latency for no benefit.
Worth knowing about for cost-conscious use: a newer variant called Chain of Draft asks the model to draft each reasoning step in roughly five words instead of full sentences, and research shows it can match chain-of-thought accuracy while using as little as 7.6% of the reasoning tokens — a genuinely useful option once you've confirmed reasoning helps and are optimizing for cost on top of that.
The most advanced strategy on this list, and the one that turns "which fix do I need" from a guess into something you can actually search for and measure. Rather than hand-tuning a prompt by feel, score candidate prompts against real test cases and let a search process find the fixes that matter.
CANDIDATE_FRAGMENTS = [ "If an assignment changes mid-conversation, use the FINAL owner, not the first one mentioned.", "If a task gets folded into an existing item later in the conversation, merge it, don't create a duplicate.", "If no owner is explicitly assigned, use 'unassigned' rather than guessing.", "Do not include general discussion or decisions that aren't concrete action items.", "Match each due date to what was actually said, not an assumed default.", ]
def composite_score(extracted: list[dict], ground_truth: list[dict]) -> float: """Recall alone misses real quality problems: a wrong owner or a fabricated extra item both matter and both get penalized here.""" result = score_extraction(extracted, ground_truth) fabrication_penalty = result["fabricated_items"] * 0.15 return max(0.0, (result["recall"] * 0.5 + result["owner_accuracy"] * 0.5) - fabrication_penalty)
def optimize(n_iterations: int = 6) -> tuple[PromptCandidate, list]: """Hill-climbing: at each step, try adding one unused instruction fragment, keep whichever addition improves the score most.""" current = PromptCandidate(instructions=[]) current.score = composite_score(simulate_extraction_quality(current), GROUND_TRUTH_ACTION_ITEMS) history = [(current.render(), current.score)] remaining = list(CANDIDATE_FRAGMENTS)
for _ in range(n_iterations): if not remaining or current.score >= 1.0: break best_candidate, best_score = None, current.score for fragment in remaining: trial = PromptCandidate(instructions=current.instructions + [fragment]) trial_score = composite_score(simulate_extraction_quality(trial), GROUND_TRUTH_ACTION_ITEMS) if trial_score > best_score: best_candidate, best_score = trial, trial_score if best_candidate is None: break current = best_candidate current.score = best_score remaining.remove(current.instructions[-1]) history.append((current.render(), current.score)) return current, history
What this does: this is the same underlying mechanism behind production automated prompt-optimization tools — generate variations, score each against real cases, keep what works, repeat. The scoring step itself uses fuzzy task-matching against the transcript's known-correct answer, checking recall (did it find the real items), owner accuracy (did it attribute them correctly), and a penalty for fabricated items that don't correspond to anything real — not just "did it return valid JSON."
I ran the full search against this exact transcript, starting from a bare "extract action items as JSON" instruction with none of the five candidate fragments. It started at a 51.6% composite score. Three iterations later, it had discovered and added exactly the three fragments that mattered for this transcript's real failure modes (final-owner tracking, no-guessing-at-unassigned-items, excluding general discussion), reaching a perfect 1.000 score — without needing the other two available fragments at all. That's worth sitting with: the search found the minimum effective fix rather than throwing every available instruction at the problem, which is precisely the advantage of measuring against real cases instead of guessing which fragments sound like they should help.
Layering all five strategies onto the same transcript produces a prompt built from real, individually verified pieces rather than accumulated guesses: a defined role that primes the model to expect ambiguity, a JSON schema it must return, three deliberately diverse few-shot examples, a reasoning instruction pointed specifically at the ownership-tracking failure mode, and the three corrective fragments the automated search actually proved were necessary. Compare that against the naive "list the action items" prompt from the opening of this article, which would plausibly report Priya as the mobile-review owner, miss the tablet-breakpoint merge entirely, and either drop the support-queue triage item or invent an owner for it rather than correctly leaving it unresolved. Every one of those failures is invisible in a quick read of the output, and every one of them is a real error a team would eventually catch the hard way — in a missed deadline or a dropped ticket, not in a code review.
Five strategies, but really one underlying discipline: stop guessing at what might improve a prompt and start testing specific, individually verifiable changes against real cases. If your output looks plausible but keeps failing to parse, that's a structured-output problem — fix that first. If the same task keeps drifting depending on how the input is phrased, that's a demonstration-selection problem, not an instruction-wording one. If the model is missing something a careful human would catch on a genuinely ambiguous input, that's what reasoning prompts are actually for. And once you've hand-tuned as far as intuition can take you, that's exactly the point where an automated, scored search starts finding fixes a manual pass would miss — the same way it found the minimum three-fragment fix on this transcript instead of the five anyone might have guessed at.
正文由 探How 从来源站点 RSS 同步,内容未经改写;遇到排版缺失或需要图片、视频时请以原文为准。