资讯与观察· 大规模系统
AI 行业动态、工程实践、产品方法和社区故事。
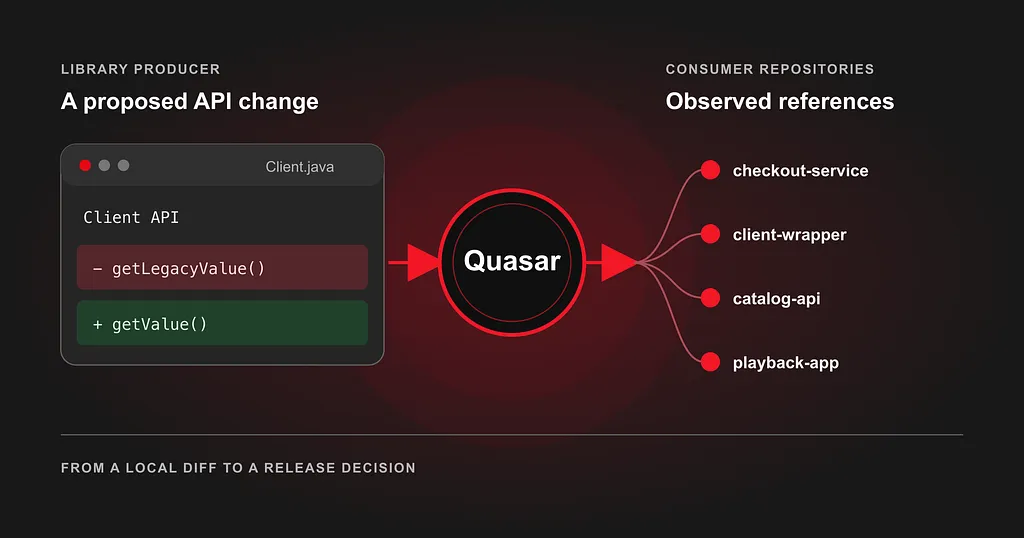
Beyond API Compatibility: Building a Tool to Measure the Blast Radius of Library Changes
By Roberto Perez Alcolea, Java Platform Team Quasar connects a proposed API change with observed references in consumer repositories, giving the producer evidence for a release decision At Netflix, shared Java libraries…
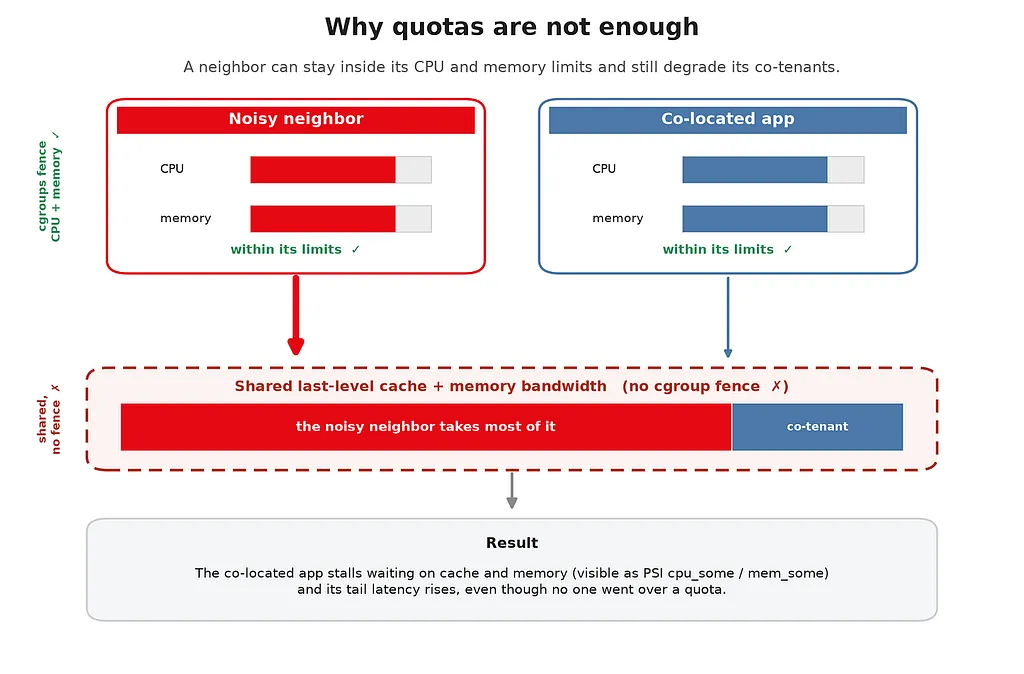
Single-tenant Titus: VM-level isolation on a multi-tenant container platform
Samartha Chandrashekar & Nick Parker You click play on a Friday night, and in the second that follows, dozens of services answer in milliseconds. Most of them run on Titus, our internal container platform. Titus is, in …
30 分钟 · Netflix TechBlog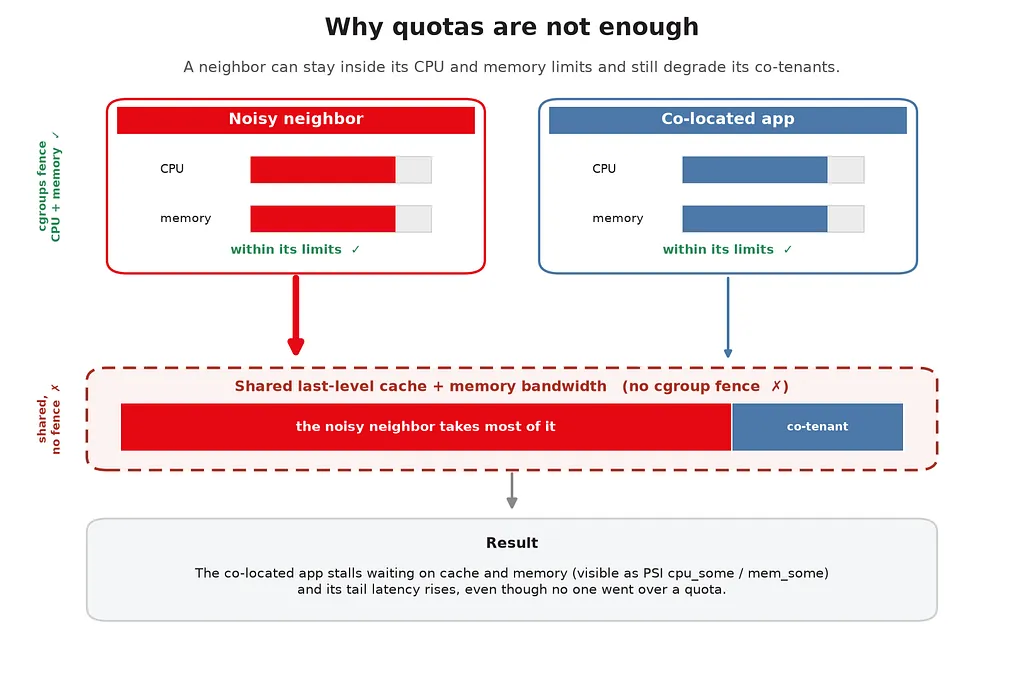
Single-tenant Titus: VM-level isolation on a multi-tenant container platform
Samartha Chandrashekar & Nick Parker You click play on a Friday night, and in the second that follows, dozens of services answer in milliseconds. Most of them run on Titus, our internal container platform. Titus is, in …
30 分钟 · Netflix TechBlogLATEST STORIES
最新内容
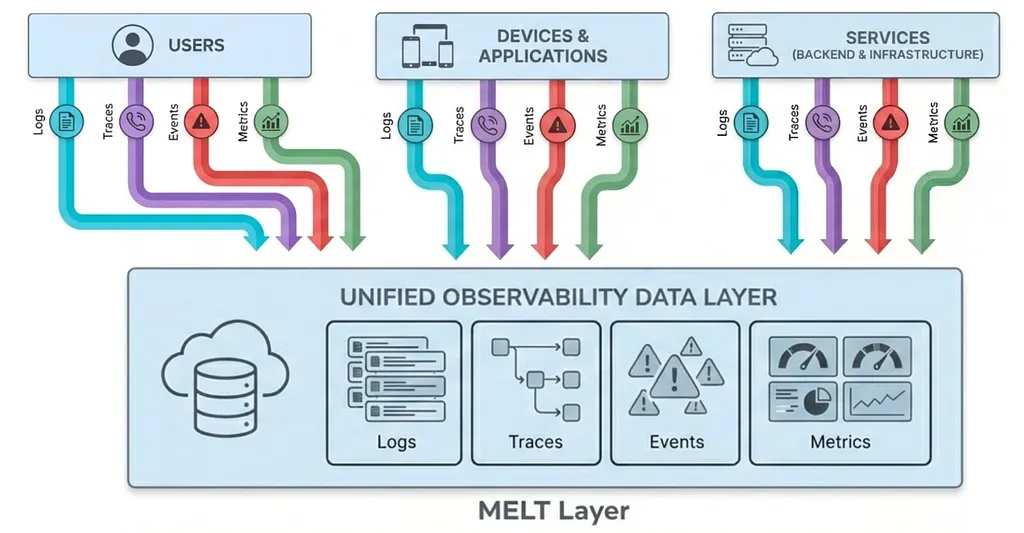
Ontology-Driven Observability: Building an End-to-End Knowledge Graph at Netflix Scale精选导读
Prasanna Vijayanathan, Renzo Sanchez-Silva When Jake Paul and Mike Tyson stepped into the ring in November 2024, we delivered the fight to roughly 65 million concurrent streams. On an ordinary day our infrastructure tak…
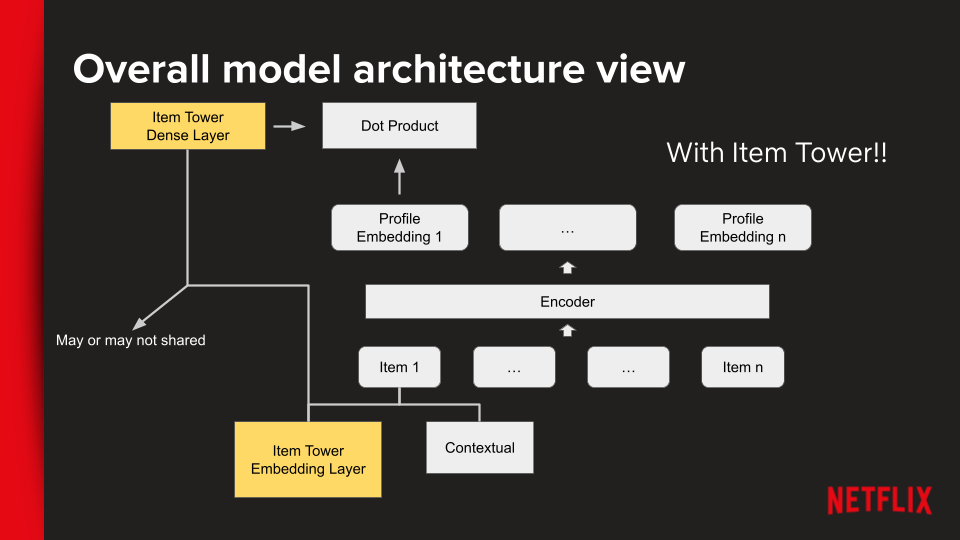
Integrating Netflix’s Foundation Model into Personalization applications精选导读
Authors: Divya Gadde, Ko-Jen Hsiao, Dhaval Patel and Moumita Bhattacharya The motivation for building the Netflix Foundation Model for personalization was laid out in this previous blog post. The Netflix homepage is pow…
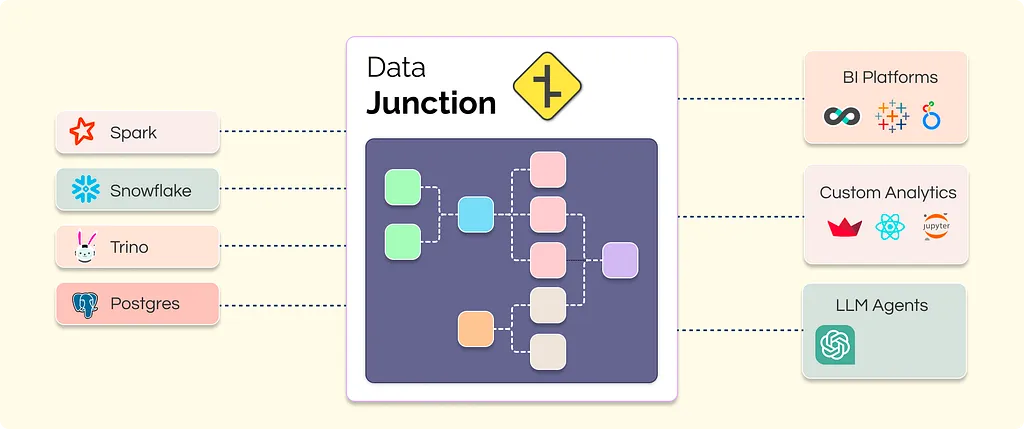
DataJunction as Netflix’s answer to the missing piece of the modern data stack精选导读
by Olek Gorajek, Samuel Redai, Yian Shang ### Intro Our Netflix journey from data to dashboards, particularly within the space of the experimentation platform, always presented a unique set of challenges. This blog post…
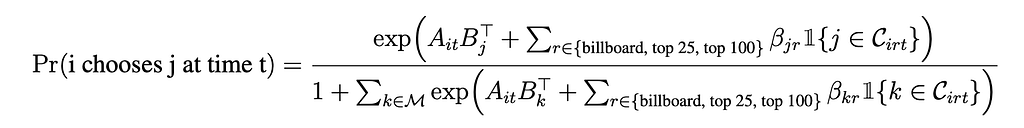
Measuring the Impact of Personalized Recommendations精选导读
By Kevin Zielnicki, Guy Aridor, Aurélien Bibaut, Allen Tran, Winston Chou, and Nathan Kallus ### Introduction Personalization is everywhere on the internet. It shapes the products we discover, the stories we read, the m…
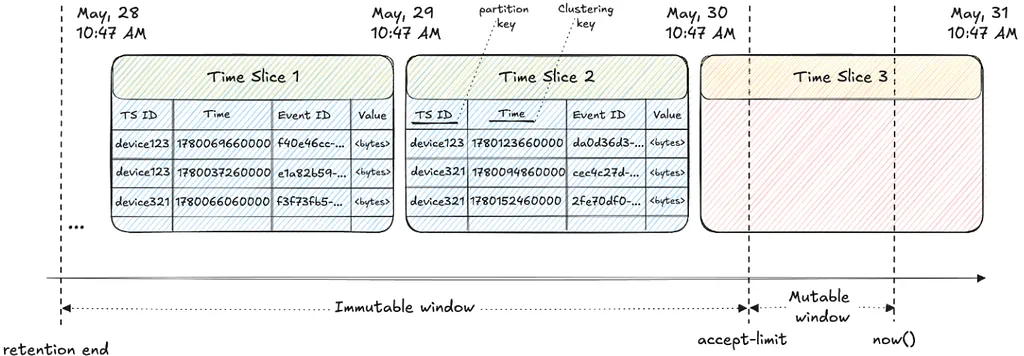
TimeSeries Tiered Storage Journey: Kafka/Flink Streams to Native Cassandra Cold Reads精选导读
By Oleksii Tkachuk, Rajiv Shringi, Chris Lohfink, Abe Ratnofsky, Kartik Sathyanarayanan ### Introduction In an earlier post, we introduced the TimeSeries Abstraction, our high-throughput, low-latency platform designed t…
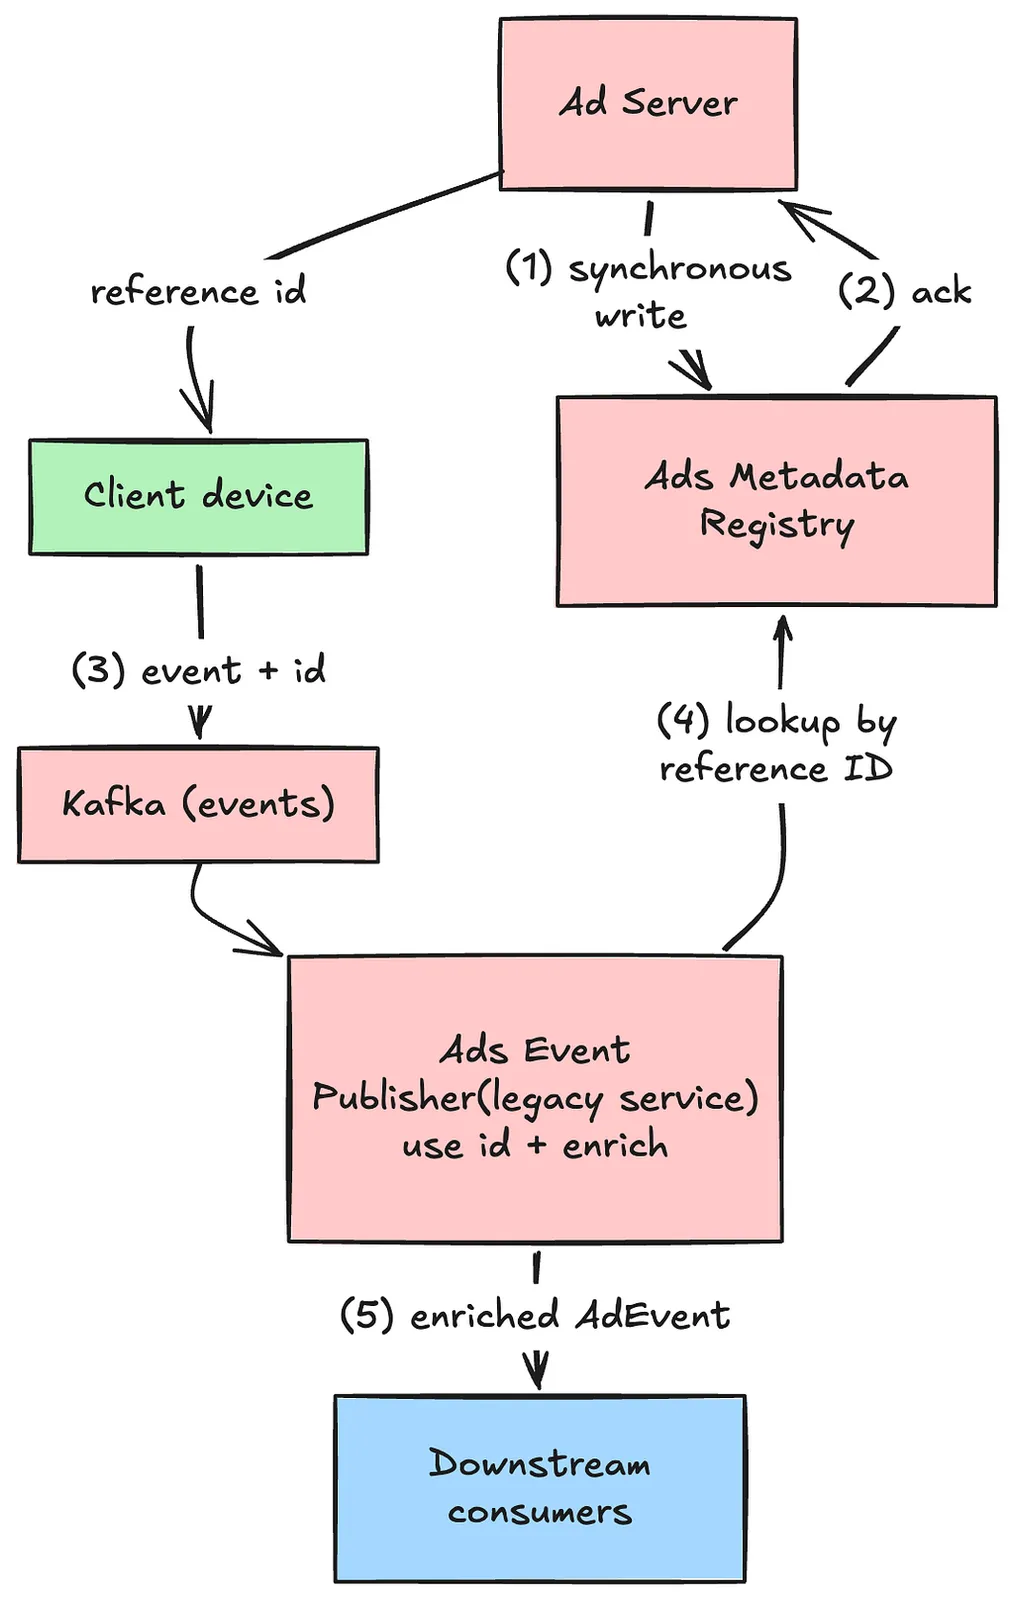
Behind the Scenes: Evolving Netflix’s Ads Event Pipeline for Live — Part II精选导读
By Yogesh Nagarur ### Introduction In Part 1 of this series, we shared how Netflix built the Ads Event pipeline and approached it as a system design problem: replacing fragmented pipelines with a centralized collection,…
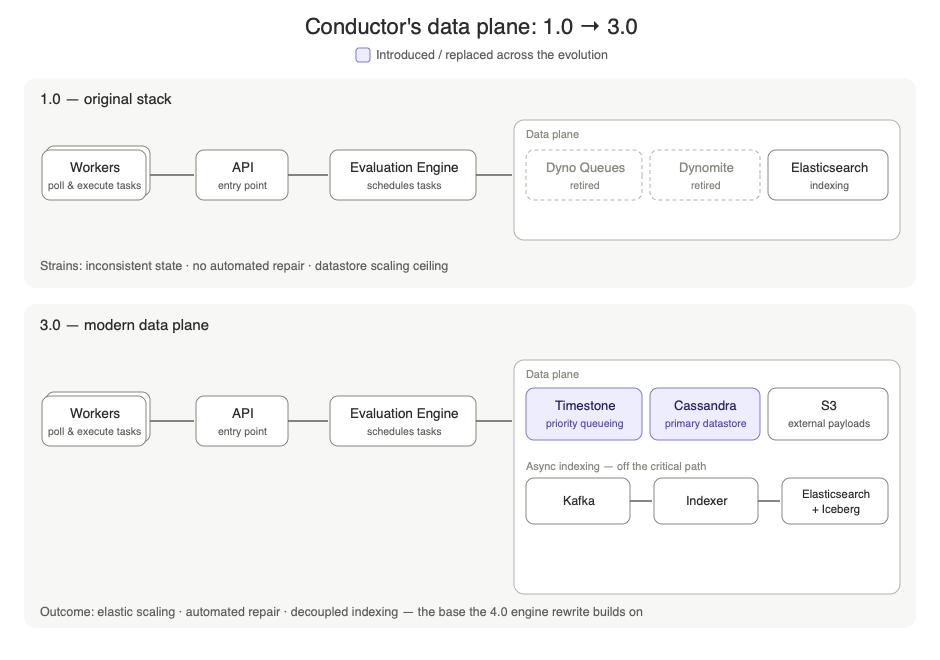
Netflix Conductor: The Next Chapter精选导读
### Netflix Conductor : The Next Chapter by Aravindan Ramkumar on behalf of the Conductor team Conductor is the workflow orchestration engine Netflix uses to stitch micro-services into reliable, observable business proc…
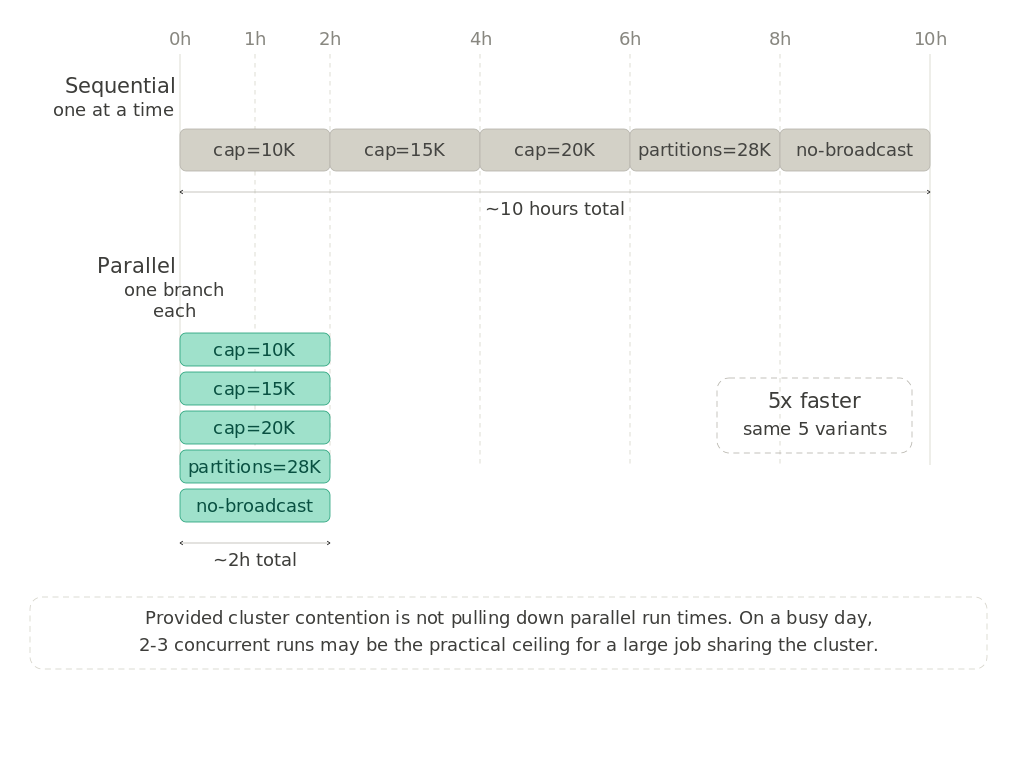
Running Apache Spark experiments in my sleep (and on a plane)精选导读
By Prashanth Gedde Narayanaswamy As one of Netflix’s largest and critical data pipelines, member-sessionizer consolidates tens of billions of hourly client events, encompassing user taps, playbacks, and engagement signa…
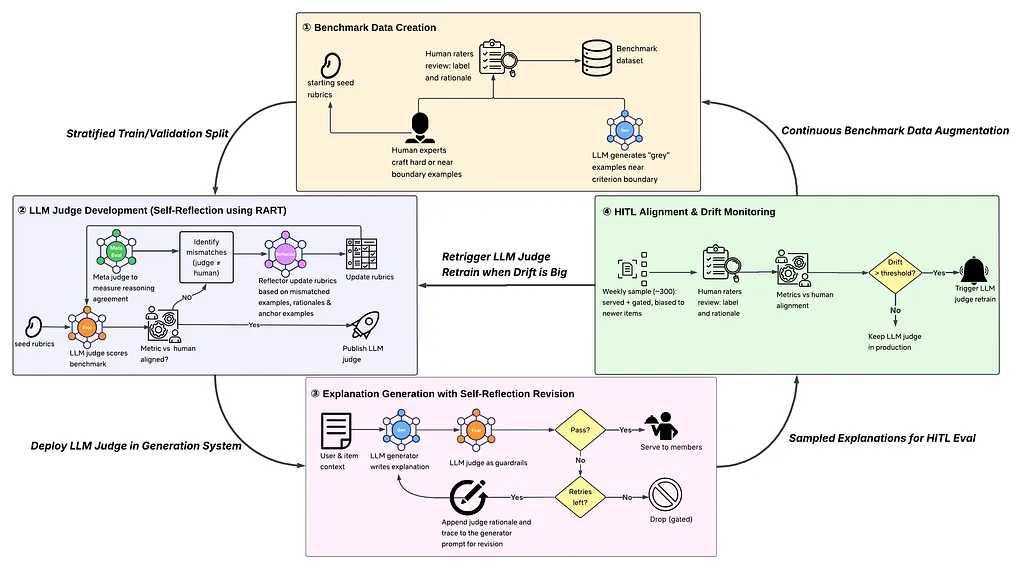
The Lifecycle of LLM-as-a-Judge: Building, Aligning, and Monitoring at scale精选导读
By Emma Yanyang Kong, JJ Tan, Ishan Gupta, Lars Olds, Claire Campbell, David Fagnan, Ratna Kavuri, Rohan Gosain, Veli Balin, Minsu Jang, Louis Garcia ### Introduction Any team generating text with an LLM at scale hits t…